Before you download an AI model, read its label, called a model card, the way you would read the box of a new appliance. Check who made it, what you are allowed to do with it, whether it is built for chatting, and whether the file is small enough for your computer. Skip the big score tables the first time through.
Say your laptop has 16 gigabytes (GB) of working memory, called random access memory (RAM), and 48 GB of free disk space. You open the page for a big model on Hugging Face, a popular site for sharing AI models. A bright badge sits next to an official-looking company name, and you take that as a green light. The file list shows one download at 42.5 GB, and you click it. On cafe Wi-Fi the download takes most of an hour, and then your Mac warns that only 5.5 GB of disk is left. The app you use to run models refuses to load the file. It sits on your disk doing nothing, because 16 GB of memory was never going to hold it.
This post teaches a 90-second check that works on any model page on Hugging Face, such as the ones for Llama or Qwen models. Model names change every few months, but the check does not.
Five fields, then stop
Treat the Hugging Face model card as a shopping sheet. On the first pass, check only the publisher, the license label, whether the name says chat or base, the file size compared with your memory, and one sentence about intended use or limits. Popularity counts and the big evaluation table can wait until you have those five answers.
The card is a spec sheet
On the Hub, each model lives in a repository (the project’s folder of files on the site), and the model card is that folder’s README.md text file. Hugging Face’s docs split it into two layers. A block of settings at the top, written in a format called YAML (a simple settings format), feeds the small labels in the header, such as license, tags, pipeline_tag, datasets, base_model, and library (a set of ready-made code other programs use). The Markdown (plain text with simple formatting marks) text under it is the human part, which says what the model is, who built it, how to use it, and what it gets wrong. The two layers overlap. You can read the labels in 20 seconds and still miss the one file that wrecks a 16 GB machine.
The Hub template still follows a 2018 research paper on model cards by Mitchell and coauthors. Its sections are Model Details, Uses, Bias / Risks / Limitations, Training, Evaluation, and Technical Specs. You are not writing that paper, because you are shopping. You want to know who made the model, what job it was built for, what it will not do, and whether it physically fits your machine. Popularity counts and a wall of benchmark (a standard test used to score models) rows can wait until those four questions have answers.
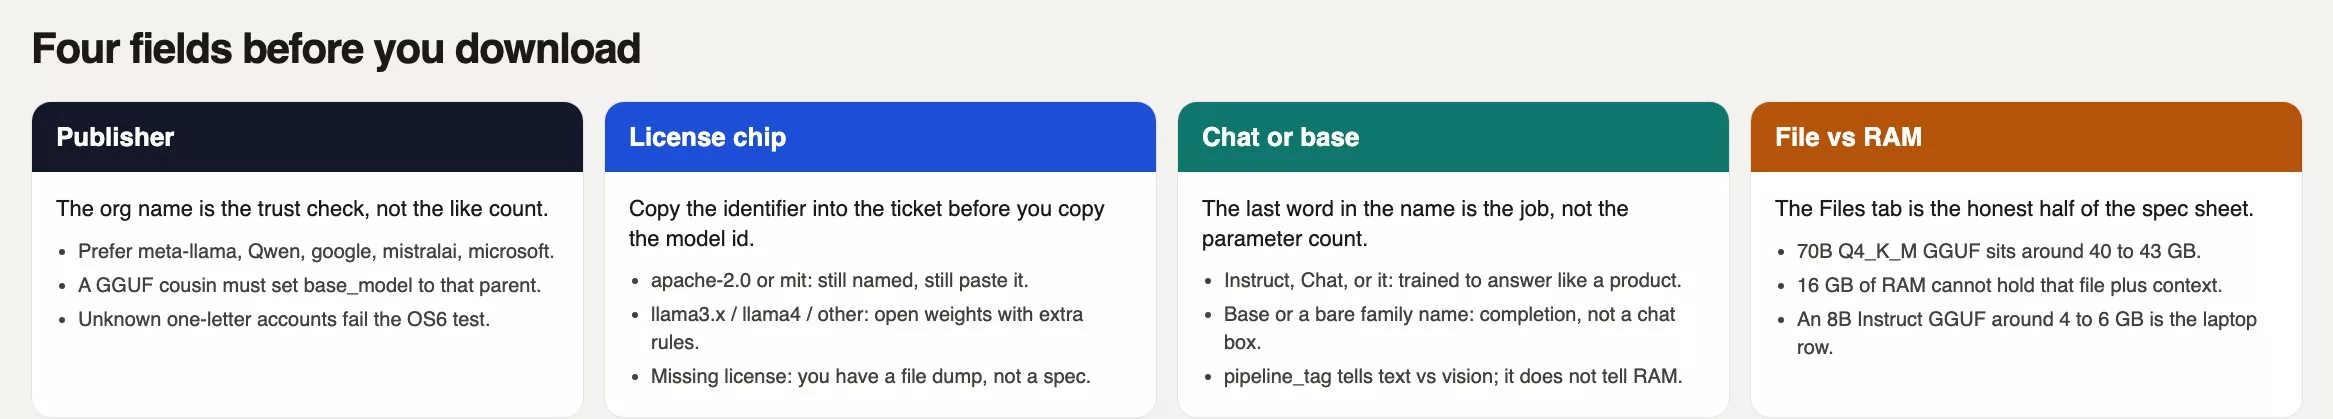
In the opening story, you never got to intended use and never opened Limitations. You saw a pretty first badge and a 70B in the title. That is how a spec sheet turns into a 42.5 GB souvenir.
Read the header, ignore the sparkle
Who published it
The organization name is your first trust check. Names like meta-llama, Qwen, google, mistralai, and microsoft belong to the families that the rest of the Hub copies. A stranger’s account can still publish a useful GGUF (GPT-Generated Unified Format, a common single-file format for running models locally) when its base_model field points at one of those parents. The guide to safety and random downloads already said not to download random weights (the learned numbers that make up the model). If you see a one-letter account, a brand-new organization, no license, and no parent model, close the tab.
Official Llama repositories are often gated. You click Agree, the terms appear, and only then do the files open up. It is easy to sleepwalk through that step. Read the organization name, then read what you agreed to. Follower counts measure popularity, and they say nothing about how much memory you have.
The license label
The license identifier is the label in the header. When the docs were checked in August 2026, many Qwen-class cards still showed apache-2.0 or mit. Meta’s 70B-class Instruct repositories showed a Llama Community identifier such as llama3.3, or a later llama4-style label if that line is the flagship when you read this. Apache-style terms allow ordinary software use. Llama’s community licenses add rules on acceptable use and attribution, and they add a monthly-active-user threshold that can force you to ask Meta for a separate grant. The open-weight versus open-source guide covers the legal side in depth, while this post only covers the label. If the label is missing, you have a file dump and not a licensed model.
Rule of thumb: The first badge is decoration. The organization name and the license label are the spec. If those two disagree with the story in your head, believe the label.
Chat, base, and the cousin repository
Look at the last word in the model name before you look at the parameter count. Instruct, Chat, or it usually means the weights were trained to answer like a product, with a system prompt (standing instructions), a user message, and an assistant reply. A Base model, which is sometimes just the family name with no suffix, is a completion model. It continues whatever text you give it, so it will not reliably handle “summarize this PDF” the way ChatGPT does. Desktop apps can wrap a base model in a chat template and hide the difference, but you still paid for the wrong kind of model.
The pipeline_tag is the Hub’s task label, and it is usually text-generation for chat weights. It picks the demo widget on the page, and it does not tell you whether the file will fit. If you wanted a text summarizer and the tag describes a vision model, you opened the wrong repository.
Then there is the cousin. Official repositories ship safetensors shards, which are large weight files meant for Python. The GGUF you drop into LM Studio (a desktop app named for the language model, or LM, it runs) or llama.cpp often lives in a different repository. Its card sets base_model to the official id and sets base_model_relation: quantized, which means it is a shrunken copy of the original. That parent link is the spec. A GGUF with no parent and a flashy 70B in the title is exactly the kind of problem the safety guide warned about. If the card has a new_version field, read that repository instead.
Context length and the Files tab
Context length is how much text the model can keep in view at once, measured in tokens, which are chunks of words and not pages. Llama 3.3 70B Instruct’s public card talked about a 128,000 token window in August 2026, and some Qwen 72B-class cards advertised the same order of magnitude. Those cards also noted that the default config.json can be shorter. Re-read the card the week you pick a model. A 128k window holds a lot of pages, and it also multiplies the memory a 70B file needs.
The Files tab is the honest half of the spec. Official 70B-class Instruct repositories list many multi-gigabyte safetensors shards, so add them up before you assume it is one file. GGUF repositories list named quantizations, which are shrunken versions that trade some quality for size. On the first pass you need the size in bytes next to the name, and the GGUF viewer can wait.
As a ballpark from public GGUF cards for Llama 3.1 and 3.3 70B Instruct, confirm the row you click. Q4_K_M runs around 42.5 GB, Q4_K_S around 40 GB, Q5_K_M around 50 GB, and Q8_0 around 75 GB. A Q2 file can dip near 26 GB, with a serious loss of quality. The guide to model size and laptop memory explains the rule that loaded weights want memory close to the file size, plus extra for context. A 42.5 GB Q4 file on a machine with 16 GB of RAM is a no. An 8B Instruct GGUF at around 4 to 6 GB is the size a laptop like yours can handle. If you need 70B-class quality on 16 GB, use a hosted service (see the guide to hosted open-model APIs) or pick a smaller Instruct file. Free disk space is not free memory.
Intended use, limitations, and the evaluation widget
Scroll past the hero badges to the Uses section. Hugging Face’s annotated template splits it into Direct Use, Downstream Use, and Out-of-Scope Use. Direct Use is what the model does without any retraining from you. Out-of-Scope is the do-not list, and it covers things like medical advice, legal advice, and scraping private data. Bias, Risks, and Limitations is the other stop you cannot skip. Labs are uneven here, because some write a real paragraph and some paste a generic disclaimer. Read whatever exists. If the card says research only, or “not evaluated for X,” that is the spec talking, and your team chat does not override it.
After that you will hit Evaluation. The Hub can draw model-index data, or newer eval-results metadata, as a widget of test scores such as the AI2 Reasoning Challenge (ARC), which uses grade-school science questions, Massive Multitask Language Understanding (MMLU), a broad multiple-choice knowledge test, and HumanEval, a coding test. On your first read, skip it. The guide to quality without benchmark theater already explained why a leaderboard row is a poor shopping list. Use those scores later, when two 8B Instruct files both fit your machine. Training Details, CO2, BibTeX, and the Glossary can wait too. If you stay in LM Studio or Ollama, the quantization (squeezing the model into a smaller file) table on the GGUF cousin’s card is the part that matches the file you will actually click.
A worked example: a 70B Instruct card
Walk through this with the cards as they looked in August 2026. Open the official meta-llama/Llama-3.3-70B-Instruct card, or the current Meta 70B-class Instruct repository if the Hub now leads with a Llama 4 line. Then run the same walk on a Qwen 72B-class Instruct card. The names move, and the fields do not.
In the header, the publisher is meta-llama. The license label is a Llama Community identifier and not Apache 2.0. The task pill says Text Generation. The name ends in Instruct, so this is the chat version and not the base. The repository is gated, so you accept Meta’s terms before you see any files. The context copy describes a 128k-class window, which you should confirm on the page you opened. None of that tells you whether the file fits in 16 GB of RAM.
On the Files tab, the official shards are the Python path. For a desktop runner, open a GGUF repository that lists this id as its base_model and find Q4_K_M. On recent public tables that row is about 42.5 GB, so your 16 GB of RAM fails right here. Stop. If you want this class of model anyway, use the hosted-API guide and a host. If you want to stay local, pick an 8B Instruct GGUF, then skim Uses and Limitations. Skip the evaluation widget until a file that fits is on the table.
| Field | Why you care | Skip for now |
|---|---|---|
| Publisher org | Who you trust; whether the random-download safety guide lets you download | Follower count, weekly downloads, likes |
| License chip | Apache-style vs Llama community vs missing | The full PDF after you have the identifier |
| Name suffix (Instruct vs Base) | Chat product vs autocomplete | Architecture diagrams and paper abstracts |
pipeline_tag | Text chat vs vision vs something else | Hobby tags that only help search |
| Files / GGUF GB | Whether 16 GB of RAM can hold it | Every exotic quant in the list |
| Context length | Will a long PDF even fit the window | YaRN recipes and rope flags |
| Intended use + limitations | What the authors say you should not do | The eval widget, CO2, BibTeX |
base_model | Is this GGUF a child of the official repo | Merge family trees |
Use this checklist as a 90-second scan while the page is open, and time yourself. If you are still reading MMLU rows, you have left the spec sheet and entered theater.
# 90-second model card scan. Do this before any download.
# Target: finish before the cafe Wi-Fi password screen times out.
# 1. Publisher (15s)
#    org in {meta-llama, Qwen, google, mistralai, microsoft, ...}
#    else: require base_model -> one of those, or stop (the random-download safety guide).
# 2. License chip (15s)
#    apache-2.0 / mit : still paste the id into the ticket.
#    llama3.x / llama4 / other : open weights, extra rules, read later.
#    missing : close the tab.
# 3. Name + pipeline_tag (15s)
#    Instruct / Chat / it : chat-shaped.
#    Base / no suffix : completion model, not your ChatGPT stand-in.
#    pipeline_tag text-generation (or the vision tag if you wanted vision).
# 4. Files tab (30s)
#    GGUF Q4_K_M (or the app’s default) : read the GB.
#    70B Q4 is ~40 to 43 GB. 16 GB RAM cannot load it.
#    8B Q4 is ~4 to 6 GB. That is the laptop row.
#    No parent base_model on a GGUF? stop.
# 5. Uses + Limitations (15s)
#    One pass. If it says research-only or not-for-X, believe it.
#    Skip the eval widget. Skip CO2. Skip BibTeX.
#    If new_version points elsewhere, scan that card instead.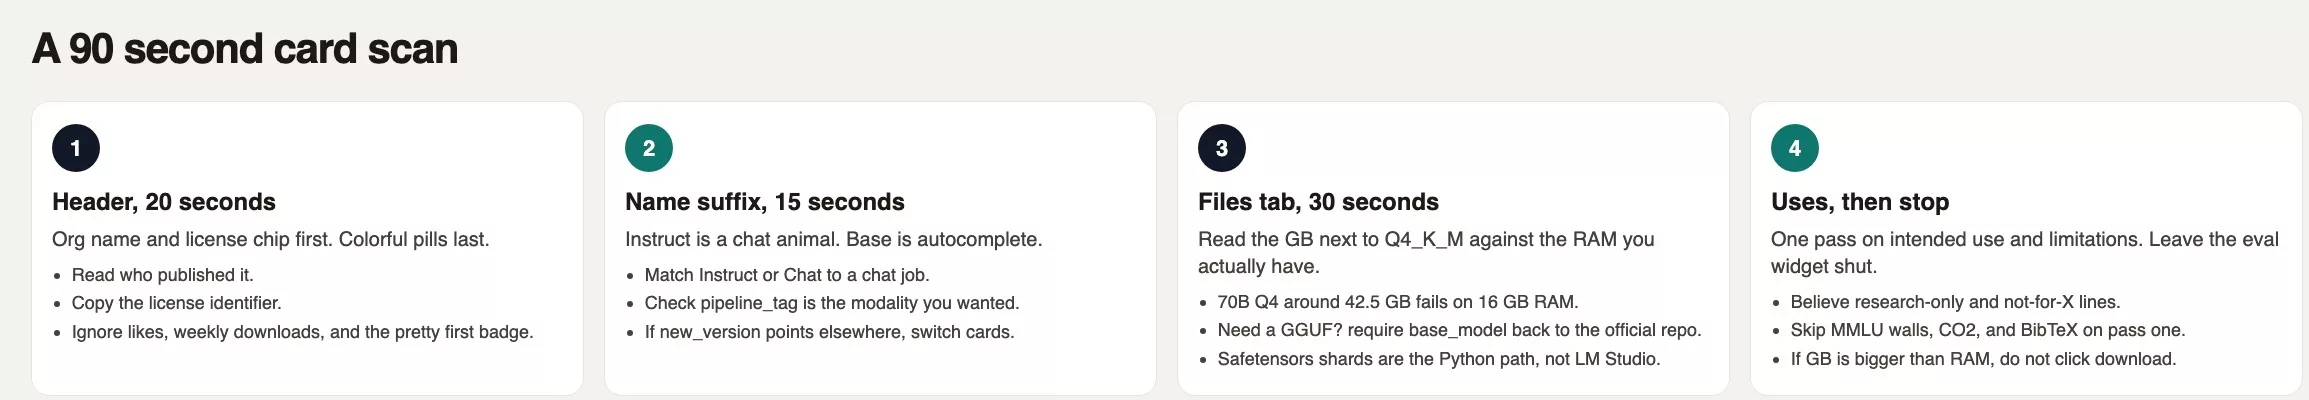
Here is what that checklist is for. In the opening story you had the pretty badge at second 3 and the download started at second 10. The scan puts 75 seconds of boring fields in front of the click, and the 42.5 GB row is the one that would have saved your disk.
The card is not the README vibe
- Trusting the first colorful pill (Text Generation, a llama logo, a download count) instead of the organization, the license, and the GB.
- Downloading the official
safetensorsshards when the app you use wants a GGUF, or the reverse. - Grabbing a Base model because the parameter count matched a blog post, then wondering why chat feels broken.
- Accepting a gated Llama license with the same reflex as a cookie banner, then telling your legal team “it’s open.”
- Reading the evaluation widget first, picking the highest MMLU score, and finding out the file is 42.5 GB after the progress bar starts.
- Ignoring
new_versionandbase_model, so you pull an old quantization of a repository the author already replaced.
Scan one card for license, size, and publisher
Open two live cards this week. Pick one official Instruct repository, either a Llama 70B-class or a Qwen 72B-class one, whichever the Hub is pushing that week. Then pick one GGUF cousin that sets base_model to that id. Run the 90-second scan on both and write five lines on a sticky note: the organization, the license id, Instruct or Base, the Q4 size in GB, and one sentence from Limitations. Then write your RAM in the corner. If the file size is larger than your RAM, you do not click.
If you need 70B-class quality, do not collect the file as a trophy. The guide to hosted open-model APIs covers Groq, Together, and Fireworks, which run big models for you. If a closed $20 chat is enough, the closed-chat guide already said so. Local practice continues in Run open models from scratch, using an 8B model that fits.
A model card you can actually use
- Treat the Hugging Face card as a spec sheet, made of YAML labels plus the README text (the page’s main description).
- Read the organization, license label, Instruct versus Base, and
pipeline_tagbefore you click anything in Files, because those four fields tell you who published the model, whether you may use it at work, and what kind it is. - On Files, compare the GGUF size in GB with your RAM. A 70B Q4 file around 40 to 43 GB does not load in 16 GB.
- Skim Uses and Limitations, and skip the evaluation widget on your first pass.
- If the file cannot fit, pick a smaller Instruct GGUF or use a hosted API, and do not fill the disk for a badge.
Your next step
Open the Hugging Face page of a model you have heard about and read it in the order from this post: organization, license label, Instruct or Base, and the file size compared with your memory. Write those four facts in a note. Reading one card carefully makes every later one much faster.
Series notes
This is Part 9 of Open-source AI explained (series code OS7c). Related: open-weight vs open-source vs free, hosted chat APIs, Run open models from scratch, privacy paste test, and Learn.
Sources
Docs and cards checked for this article. Labels move; re-open the week you download.
- Hugging Face: Model cards (metadata vs text, license,
base_model,pipeline_tag, eval widgets) - Hugging Face: Annotated model card template (Uses, limitations, evaluation sections)
- Hugging Face: Model card guidebook
- Hugging Face: GGUF on the Hub (quant names, viewer, llama.cpp / LM Studio / Ollama)
- meta-llama/Llama-3.3-70B-Instruct (worked official card, checked August 2026; confirm the current flagship)
- Meta: Llama downloads and license (community license / acceptable use, not Apache)
- Mitchell et al., 2018: Model Cards for Model Reporting (the paper the Hub template still cites)
- llama.cpp, LM Studio, and Ollama (the runners that load a GGUF)
- Model size, quantization, and will my laptop run it? and Safety and random downloads
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.