Some companies run free-to-download AI models for you. They still send your text to their own computers, and they charge by how much text goes in and out, not a flat monthly fee. Groq, Together AI, and Fireworks AI all sell this as a chat API: a web address your program sends text to and gets answers back from. None of them runs the model on your own laptop. And Groq, with a q, is a different company from Grok, the chatbot from xAI.
Say a coworker tells you to “use Groq, it’s cheap,” and you copy their small program for sending text to an AI model. You sign up, paste in your new key, and point the program at a folder of 18 long documents, asking for a long reply to each. Less than an hour later, Groq’s billing page shows $11.40, and the program is still running. You meant to try one quick question, but the program kept going through every file.
A key is not a chat seat
This post explains what these three companies sell, why paying by the amount of text behaves so differently from a $20 monthly chat plan, and how a program that runs on its own can reach $11.40 before you notice. You will learn to check what each service keeps of your data, set a spending limit, and send one small test before you send a whole folder. The charges are counted in tokens, small chunks of text of roughly a short word each. The last section covers services that pass your request to other companies for you, and why that can hide who handled it.
The prompt still leaves your machine
An open model is just a large file you are allowed to download, plus a license that says how you may use it. A hosted service has loaded some of those files onto its own machines and gives you a web address to send text to. You send a question, an answer comes back, and you pay for the text or use up a free allowance. Using an open model this way does not move your text onto your laptop. The earlier post on hosted versus local models covers where the work actually happens.
People reach for these services when a 70B-class model (one with about 70 billion adjustable settings) is too big for their computer’s memory, or RAM (your computer’s working memory). They also use them when they want to send a request from the command line (the text window where you type commands) instead of pricing out a graphics card, the chip that does the heavy math for AI, or when a teammate already has a key. Fast responses do not change the basic test. Ask yourself whether you would send this FAQ dump to that company’s support inbox. If the answer is no, do not put it in the messages field of a request.
The request format looks like OpenAI’s chat completions on purpose. Hosts copy that shape so that a program can switch to a new company by changing a single web address, the base_url, and keep working. The model name is the part that does not carry over. llama-3.3-70b-versatile was a Groq id in the August 2026 docs, Together wants a string in the form org/name, and Fireworks wants accounts/fireworks/models/.... Copy the id from the host you chose this week, because a Hugging Face repo path pasted into Groq will simply fail.
Rule of thumb: use one host, copy one model id from that host’s list this week, set a spending limit, and only then send a small test request. Customer files wait until the meter looks boring.
Three hosted services for open models
Three companies show up in nearly every thread about open-model APIs. All three rent out inference, which means they run a model for you and return the answer, but they do not sell the same catalog or the same extras. Pick one for the first week. That unexpected $11.40 charge started with two similar names living in one file.
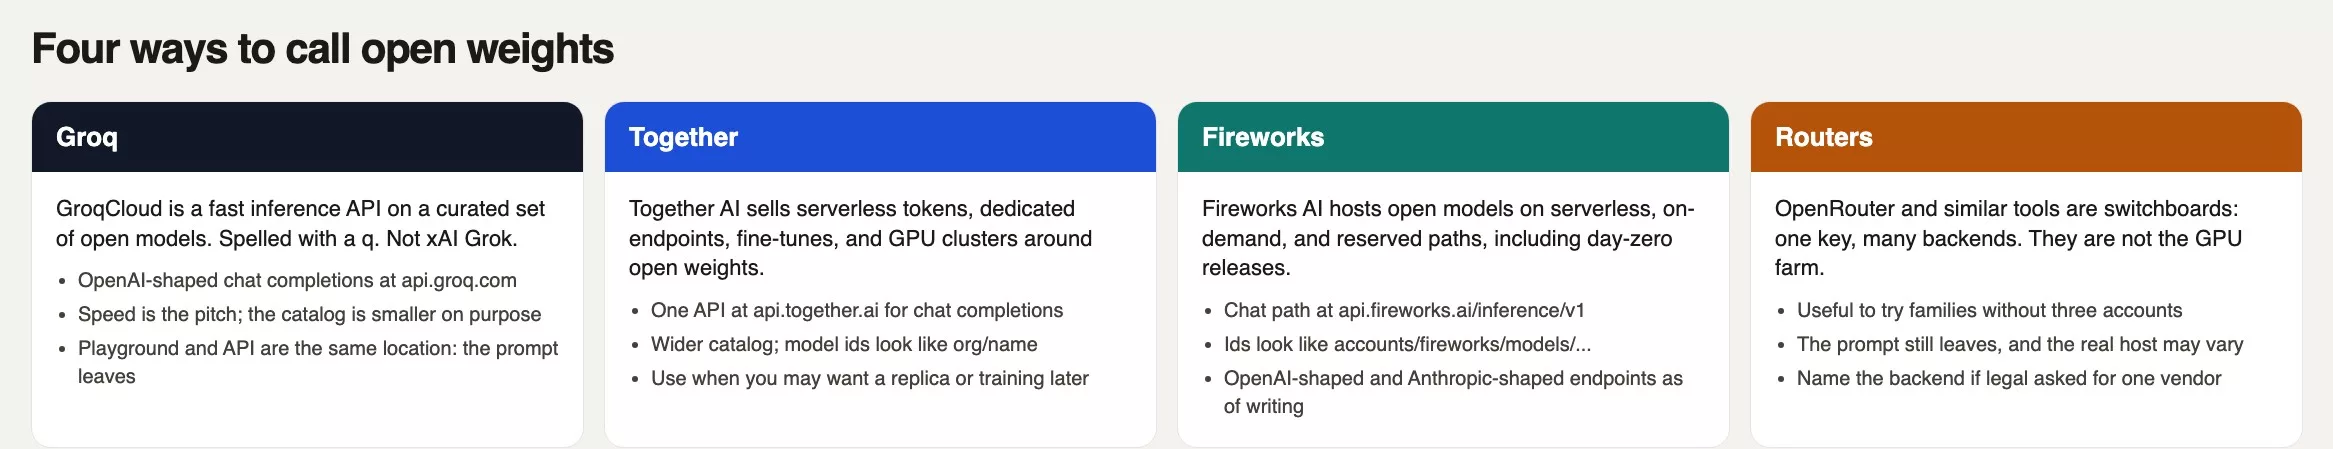
Groq runs a service called GroqCloud. Its pitch is speed on a hand-picked set of open models, and chat requests go to https://api.groq.com/openai/v1. Its quickstart still shows a first request on llama-3.3-70b-versatile, but as of October 2, 2026, Groq’s deprecations page says that model was shut down for free and developer accounts on August 16, 2026, with openai/gpt-oss-20b or openai/gpt-oss-120b as the suggested replacements. The browser playground lives in the same data centers as the API, so typing there is not local either.
Together AI sells Serverless Inference, where you pay per token and never size a machine, along with Dedicated Model Inference, fine-tuning (extra training on your own examples), and clusters of graphics chips (GPUs, the chips that do the heavy math for AI) you rent. Chat requests go to https://api.together.ai/v1, and the August 2026 quickstart used MiniMaxAI/MiniMax-M3. The serverless catalog also lists Llama, Qwen, DeepSeek, Kimi, and other families, so check the live table the morning you start. Together makes sense if you might later want a dedicated copy of a model or a fine-tune without leaving the same vendor.
Fireworks AI hosts open models in three ways: Serverless (with Priority and Fast options in August 2026), On-Demand dedicated deployments, and Reserved capacity. Its OpenAI-style chat path is https://api.fireworks.ai/inference/v1, and the company also documents a second address that follows Anthropic’s format. Model ids look like accounts/fireworks/models/deepseek-v3p1. Its model library, the catalog of models it offers, advertises support for new open releases on the day they come out, and you should copy the id from this week’s model page.
| Host | What it is | When to use |
|---|---|---|
| Groq (GroqCloud) | Fast inference API on a curated set of open models, OpenAI-shaped endpoints | You want speed on a known id and you will live with their list |
| Together AI | Serverless tokens, dedicated endpoints, fine-tunes, GPU clusters | You want a wider catalog, or a replica / training path in the same place |
| Fireworks AI | Serverless, on-demand, reserved; OpenAI-shaped and Anthropic-shaped endpoints | You want day-zero open models or a dedicated serving path |
| OpenRouter (router) | One key, many backends; it picks, fails over, or auto-routes | You want a switchboard. Name the real provider if legal asked |
Prices live on each host’s model table, and they change often. Do not copy a blog’s dollar figure into a forecast, because it may already be out of date by the time you read it. Open the live table the week you start.
Routers are switchboards
OpenRouter sits in front of many providers and gives you one OpenAI-style address, https://openrouter.ai/api/v1. You either pick a model string or send openrouter/auto and let their Auto router choose for you. Its docs in August 2026 described hundreds of models across dozens of providers, with automatic failover when one backend (the behind-the-scenes software that does the work) returns an error. So you talk to a switchboard, and the switchboard talks to a whole set of separate companies behind it.
That is handy when you want to try Qwen this morning and Llama this afternoon without keeping three dashboards open. It becomes a problem when last Tuesday’s security review named Groq and Thursday’s traffic quietly ran somewhere else. Read the response’s model field to see what actually answered. If a contract said “this vendor,” do not hide the vendor behind auto-routing. A router does not make the prompt local, because it adds one more stop on the way, so start with one named host.
Usage billing, not a seat
The ChatGPT, Claude, Gemini, and Grok apps often sell a monthly seat, either with free caps or on a plan near $20 (the post on when closed chat is simply easier covers that choice). You pay the plan price, and the product then slows you down when you use too much. A hosted open-model API works differently because it bills for usage. Input tokens have one price, output tokens have a price that is usually higher, and nothing in the bill says “$20 and we are done.”
The $11.40 charge shows the shape of that math. It is not a rate you should reuse. There were eighteen files with long prompts, and max_tokens was set to 8192 so each reply could grow into a small essay. The loop never paused between requests, and a file name made you think you were on a chat product. You never opened Groq’s live price table and never set a cap, so the console kept adding up the cost while you made coffee.
Free tiers exist, with limits on how fast you can send requests. They suit a small test request, and they do not suit faq_extracts/. As of October 2, 2026, Groq’s spend-limit docs say paid accounts can set a monthly limit under Settings, then Billing, then Limits, and that spending is tracked with a 10 to 15 minute delay, so a fast loop can overshoot it. Together and Fireworks keep their own billing screens. Find the cap before you point a script at a folder, and if you cannot find one, run a single request by hand instead.
Retention is a page you open
Hosted means the prompt leaves your machine. What the host keeps after it answers is a separate question, and you should not guess from the logo. Open the current data page the week you ship, because these policies change.
Groq’s “Your Data” docs said in August 2026 that customer inference inputs and outputs are not retained by default. Usage metadata, meaning counts and not the text itself, is always kept. Groq keeps more if you use batch jobs or fine-tuning, or if it is debugging reliability or abuse. Zero Data Retention, or ZDR, is a toggle under Data Controls that tells the host not to store your prompts and answers at all, and turning it on also switches off features that need stored state.
Fireworks documents Zero Data Retention by default for open models. It says it does not log or store prompt or generation data unless you explicitly opt in. Its Response API behaves differently when store=True, which is the default on that API, so set store=False if you use it and do not want conversation history kept. Together’s terms describe a Zero Data Retention option that keeps prompts and outputs from being stored or used for training when you turn it on. Open that page the morning you create the key. A promise that a vendor will not train on your data without opt-in is a different sentence from a promise to delete the prompt as soon as the request ends. The privacy checklist for running AI yourself covers how to choose.
A worked example: $11.40 before standup
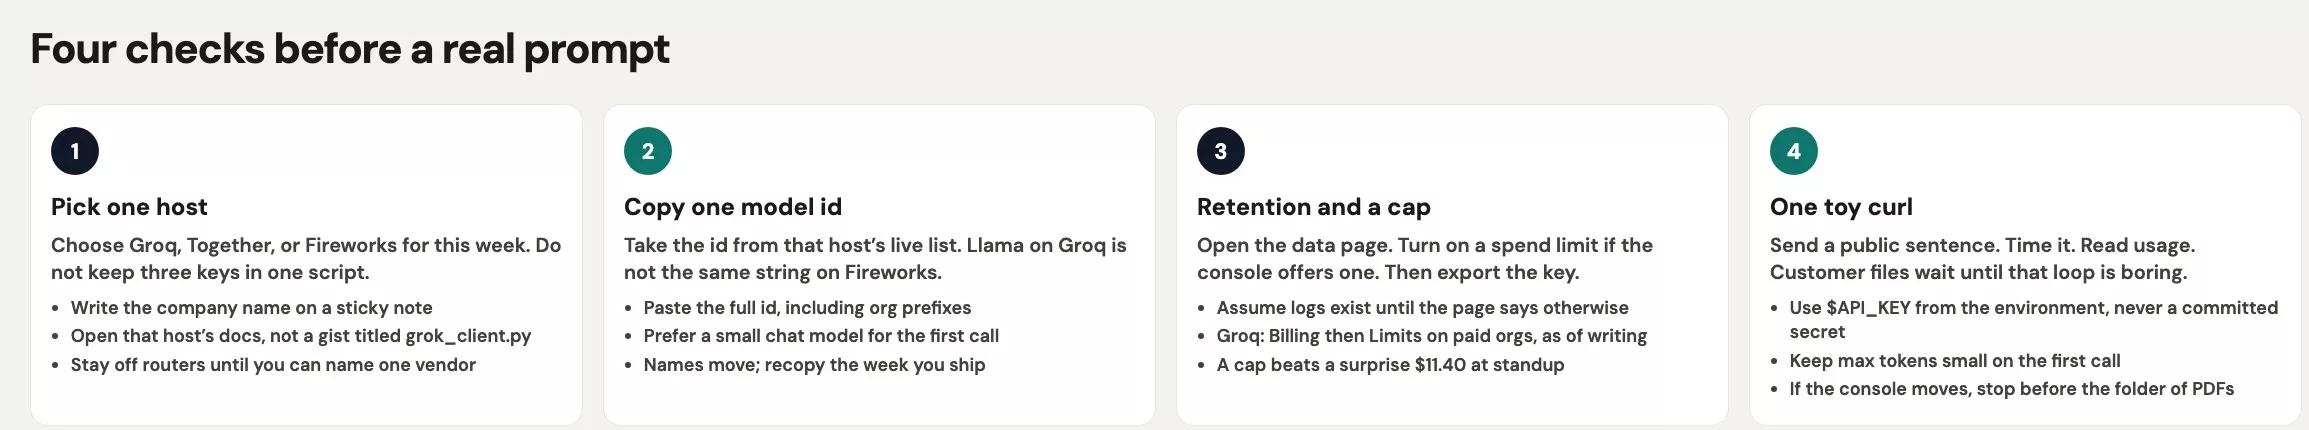
Here is the safer version of that morning, without a loop over a whole folder.
- Pick Groq for this week. Write “Groq, with a q, GroqCloud” on a note, and close any tabs about Grok so the two names stop blurring together.
- Open the live model list and copy one id. A small, fast model is enough for a first test, and the sample below uses
openai/gpt-oss-20b, one of the replacements Groq suggests for free and developer accounts. - Open Data Controls and read whether the text of your requests is kept. Turn on ZDR if that matches your agreement. Then open Billing, then Limits, and set a cap you could explain out loud in standup.
- Save the key as an environment variable, which is a named setting your computer holds outside your code. Do not commit it to a repository (a project folder that keeps every version of its files), and do not name the variable after a different product.
- Send one toy sentence and read the JSON that comes back, which is the structured reply. Check the usage numbers in it, and then stop.
Below is a curl command that matches Groq’s OpenAI-style path. Curl is a small command-line tool that sends a web request and prints what comes back. Put a real key into your environment as $API_KEY, and never paste a live key into a ticket or a gist.
# Toy call only. Public sentence. No vendor FAQs.
# Copy the model id from Groq’s list this week; names move.
export GROQ_API_KEY="$API_KEY"

curl https://api.groq.com/openai/v1/chat/completions \
  -H "Authorization: Bearer $GROQ_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-oss-20b",
    "max_tokens": 64,
    "messages": [
      {"role": "user", "content": "Reply with one sentence: the warehouse delay was ours."}
    ]
  }'
You should get JSON back with choices[0].message.content and a usage object that counts your tokens. A 401 error means the key is wrong. A blocked-spend 400 on Groq means your cap worked, and a 404 on the model means the list has changed, so copy the id again from the console. Together uses https://api.together.ai/v1/chat/completions and Fireworks uses https://api.fireworks.ai/inference/v1/chat/completions. The JSON idea is the same on all three, but each host has its own address and its own model string.
| What you might assume | What was true | Fix before the next loop |
|---|---|---|
grok_client.py talks to xAI | The key was GroqCloud | Rename the file. Say Groq out loud once |
| Cheap Llama, so 18 files are fine | Usage billing, long prompts, max_tokens 8192 | One toy sentence, small max_tokens |
| Open weights mean private | The prompt left the laptop | Open Data Controls / ZDR. Apply the privacy checklist |
| No budget line needed | Console showed $11.40 before standup | Spend cap on the org before any folder |
The 6,140-word dump can wait. If your legal team says those 18 files may not leave the company, a hosted API is the wrong tool for them. If they may leave, keep the cap, keep one model id, and log the token counts so that standup sees usage numbers instead of a surprise dollar figure.
Groq is not Grok
- Naming the script after Grok and paying Groq, or the reverse.
- Calling a Groq or Together playground “local” because the dropdown says Llama.
- Pasting a Hugging Face repo id into a host that wants its own string.
- Copying last year’s price into a budget instead of checking the live table.
- Leaving
max_tokenshuge and looping over a folder on a key with no cap. - Skipping the retention page because a tweet said “ZDR by default.”
- Putting three hosts and a router in one config before you can name a vendor in a review.
One test request and one spending limit
Create one key on one host and set a cap if the console offers one. Run the small test request with the warehouse sentence. Then write four lines on a sticky note: the host name, the model id, whether the request text is kept, and the cap you set. Do not point the key at customer files. The next post covers the easiest way to chat with a hosted open model through a web page, and it opens the series on running open models from scratch. Here is the post on the easiest hosted chat path, and the series page is Run open models from scratch.
Hosted open weights still leave the machine
- Pick one host and copy one model id from that host’s live list, because model ids change and an old one from a blog post returns an error.
- Read the retention page, set a spend cap, export
$API_KEY, and send one small test request. - A usage bill can reach $11.40 before standup, and a $20 seat is a different kind of product.
- Routers add one more stop, so name the real company behind them if someone asked for a specific vendor.
- This series ends here, and actually running the whole stack yourself starts in the next one.
Series notes
This is Part 10 of Open-source AI explained (OS7d). It pairs with the posts on what “open” means (OS1) and hosted versus local (OS2), both on Learn.
Sources
Product names, endpoints, and policy summaries checked against vendor help pages in August 2026.
- Groq (GroqCloud inference; not xAI Grok)
- Groq: Quickstart and Models (live ids; sample
llama-3.3-70b-versatile) - Groq: Spend limits and Your data (Billing Limits; ZDR; batch exceptions)
- Together AI, Quickstart, Terms, Privacy (API at
api.together.ai/v1; sampleMiniMaxAI/MiniMax-M3) - Fireworks AI, Serverless quickstart, Data handling (
api.fireworks.ai/inference/v1; sampleaccounts/fireworks/models/deepseek-v3p1) - OpenRouter (router: one key, many backends)
- Hosted versus downloaded models, privacy when running AI yourself, and Learn
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.