Treat an AI model file you download like software you are about to run, not like a document you glance at. Before you load one, prefer files from the official maker or a well-known uploader, read its description and license, check that the file size matches what it claims, and skip anything that comes as an installer program.
Say an online thread convinces you the official version of a popular model refuses too many requests, so you search Hugging Face, a large site where people share AI models, for an “uncensored” version. The top result is a 2.4 gigabyte (GB) file called “ULTIMATE” from an account created last Tuesday, with eleven downloads and a two-sentence description. You load it in LM Studio, a desktop app for running AI models, and ask a harmless question. It answers with 900 words of role-play. When you ask about its license, it makes one up: “commercial use, no restrictions.” You almost send that line to your legal team before you look at the file name again.
This post is a five-minute trust check: who published the file, what its card says, what files and sizes it contains, and then one public toy prompt. Walk away from empty cards and from downloads dressed up as .exe installers.
A download is software you run
A model file is not a screenshot of a chatbot. When you load a GGUF in Ollama, LM Studio, or llama.cpp, that binary is read by your computer’s main processor or graphics chip. Hugging Face’s own GGUF documentation describes the format as tensors, which are big blocks of numbers, plus a block of descriptive metadata, built for llama.cpp-style engines. By loading it you asked the program to execute someone else’s data. Treat the click like installing an app, because those bytes sit in your computer’s working memory (RAM) and they answer you.
Two other file stories sit next to GGUF, and people mash them together in chat threads. Pickle is the older PyTorch format (.bin or .pt), and it can run Python code when you load it. Hugging Face documents that risk and tells you to load such files only from people and organizations you trust, or to switch to safetensors, a format that stores only the numbers. GGUF uses a different reader, but it is still someone else’s model files running on your machine. A wrapped “AI installer” from a random website is a third story, because that is an executable program, and you should not run it.
The Hub also runs a malware scanner (ClamAV) on every commit, and a second scan for dangerous imports in pickled files. A clean badge only means the scanner did not match a known signature when it looked. The random file in our story could have been “safe” in that narrow sense and still useless for a three-page summary. I will not invent a percentage for how often GGUF files carry malware, because I have not seen a public count I trust. What I do see is worse: thin cards, strange titles, and fine-tunes that do not do the job on the label.
Rule of thumb: If you would not run a random
.exefrom that username, do not load a mystery GGUF from it either. Prefer the official publisher first, then a converter you can find in more than one place.
Official orgs, then converters you can name
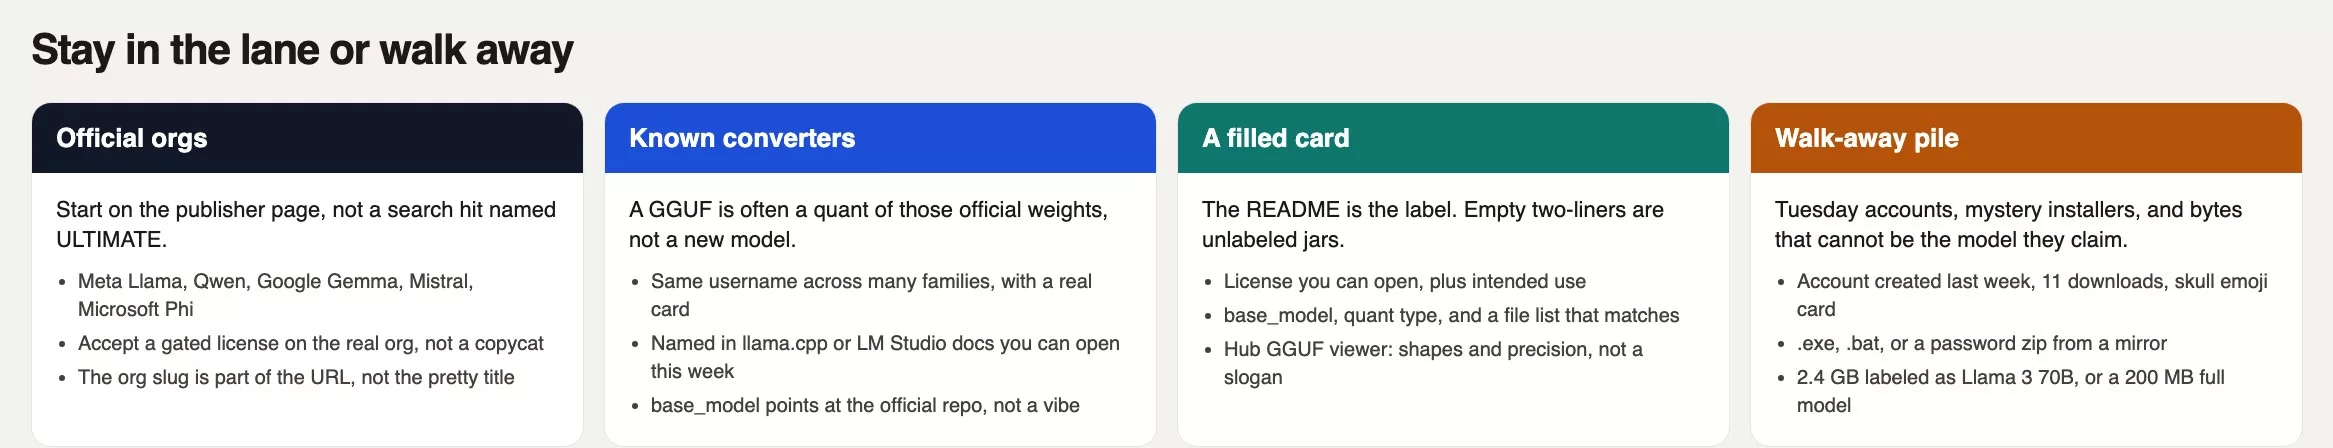
Start with the publisher. In August 2026 the boring, correct sources for the model families this series keeps naming are these: Meta Llama on the Hub and on llama.com/llama-downloads, Qwen under the Qwen organization, Gemma under Google, Mistral under mistralai, and Phi under Microsoft. The organization name is in the web address (meta-llama/..., Qwen/..., google/..., mistralai/..., microsoft/...), and a display name that says Llama in a silly font is not that address. Gated models such as Llama and some Gemma versions ask you to accept a license while logged in, so accept it on the real page. A copycat that promises “ungated Llama 3 70B, no form” is selling you a story.
Many laptop-sized files were not uploaded by Meta at all. They are quants, which means someone took the official (or at least documented) model and saved smaller variants for llama.cpp. Hugging Face even hosts a conversion space under ggml-org. Names of community converters change over time, so the test is not brand loyalty. The test is whether the same username appears across many model families, whether the card names the base_model, whether the file sizes match the quant table, and whether you can open a trail in the llama.cpp or LM Studio documentation this week. If you cannot point at that trail, you are back to the Tuesday account.
A converter is still a person with a disk. Prefer their Q4 (a middle-sized compression level) of an official instruct model over a one-off titled ULTIMATE with no base model listed. Words like “uncensored,” “abliterated,” “heretic,” and “god mode” are marketing. They can describe a real fine-tune (extra training on new examples), but they can also describe a merge that forgot how to follow a three-page summary. A title made only of adjectives should not earn your trust.
The model card is the label
A Hugging Face model card is the README.md file on the repository (a project folder that keeps every version of its files), often with a small header written in a plain-text settings format (YAML). The Hub’s own documentation says a card should describe the model, its intended uses and limits, training notes, datasets, and evaluation. The header fields that actually help before you download are license, base_model (and whether this is a quant, a fine-tune, an adapter, or a merge), library_name, datasets, and the pipeline tag (the label naming the job the model does, such as text generation). If the header is empty and the description is two sentences, you are holding an unlabeled jar, so walk away. Really.
Open the license the way you would open a vendor contract. Llama has an acceptable-use policy on Meta’s download page, and the Apache-2.0, Gemma, and Mistral licenses are not the same text. “Uncensored, so the license does not apply” is fan fiction. If the card says license: other, follow the license_link. If there is no license field and no LICENSE file, you cannot tell your legal team anything true. In our story the model itself invented “no restrictions,” which is how a 2.4 GB file becomes a company-wide incident.
On a GGUF repository, click any .gguf file under Files. The Hub has a GGUF viewer that shows metadata, tensor names, shapes, and precision. You do not need to read the technical detail, only spot one mismatch. Maybe the title says 70B but the viewer shows a tiny stack, or the title says Q4_K_M while the filename says Q2, or the card says Llama 3 instruct while the tensors look like a different family. Any one of those is enough. Comments are the other human channel, and people reporting “fails to load in LM Studio” or “this is a 3B renamed” are doing you a favor. A wall of fire emojis is an ad. Ignore it.
Files, bytes, and the installer trap
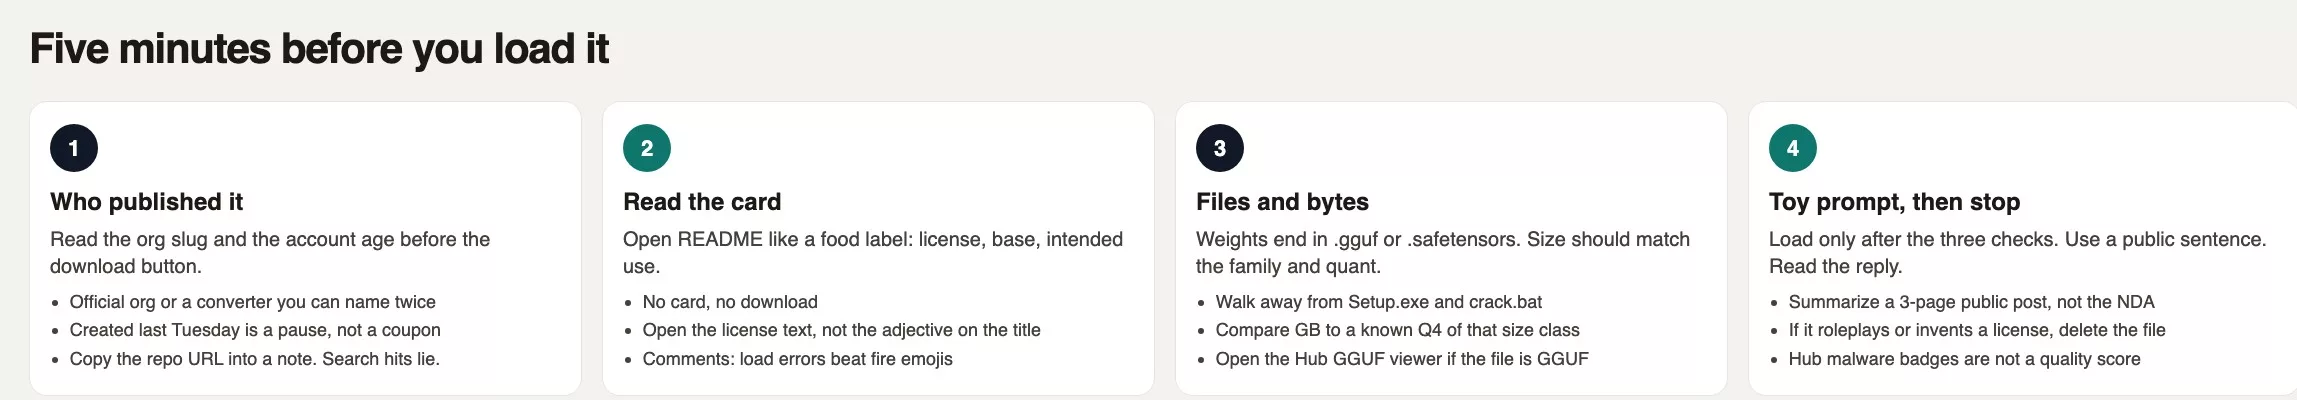
The files you actually want are .gguf for llama.cpp-style programs and .safetensors (plus a config file and a tokenizer, which splits text into pieces the model reads) for Transformers-style loading. A repository can hold both. What you do not want is Setup.exe, crack.bat, FREE-AI-INSTALLER.zip, a password-protected archive from a “mirror” in the comments, or a Chrome extension that is “required to download.” Those are not models. They are programs wearing a model-shaped costume, so close the tab. Now.
The size in bytes should match the story. The earlier post on size covered parameter counts and quantization (shrinking a model by storing its numbers with less precision). A typical 8B-class Q4 GGUF from a known converter lives around 4 to 5 GB, not 2.4 GB and not 200 megabytes, and a 70B Q4 runs to tens of gigabytes. The 2.4 GB “Llama 3 ULTIMATE” in our story could have been a small model, a brutal compression, a truncated dump, or a rename. Open one trusted Q4 of that size class and compare, and if the card and the file size disagree by a lot, stop. Eleven downloads is not a trust score, and “updated 14 minutes ago” on a brand-new user is a reason to wait.
Five minutes is the budget: check the publisher and account age, the card and license, the files and size, and then run one public prompt. Use a blog post you could email to a stranger, never a confidential agreement. If the model roleplays or writes a fake license, delete the file, keep the runner, and swap in an official instruct quant.
Worked example: five minutes on a suspicious file
This is a toy case, labeled as such. The repository name in this example is fake on purpose: tuesday-weights-lab/Llama3-uncensored-ULTIMATE. The account was created last Tuesday, it has eleven downloads, and the file on disk is 2.4 GB. You already have LM Studio because a coworker shared a screenshot, and you searched, clicked Download, and skipped the card. Here is the check you can still run with the page open, comparing what a trustworthy repository looks like with what this one showed.
| Check | Stay in the lane | Walk away (the Tuesday hit) |
|---|---|---|
| Who published it | Official organization name, or a converter you can find in llama.cpp / LM Studio docs this week | Account created last Tuesday, eleven downloads, display name is three adjectives |
| Model card | License, base_model, intended use, quant named | Two sentences and a skull. No header. No base model. |
| License | A text you can open (Llama, Apache-2.0, Gemma, Mistral, a license_link) | Missing, or the model invents “no restrictions” when asked |
| Files | .gguf / .safetensors, tokenizer, config | Setup.exe, .bat, password zip from a “mirror” |
| Size vs claim | Gigabytes in the neighborhood of that family and quant | 2.4 GB labeled Llama 3 ULTIMATE; a known 8B Q4 is nearer 4 to 5 GB |
| Comments / viewer | Load errors, hash notes, GGUF viewer shapes that match | Only fire emojis, or tensors that look like a much smaller stack |
| First prompt | A public three-page post, on-task summary | 900-word jailbreak roleplay, then a fake license for your legal team |
You needed a sticky note, not a security team. Every walk-away sign was visible before the runner even started, except the 900-word reply, which arrived in under a minute. The confidential agreement never went in, the half-typed message to legal got deleted, and the 2.4 GB file went to the Trash.
Below is a checklist you can paste into a note. Fill in every line, and if a line is “no” or “unknown,” do not load the file. Labels in the Hub’s interface change, so in August 2026 this is the general shape and not a promise that every page uses the same badge names.
# Five-minute trust check before you load a GGUF
# Fill every line. If any answer is "no" or "unknown", stop. ORG= # meta-llama / Qwen / google / mistralai / microsoft / named converter?
ACCOUNT_AGE= # months, or created this week?
CARD= # README with license, base_model, intended use? or two sentences?
LICENSE= # a file or license_link you opened, not an adjective?
SIZE_GB= # matches that family and quant (compare to a known Q4)?
FILES= # .gguf / .safetensors, NOT .exe .bat .scr installer.zip?
VIEWER= # Hub GGUF viewer: shapes vs the title?
COMMENTS= # load errors and hashes, or only fire emojis?
TOY_PROMPT= # public 3-page post only. NDA stays off this runner.
REPLY_OK= # on-task summary? if it roleplays or invents a license, delete. # Load only if ORG is known, CARD exists, SIZE matches, FILES are weights.
# Then run TOY_PROMPT. Time it. Read it. Then decide.
The point of that block is that you could have filled in ORG and ACCOUNT_AGE in forty seconds and never hit Download. The toy prompt is the last gate, not the first. If you only test with a confidential agreement, you have already failed the check, and the related guide on privacy explains why.
Random Hub files are not a store
- Searching “uncensored ULTIMATE” and treating the first hit as if Meta published it.
- Skipping the model card because the filename has Llama in it.
- Reading a Hub malware badge as a quality score.
- Running
Setup.exe“so the model works on Windows.” - Pasting a confidential agreement into the first prompt to “see if local is good.”
- Telling your legal team a license the model invented in chat.
- Assuming pickle, GGUF, and an installer all carry the same risk.
Check the card before you pull
Open one official organization page, such as Llama, Qwen, Gemma, Mistral, or Phi, and open its card. Write the license name on a sticky note. Then open one GGUF from a converter that lists that repository as its base_model, and compare the file size to the card. Run the checklist, and use a public paragraph only. If you already downloaded a Tuesday special, delete it, or quarantine the folder until the checklist passes. The next post covers when a closed chat is simply easier, where a paid chat box is the honest tool and a random GGUF is unpaid labor. Reading cards in more depth comes later in this series, and the path for desktop runners from zero is in the series on running open models, beginning with the hosted chat page.
Safety before the download
- A random GGUF is software on your machine, so prefer official publishers and then converters you can name twice.
- Five minutes covers the publisher, card, license, files, size, and one public prompt, with no mystery
.exe. - Sloppy fine-tunes are the usual mess, though malware exists too, so do not invent a statistic and walk away when the card is empty.
Your next step
Before your next model download, open its model card and do the five-minute check from this post: publisher, card, license, files, size, and one test prompt. Write what you found next to the file name in a short note, so you can show anyone who asks where the file came from and why you trusted it.
Series notes
This is Part 6 of Open-source AI explained (series code OS6). Previous: quality without benchmark theater. Next: when a closed chat is simply easier. Related: hosted vs download and Run open models from scratch.
Sources
- Hugging Face Hub: Model cards (readme plus settings header: license, base_model, intended use, datasets)
- Hugging Face Hub: GGUF (format, GGUF viewer, ggml-org conversion space, llama.cpp / LM Studio / Ollama)
- Hugging Face Hub: Pickle scanning (loading pickle can execute code; prefer trusted orgs and safetensors)
- Hugging Face Hub: Malware scanning (ClamAV on commits; a badge is not a quality audit)
- Meta Llama downloads (license and acceptable use on the official page)
- llama.cpp, Ollama, and LM Studio (runners; confirm the model source inside the app)
- Analytics Made Simple: hosted vs download and privacy paste test
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.