On an ordinary laptop, pick a small AI model in its packed form, because your computer’s working memory decides whether the model runs, not whether the download finished. Labels such as 7B and 70B count the model’s learned numbers in billions, and they work like clothing sizes. They tell you how big the model is, not how smart it is. A tag such as Q4 means the model was squeezed into a smaller file so a laptop can load it.
Say you are sitting on a kitchen stool with a MacBook Air that has 16 gigabytes (GB) of memory. A coworker says a big 70B model “felt like ChatGPT,” so you download it in Ollama, a free app for running models on your own computer. The file alone is 43 GB. Your fan turns into a leaf blower, and the first word of the reply takes minutes to appear because your browser and chat apps are still open. You close the lid with the cursor still blinking.
This post teaches the sticky-note pick. On 8 to 16 GB of memory, stay near a 7B or 8B model in Q4 form. On 32 GB you can try 13B to 14B, and a 70B model wants a lot more memory or an online service that runs it for you. The numbers below come from library pages checked on October 2, 2026, so re-check the library the week you pull a model.
Billion is a clothing size
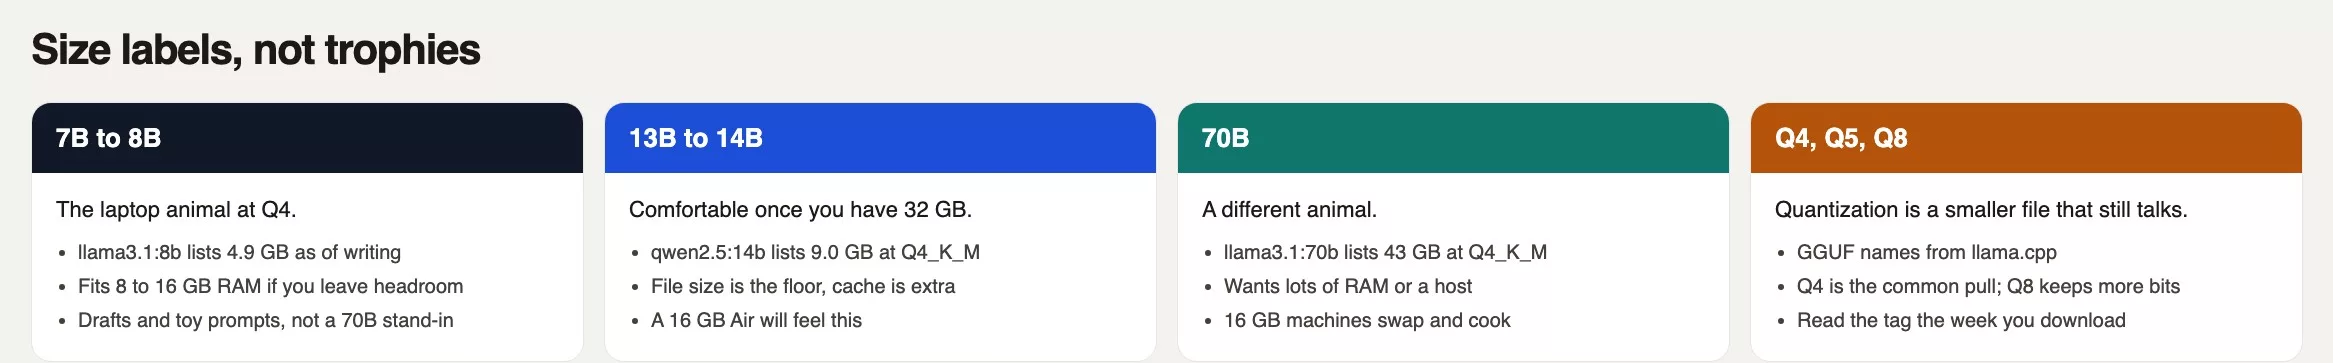
The B stands for billion parameters. A parameter is one number the model learned during training, and 7B means about seven billion of those numbers. A 70B model has about ten times as many. Treat the label like a shirt size, because it tells you how much cloth you bought and nothing about how well the shirt fits your work. Nobody at the office gives you points for wearing an extra large.
Model families reuse the same name at several sizes. Google’s Gemma 4 ships sizes from E2B through 31B, and Alibaba’s Qwen3.5 ships everything from 0.8B through 122B. A handy middle size in October 2026 is often 9B, and Ollama lists qwen3.5:9b at 6.55 GB in the Q4_K_M form (checked October 4, 2026). Tag names change, so open the library page the week you type ollama run.
Bigger can help with hard reasoning and long instructions. Smaller is faster, cooler, and more likely to fit in your machine. A sharp 8B model on your laptop beats a 70B model that spends four minutes shuffling data to the disk, so pick a size your memory can hold and then judge the writing on a prompt of your own. A later post covers how to judge quality without the hype.
A few models are built as a mixture of experts, which means only a slice of the model is active for each word it produces. A 30B or 120B name on one of those cards can ship a smaller file than you would expect, so read the card before you compare it with a regular model. For your first local setup, stay with a plain, dense model at 7B to 8B in Q4.
Rule of thumb: The B is how much model you asked for. Memory is whether the machine can lift it, and disk is only whether the file landed.
Quantization is a smaller file that still talks
Full-precision weights are fat. The quantize notes in the llama.cpp project, checked on October 2, 2026, put the original Llama 3.1 8B near 32.1 GB and its Q4_K_M version near 4.9 GB. For the 70B model, the original is near 280.9 GB and Q4_K_M is near 43.1 GB. That is why Ollama lists llama3.1:8b at 4.9 GB and llama3.1:70b at 43 GB, since you download a packed version and not the full textbook.
The packed file format is called GGUF (GGUF is short for GPT-Generated Unified Format). Hugging Face’s Hub docs describe it as the model’s numbers plus labeling information, built for engines in the GGML family (GGML is short for the tensor library those engines share). llama.cpp is the engine underneath a lot of desktop apps, and Ollama and LM Studio (LM stands for language model) both work with that ecosystem. You do not have to compile llama.cpp yourself, but you do have to read the quantization name on the file.
Those names look like serial numbers, so here are the three you will meet first, again from pages checked in August 2026:
Q4_K_M(and other Q4 flavors) uses roughly 4 to 5 bits per weight. Ollama’s default Llama 3.1 tags use it, and it is the pull that usually still talks well.Q5_K_M(and other Q5 flavors) takes a bit more memory and lands closer to the original numbers, which helps when Q4 feels mushy and you have memory to spare.Q8_0uses about 8 bits and Hugging Face still documents it. It sits nearer the original numbers at roughly double the size of a Q4 file, which is fine on a 7B model and painful on a 70B.
There are more letters than these, such as Q4_0, _S versus _M, and the newer I-quants like IQ4_XS. You do not need the whole menu on day one. If the Hub file and the Ollama tag both say Q4_K_M, you are in the main lane, and it is still worth re-checking the file, because tags do get retagged.
Quantization works like a lossy zip file for the model’s numbers. The model usually still talks, although it can get vaguer, worse at tiny facts, or sloppier with a fiddly output format. It does not turn a 7B into a 70B. Saying “just use Q8” spends memory you may not have, and on a 16 GB Air that spending is how you meet the leaf blower. Pull a tagged Ollama file, or a Hub GGUF file that already lists its quantization, and leave the llama-quantize tool for a later craft.
Memory is the limit, not the download bar
Disk space is cheap enough that a 43 GB file can finish downloading. Memory is the room the model needs while it runs. If the file is larger than the memory your operating system will give it, the machine starts paging, which on a Mac means compressing memory and then borrowing space on the solid-state drive (SSD). The fan climbs and the words crawl out. The first word is the slowest because the program is still hauling the model in from the drive.
Apple Silicon makes this easy to miss. An M2 Air has unified memory, which means the processor (CPU), the graphics chip (GPU), and the display all share the same 16 GB. The number to check in About This Mac is the memory, and not the 256 GB of SSD storage you happen to have. A Windows laptop with 16 GB of RAM and a 4 GB graphics card is the same shape of problem. An 8 GB graphics card can hold a 7B model in Q4, but it will not hold a 43 GB 70B model.
The file size is the floor and not the whole bill. You still owe memory to the operating system, the browser, and the key-value (KV) cache, which is the conversation’s working memory. A long conversation spends more of that cache. A 4.9 GB 8B model feels tight on 8 GB with 40 Chrome tabs open and relaxed on 16 GB once you quit the junk, so the picks below say “around” and “try” and not “guaranteed.”
A model that fits in RAM (or in the graphics card’s own video memory, known as VRAM) can stream its reply. A model that spills onto the drive can still finish a sentence, but you will have time to open your email while you wait. The four-minute first word in the opening scene came from that spilling, and Llama had no bug. The 70B file was honest about its size, and the 16 GB laptop was simply the wrong closet for it.
Write the pick on a sticky note
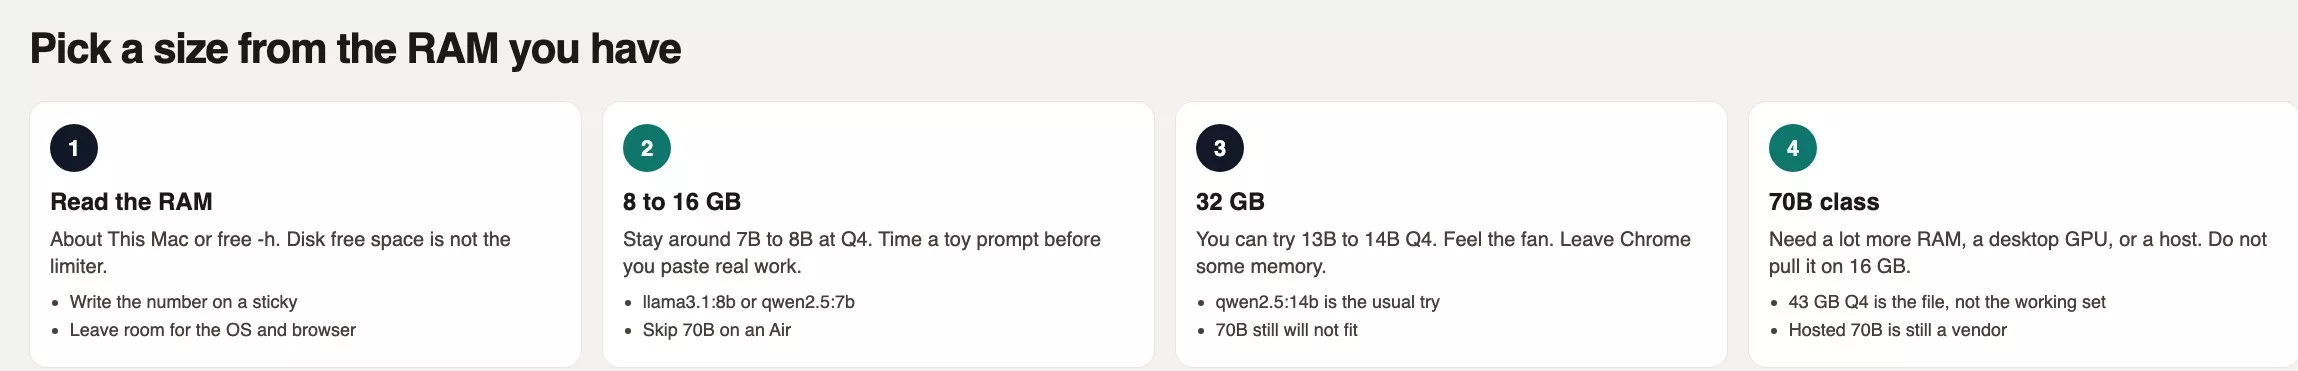
Look up your memory first. On a Mac, open the Apple menu and choose About This Mac, and on Linux run free -h. Write the number down, and then pick a size that leaves room for the rest of the computer. The table below gives a starting pick based on library pages checked in August 2026.
| Size label | Typical Q4 file (Ollama, checked August 2026) | Memory that usually holds it | Use it when |
|---|---|---|---|
| 7B to 8B | llama3.1:8b 4.9 GB, qwen2.5:7b 4.7 GB, both Q4_K_M | 8 to 16 GB with headroom | First local chat, drafts, toy prompts on a laptop |
| 13B to 14B | qwen2.5:14b 9.0 GB at Q4_K_M | 32 GB is the comfortable try | You already have the RAM and 8B feels thin |
| 32B-class | Often near 20 GB at Q4 (check the live tag) | 32 GB is tight, 64 GB is calmer | A desktop or a loaded laptop, after 14B is useful |
| 70B | llama3.1:70b 43 GB at Q4_K_M | A lot more unified memory, a big GPU pair, or a host | Never as the first pull on a 16 GB Air |
If you have 8 to 16 GB, stay around 7B to 8B at Q4. If you have 32 GB, try 13B to 14B. A 70B model wants a lot more memory or a hosted service, so tape that rule to the bezel of your screen. The 405B tag is a joke on a laptop, since Ollama lists llama3.1:405b at 243 GB.
Even a 32 GB machine cannot keep a 43 GB 70B Q4 file loaded. Squeezing a 70B into 2-bit form on 32 GB is a hobby and not a Monday pick. If you need 70B-class answers on 16 GB, the honest answer is a hosted service, as the earlier post on hosted versus downloaded models explained. Groq is the hosting company spelled with a q, and it has nothing to do with Grok from xAI. Together and Fireworks rent graphics hardware too. In every case your prompt leaves your device, so make that trade on purpose.
Worked example: 43 GB, 4 minutes, one Air
Back to the kitchen stool. Your Air has 16 GB of unified memory and maybe 180 GB free on disk. The pull succeeds, so disk space was never the veto. The operating system compresses memory and then swaps to the drive, and the first word arrives after 4 minutes. Later words still take seconds each. You asked for a rewrite of a public blog paragraph, a job that llama3.1:8b would have finished while the 70B model was still catching its breath.
Here is a check you can run before the 43 GB mistake. Flags and tag names move, so read the help text the week you try this.
# RAM pick, then a toy pull.
# As of October 4, 2026, the Ollama library lists:
# qwen3.5:4b 3.32 GB Q4_K_M
# qwen3.5:9b 6.55 GB Q4_K_M
# qwen3.5:27b 17.48 GB Q4_K_M
# qwen3.5:122b 81.37 GB # macOS bytes of RAM:
sysctl hw.memsize
# Linux:
# free -h # 8 to 16 GB RAM: stay here.
ollama run qwen3.5:9b # Toy prompt only. Time the first token with a watch.
# Reply in one sentence: what is 17 times 4? # 32 GB RAM: you may try this after the 9B feels thin.
# ollama run qwen3.5:27b # Do not run this on 16 GB:
# ollama run qwen3.5:122b
The point of this check is that your memory number hits the screen before the 70B badge does. If the 8B model’s first word is already slow, quit the 40 browser tabs and try again. A hot laptop is not a request for a bigger model. If the 8B model runs fine, keep it for a week before you decide anything else.
When a host is the honest 70B
If the job needs a large open model and your machine is a 16 GB Air, pay a host and say so out loud. A Q4 70B model wants tens of gigabytes of fast memory, which means a Mac Studio class machine, a used pair of graphics cards, or someone else’s rack of servers. You cannot will 43 GB into an Air by buying a bigger drive.
A closed chat product (ChatGPT, Claude, Gemini, or the Grok chatbot) may still be easier for plain writing, and the AI products chooser walks through that choice. Do not build a local 70B setup just so a thank-you note sounds like a press release. Do not paste a confidential document (one covered by a non-disclosure agreement (NDA)) into a host because the local 8B model felt “less smart.” Location is still the question that matters most, and size only decides whether the model fits.
Stay on the laptop when the work has to be offline. In that case the sticky-note pick is your whole strategy, because a 7B Q4 model that answers in two seconds with Wi-Fi off beats a 70B model that melts the case. The post on why normal people care about open-model privacy explains what staying local really protects, and the privacy paste test gives you a quick way to check a prompt before it leaves.
Common mistakes with memory and size
- Treating 70B as a badge, when it is only a clothing size and earns no points.
- Reading free disk space as “it will run,” when memory runs the model and disk only stores it.
- Pulling
llama3.1:70bon 16 GB because the command is one short line. - Choosing Q8 on a 70B “for quality” when you cannot even hold Q4.
- Judging an 8B model while it is swapping to disk, then calling local models “unusable” instead of quitting Chrome and retrying.
- Skipping the model card’s quantization line on Hugging Face, when the GGUF filename is the real spec.
- Mixing up Groq the host with Grok the chatbot when you bounce off a local 70B.
Pick one size you can load
Write your memory number on a sticky note and pull one 7B or 8B Q4 tag. Time a toy prompt. If you have 32 GB, try the 14B on the same prompt and keep whichever is faster. Do not pull a 70B on 16 GB. The next post covers privacy reasons for running models yourself, and the hosted-versus-download split still applies. For step-by-step setup, see Learn.
Quantization in one page
- The labels 7B, 13B, and 70B are size labels, so write down your memory first.
- Q4, Q5, and Q8 (with GGUF, llama.cpp, and Ollama tags) shrink the file, and the model usually still talks.
- With 8 to 16 GB, stay near 7B to 8B Q4. With 32 GB, try 13B to 14B. For 70B, get lots of memory or use a host.
- A 43 GB
llama3.1:70bon a 16 GB Air is how you get a 4-minute first word and a leaf blower.
Series notes
This is Part 3 of Open-source AI explained (series code OS3). Previous: hosted vs download. Next: privacy reasons normal people care about. Hands-on setup lives in Run open models from scratch.
Sources
- Ollama and the Llama 3.1 library page (checked in August 2026:
llama3.1:8b4.9 GB,llama3.1:70b43 GB, bothQ4_K_M) - Qwen 2.5 on Ollama (
qwen2.5:7b4.7 GB,qwen2.5:14b9.0 GB,Q4_K_M) - llama.cpp and its quantize notes (original vs
Q4_K_Msizes for Llama 3.1 8B / 70B / 405B) - Hugging Face Hub: GGUF (format, quant type table, Q4_K / Q5_K / Q8_0 and newer IQ types)
- LM Studio (desktop runner that also loads GGUF)
- Groq (hosted inference; not xAI Grok) if 70B will not fit
- Analytics Made Simple: hosted vs download and what open means
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.