You can run a small AI model on an ordinary laptop, as long as the model fits in your computer’s working memory (RAM), and the real cost is heat and battery. On a laptop with 16 gigabytes (GB) of memory and a browser open, start with a model that has about 7 billion settings (the numbers it learned in training), in a compressed version that download sites label “7B Q4.” (Q4 means each of those numbers is stored in 4 bits instead of 16, so the file is about a quarter of the size.) You don’t need a gaming graphics card just to rewrite an email.
Say you are working from a shared table at a coworking space, and the charger is in the other bag. Someone online calls the small models toys, so you download one about twice as big to tidy up your meeting notes. Twenty-two minutes later your laptop’s memory is almost full, the case is too hot to rest on your lap, and the battery is at 8%. The notes came out as three paragraphs, and you still have a client call at the end of the afternoon.
This post explains what happened there. It covers how memory works on a Mac and on a PC, why a model can be too big for your laptop even when the file downloads fine, and when a graphics chip (GPU, the part that does the heavy math for AI) is worth having. It ends with a short check you can paste into the Terminal (the Mac’s text window for typing commands) before you download a bigger model. Model sizes on download sites change, so re-check them the week you download.
Two memory maps
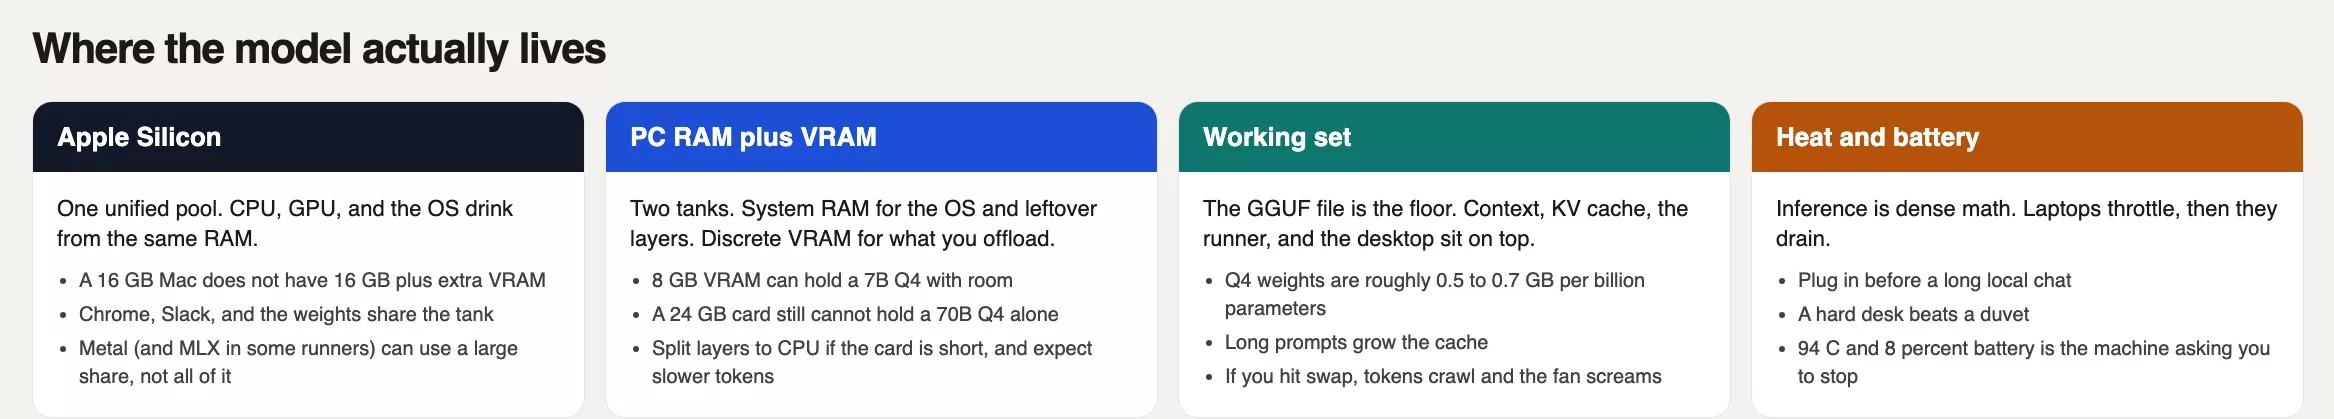
The weights, the numbers the model learned, are a file. While you chat, the whole file has to sit in memory that the processor can reach. A Mac with Apple Silicon and a Windows or Linux PC with a graphics card keep that file in different places.
Apple Silicon: one pool
Apple’s M-series chips share what Apple calls unified memory. The processor, the graphics chip, and the rest of the system all read from the same RAM. A 16 GB MacBook Air does not have 16 GB of system RAM plus a hidden 8 GB of VRAM. It has 16 GB, and that is all. Chrome, Slack, Preview, the operating system, and the model all draw from that one supply. A 13B Q4 file can “load” and still feel like wading through syrup, because the file found a home and then the desktop took the rest. Runners talk to the graphics chip through Apple’s Metal software. Ollama has also previewed an MLX path on Apple silicon, using Apple’s own machine-learning framework (MLX). macOS still keeps a slice of memory for itself. If the Memory Pressure graph in Activity Monitor turns yellow or red, the model is swapping to the SSD (your storage drive), which means it is borrowing slow disk space as if it were memory. Tokens (the chunks of text the model writes) arrive more slowly, and the fan does not stop.
A PC: RAM plus VRAM
A typical Windows or Linux desktop has two separate pools. System RAM holds the operating system, the browser, and any leftover layers of the model. Video memory (VRAM) on the NVIDIA (the company whose graphics cards most AI tools are built for) or Advanced Micro Devices (AMD) graphics card holds whatever part of the model you offload to it. An 8 GB card can keep a 7B Q4 file with room for a short conversation. A 24 GB card, the 4090-class ceiling that a lot of shopping tabs chase, can hold 13B to 32B-class Q4 files more comfortably. A 70B Q4 file still wants on the order of 40 GB for the weights plus working space, so one consumer card cannot swallow it whole. You either split layers onto the processor or you use a host.
llama.cpp is the engine under parts of Ollama and LM Studio, a free app for running models on your own computer. It can run on the processor alone, put every layer on the graphics card, or split the layers between them. Splitting is how a 13B model survives on 8 GB of VRAM, and it is why the reply seems to take a breath between words. The trip between those two pools is a cost you skip with unified memory, so a Mac can hold a bigger file than a similarly priced gaming laptop.
Rule of thumb: If the model file is more than about a third of the RAM (or VRAM) you can actually spare, expect swapping, heat, and a sad fan. On 16 GB with Chrome open, that points at a 7B or 8B Q4 file.
Fit is more than the file size
The earlier post on model size and quantization covered quantization, which shrinks a model by storing its numbers with less detail, and the labels: 7B, 8B, 13B, 70B, and the Q4, Q5, and Q8 tags on a GGUF file (a file format for models that run on personal computers). The number on the library page is the floor. In August 2026, llama3.1:8b was listed at around 4.9 GB, and that figure is only the packed weights. A chat also adds a key-value (KV) cache, which is the model’s scratchpad for this conversation, plus temporary calculations, the runner program, and whatever else is already in memory. A long paste of standup notes grows that cache, so a 32k context window (the amount of text the model can hold in view) is not free.
Many local guides use a working rule of about 0.5 to 0.7 GB of weights per billion parameters (the learned numbers inside a model) at 4-bit, then extra room for the cache and the app, then a few more GB for the operating system. Treat that as a rough guess, because quantization recipes differ. Mixture-of-experts models can look huge on the box and use only some of their experts for each token. So read the model card, and then time a small test prompt.
Swap is the failure you hear as a fan. When RAM is full, the operating system writes pages of memory to disk and reads them back. An SSD is fast compared with a hard drive from 2012, and it is slow compared with RAM. Memory Pressure climbs, the disk stays busy, and you get one token every few seconds. The model did not need a better prompt. It needed a smaller file, a closed browser, or a machine with more of the right kind of memory.
A sane machine and size table
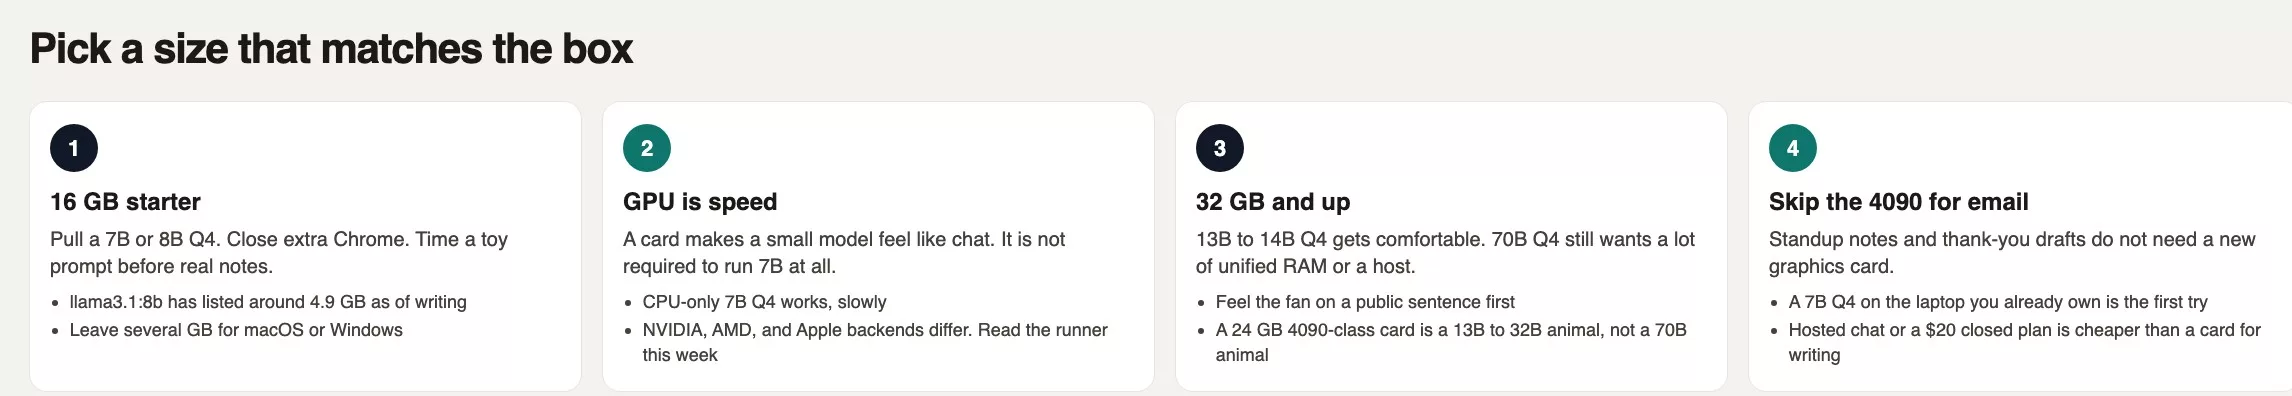
Use this table as a starting map and not as a warranty. It assumes a short conversation, a Q4-class GGUF, and one chat at a time, using the library sizes from August 2026. Close the 40-tab browser session before you judge the laptop. If the runner offers a cloud model, that row does not apply, because your prompt left the building. The post on hosted versus downloaded models explains that difference.
| Machine | Sane starter | Skip | Why |
|---|---|---|---|
| 8 GB laptop, no extra GPU | 1B to 3B Q4 if you try local at all | 7B and up with Slack open | OS plus one 7B file will swap |
| 16 GB unified Mac, or 16 GB RAM CPU-only PC | 7B or 8B Q4 | 13B+, 70B | File plus cache plus Chrome fills the pool |
| 16 GB RAM plus 8 GB VRAM | 7B or 8B fully on the card | 70B | GPU holds the small model; 13B may split |
| 32 GB unified or 32 GB RAM | 13B to 14B Q4 | 70B Q4 if you also want a browser | Headroom for cache and the desktop |
| 24 GB VRAM (4090-class) | 13B to 32B Q4 on the card | Buying this to rewrite email | 70B Q4 still wants ~40 GB of weights |
| 64 GB+ unified or a workstation | 70B Q4 becomes possible | Expecting ChatGPT Plus prose by default | Capacity is not a closed-chat subscription |
The 16 GB row is the one this series keeps coming back to, and it is the reason this post centers on a 7B Q4 on 16 GB. You can try a 13B, and you will feel it. The size post’s qwen2.5:14b listing, at around 9.0 GB in Q4_K_M, will cook a 16 GB Air. Pull the 8B first.
A GPU is a speed upgrade
Small models run on the processor alone, because llama.cpp was built for that. A 7B Q4 on a modern laptop processor will produce text, though it may feel like a careful typist and not a chat app. A GPU moves the same math onto hardware that is built for matrices. That means NVIDIA’s parallel-computing software (CUDA), AMD’s ROCm software on a narrower list of cards, or Apple’s Metal or MLX. Replies get snappier. You still need the weights to fit in the pool you chose, and an 8 GB card does not magically hold a 70B file. It holds a 7B well. Ollama will use a GPU if it sees one. LM Studio shows a slider for how many layers go on the card. When you run llama.cpp by typing commands, it uses a setting called --n-gpu-layers. You do not need any of those flags for a first 8B model on a 16 GB Mac.
Do not buy a 4090 to rewrite a standup. The GPU already inside a Mac, a used 8 GB card, or a processor-only 7B model will draft the same three paragraphs you needed. A 4090 suits a hobby or a batch job, and it is not an email tool. If the writing can leave your machine, the hosted option in hosted open-model chat is cheaper. Groq (a company that runs AI models for others, spelled with a q, not xAI’s Grok) and similar companies rent out fast graphics chips by the token. A roughly $20 closed plan from the post on accounts and free versus paid is cheaper still for thank-you mail. Local hardware is the bill you pay when the prompt must stay on your machine, or when you already own the box and accept the fan.
Heat and battery are the other invoice
Running a model is dense math that does not pause. Laptops are designed to work in bursts and then rest, but a local chat session never rests. The chip stays busy for every token, so heat rises and the fans spin up. On a thin Air, the aluminum under your palms is the heatsink, and 94°C is the case telling you so. Thermal throttling comes next, which means the chip slows itself down to survive. The “slow model” you blamed is partly a hot model.
Battery is the second meter. Unplugged, a 16 GB Air decoding a 13B-class model will drain charge in a hurry. In this story you hit 8% in 22 minutes because the charger was in the bag across the room, and because you treated “offline” as a cafe mode. Offline means the prompt can stay on the machine. It does not mean the machine can live on a 12% charge. Plug in. If you cannot, drop to a 7B Q4 file, shorten the prompt, and quit the browser. A duvet, a couch cushion, and a packed backpack under the hinge all act as blankets, so put the laptop on a hard table. If the job is a public FAQ rewrite and the laptop is already cooking, stop. Hosted open-model chat, or the closed box from the AI products chooser, will finish the paragraph. Local is for the paste you would not email, as the privacy paste test explains.
A worked example: 22 minutes, 94°C, 8%
You wanted three things from the earlier list of offline tasks. You wanted messy standup bullets turned into a Slack update, the text kept on your laptop, and a prepared look before the afternoon call. You had one working setup from the Ollama post and 16 GB of memory. You picked the wrong size.
| When | What you saw | What it meant |
|---|---|---|
| Start | Pulled a 13B-class Q4 (~7 to 9 GB on disk) | Too big for 16 GB with Chrome and Slack |
| 8 minutes in | First reply slow, fan loud, Memory Pressure yellow | Working set plus desktop filled unified memory |
| 22 minutes in | 94°C, 8% battery, 14.8 GB used, three paragraphs out | Heat and battery collected the bill. The notes were a 7B job. |
| After | Quit Chrome, plug in, pull llama3.1:8b (~4.9 GB listed) | Same task, headroom, cooler case, battery that lasts a meeting |
So you unload the 13B and pull the 8B Q4. You quit the browser for the session, plug in, and put the Air on a table and not a backpack. Send one public sentence first, such as “Summarize: the warehouse delay was ours,” and watch Activity Monitor for 30 seconds. If Memory Pressure stays green and the fan is a background hum, paste the standup. If it goes yellow, you are still too big. Do not add a 4090 to that story. Add a smaller file.
Pre-flight: a hardware checklist in Terminal
Run this before you pull a new model. It prints your RAM, NVIDIA memory if a driver is present, and battery status on macOS. Flags and program names change, and as of August 2026 this shape is enough to read your memory pools.
# Check RAM, GPU memory if any, and battery before you download a bigger model.
# Written August 2026. Run in Terminal. Skip any line that errors.

echo "=== RAM ==="
if command -v sysctl >/dev/null 2>&1; then
  sysctl -n hw.memsize | awk '{printf "Physical RAM: %.0f GB\n", $1/1024/1024/1024}'
fi
command -v free >/dev/null 2>&1 && free -h

echo "=== NVIDIA GPU (skip on Apple Silicon) ==="
if command -v nvidia-smi >/dev/null 2>&1; then
  nvidia-smi --query-gpu=name,memory.total,memory.free --format=csv,noheader
else
  echo "No nvidia-smi. Fine for Macs and CPU-only PCs."
fi

echo "=== Battery (macOS) ==="
command -v pmset >/dev/null 2>&1 && pmset -g batt

echo "=== Starter ==="
echo "16 GB with Chrome open: pull 7B or 8B Q4. Time a toy prompt."
echo "Do not pull 70B. Do not buy a 4090 to rewrite a standup."
The script prints a RAM number for your sticky note, a VRAM line if the PC has an NVIDIA card, and whether you are on battery. If physical RAM is 16 GB and pmset says discharging, plug in before the 13B experiment. If nvidia-smi shows 8 GB total, plan for a 7B fully on the card. If that command is missing and you are on a Mac, you are in the unified-memory row. Then run ollama list, or look at LM Studio’s model sidebar, and confirm the model is local and not cloud.
Mistakes with a 7B card on an 8 GB machine
- Reading “16 GB Mac” as 16 GB of RAM plus extra VRAM, when unified memory is one pool.
- Treating the GGUF file size as the full memory need, when the cache, Chrome, and the operating system all sit on top.
- Pulling a 13B on 16 GB because someone called 7B a toy. The 94°C session in this post is that mistake.
- Buying a 4090, or any new card, to draft email. Size the job first, because writing often wants a $20 plan or a hosted chat page.
- Running a long local chat unplugged on a thin laptop, then blaming the model for 8% battery.
- Leaving a cloud model selected after you “went local.” Hardware notes do not apply if the prompt left your machine.
Your next step: note your memory and pick a model
Write your RAM, and your VRAM if you have a card, on a sticky note. Run the pre-flight script. If you have 16 GB, pull one 7B or 8B Q4 file and send the warehouse-delay sentence. Watch Memory Pressure or Task Manager for a minute, and feel the case with your hand. If you are on battery, plug in and run the same prompt again. Only then retry a 13B, and only if 32 GB is sitting there. Next comes the post on updating local models, which explains how to update a tag without breaking the setup you just fitted. More paths are on Learn.
Hardware you actually have
- Apple Silicon has one memory pool, and a PC has RAM plus VRAM. Fit the file to the pool you actually have.
- A 7B Q4 on 16 GB is the honest starter. The file size is the floor, not the full memory need.
- A GPU speeds up small models, and it is not required. Do not buy a 4090 for email.
- Plug in, use a hard desk, and pick a smaller model. Reaching 94°C and 8% battery in 22 minutes is the machine vetoing the 13B.
Series notes
This is Part 5 of Run open models from scratch (series code OS12). Previous: first useful offline tasks. Next: updating models without breaking the setup. Related: size and quantization and one local stack.
Sources
- llama.cpp (CPU, CUDA, Metal, split layers; Apple silicon called out as a first-class target)
- Ollama and Ollama MLX preview on Apple silicon (runner plus unified-memory path; confirm local vs cloud tags)
- LM Studio (desktop runner with hardware sliders)
- Hugging Face: GGUF (file format and quant names)
- Hugging Face: model cards (size, license, intended use, the week you pull)
- Groq (hosted inference; not xAI Grok) and Together AI / Fireworks AI (when a laptop should not hold the file)
- Model size and quantization and Hosted versus local
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.