Pick one local setup for running an AI model and stick with it. A local model is a program on your computer that waits for requests at a numbered doorway called a port. If three different apps are each waiting on three ports, your request may reach the one that is switched off. This post walks through a 30-minute path using Ollama: install it, download one small model, chat with it, save a prompt, and close the extra apps.
Imagine you have a saved command that sends a 12-line warehouse note to port 8080, and it comes back with “Connection refused.” When you open Activity Monitor (the Mac tool that lists running programs), three different programs all claim to be a local model: Ollama, LM Studio, and an older setup from last month that has already shut down. The note was about two pallets and a missed dock appointment, and your request went to the setup that was off.
If you already like LM Studio from the earlier post on desktop runners, stay there and close Ollama. This walkthrough uses Ollama only because its commands are easy to paste. The rule that matters is to run one setup at a time.
One app, one port
A local model is a program listening on a port. A command-line request, a chat window, and a Visual Studio Code extension all talk to that port, and none of them talk to “AI on my laptop” in a general sense. If the program is down, you get “connection refused.” If three programs are up, your request might reach the idle one, the half-loaded one, or the container that crashed last night (a container is a packaged app that Docker, a common tool, runs in its own walled-off space).
Ollama uses 127.0.0.1:11434 by default. LM Studio’s local server commonly sits on 1234, and a llama.cpp llama-server in Docker often lands on 8080. Those numbers were checked in August 2026 and can change between versions. In our story, the saved command still said 8080 because it was copied from a blog post eleven days earlier, after a Saturday spent with Docker. Ollama was installed on Monday, and LM Studio was opened on Tuesday “to compare.” That left three listeners, three model folders, one prompt, and zero answers.
If the earlier post left you inside LM Studio and you have chatted once, stay there and close Ollama. This post uses Ollama because its command-line interface (CLI, meaning you type commands instead of clicking) is easy to paste and its documentation lives at ollama.com. Whichever you pick, run just one.
Rule of thumb: If Activity Monitor shows three model runners, you do not have a local stack. You have a port raffle.
The four pieces of the stack
When people say “I installed Ollama,” they mean four different things at once. Splitting them apart on purpose makes problems easier to find. The map below shows the setup you are keeping.
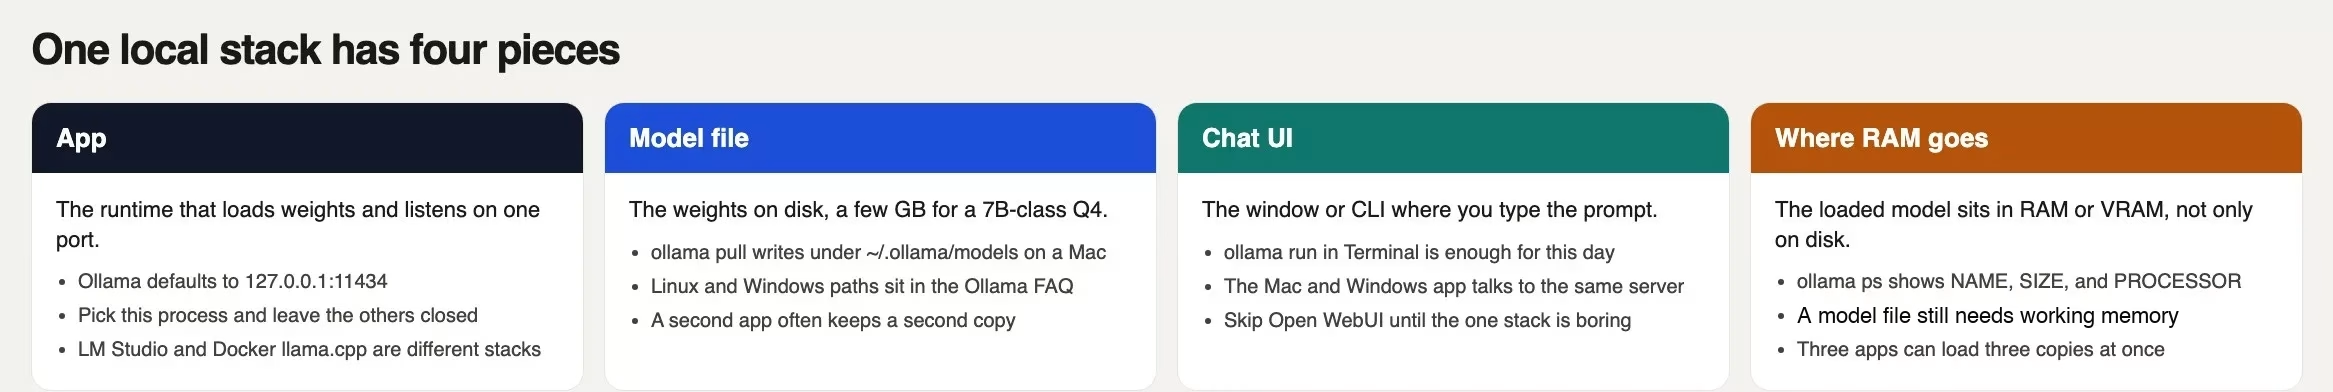
| Piece | What it is | In Ollama | Where RAM goes |
|---|---|---|---|
| App | The runtime that loads weights and listens | Ollama app plus the ollama CLI, port 11434 | Small until a model is loaded |
| Model file | Weights on disk | ~/.ollama/models on a Mac (see the FAQ for Linux and Windows) | Disk only, until you run |
| Chat UI | Where you type | ollama run or the app window | Almost none |
| Loaded model | Weights copied into memory | ollama ps shows NAME, SIZE, PROCESSOR | RAM or VRAM, often several GB |
Two commands keep the pieces straight: ollama list shows the catalog of files on disk, and ollama ps shows what is loaded in memory. In our story the 6.6 GB download (GB means gigabytes, a measure of disk space) sat on disk with nothing loaded, because the request never reached port 11434. Meanwhile LM Studio was using 2.4 GB of memory on a model nobody was talking to, and Docker Desktop held about 800 megabytes for a container that had already exited. That is how three programs use up memory without answering a single warehouse note.
Ollama’s public homepage now advertises both running on your computer and running in the cloud, so stay on a local model name. If a model line says cloud, your prompt leaves your machine, the same lesson as the earlier guide on hosted versus downloaded models. You can set OLLAMA_NO_CLOUD=1 or disable_ollama_cloud in ~/.ollama/server.json if you want the app to refuse that path.
A 30-minute Ollama path
Think of this as a worked clock. Use one terminal (the text window where you type commands) and one model name you confirmed on the library page this week. If the download is slow, wait, and do not fill the gap by launching LM Studio.
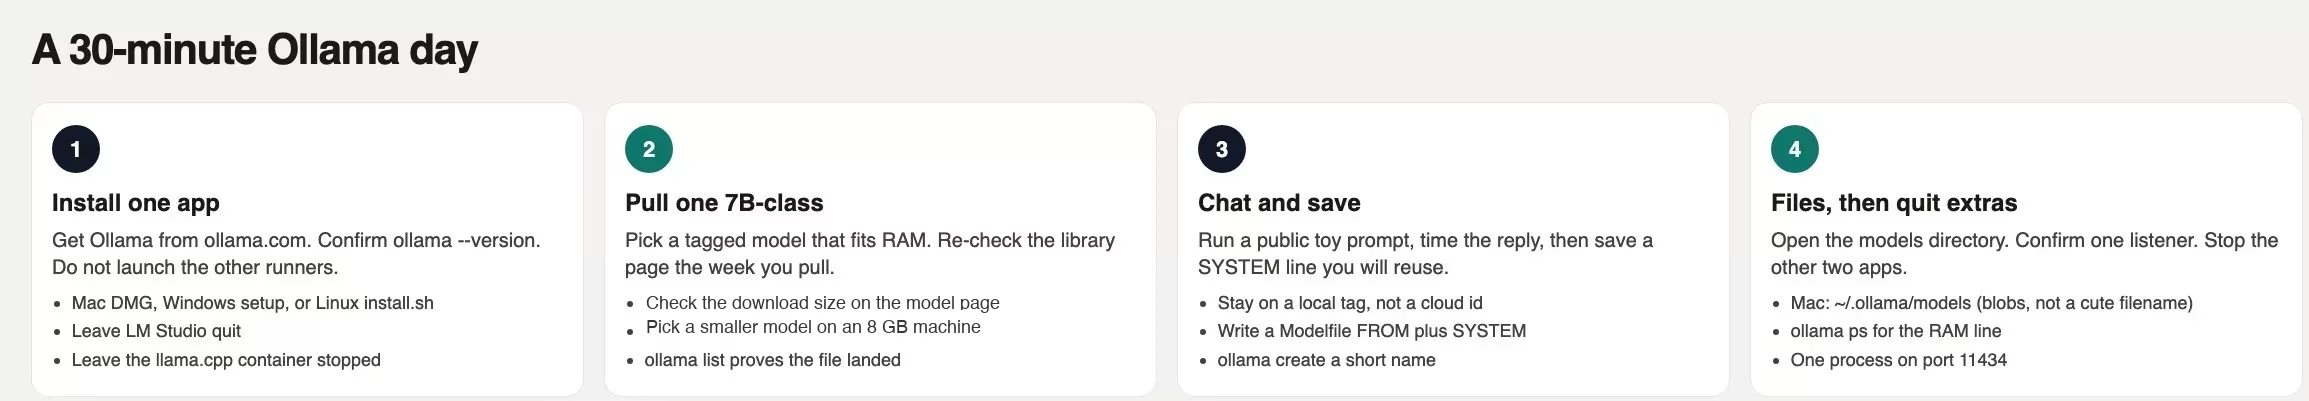
In the first five minutes, install from ollama.com/download. On a Mac you get an installer file (a .dmg file), and the current page asks for Sonoma or later. Windows has a setup program, and Linux documents curl -fsSL https://ollama.com/install.sh | sh. Then run ollama --version. If that command is missing, open a new terminal after the installer finishes, or use the app’s own window.
From minute five to minute eighteen, download one model of about 7 billion settings that fits in your memory (RAM, the short-term workspace your computer uses while it runs programs). On October 5, 2026, the library page listed qwen3.5:9b, a current Alibaba model, at about 6.6 GB, which is the neighborhood the guide to size and compression called laptop-sized. On a machine with 8 GB of RAM, switch to qwen3.5:4b, which is about 3.3 GB. Do not pull a model name with no size tag and hope for the best, because a name with no tag can resolve to a bigger default than you expect. Read the size on ollama.com/library the morning you download, since names and sizes move. The commands below show the shape of the job as of October 2026, not a permanent recipe.
# One local stack. Paste in order. Do not open LM Studio this hour.
# Re-check the tag and size on https://ollama.com/library this week (checked October 5, 2026).
# 16 GB RAM example: qwen3.5:9b (about 6.6 GB, Q4_K_M).
# 8 GB RAM: qwen3.5:4b instead (about 3.3 GB). Never pull an untagged 70B default.
ollama --version
ollama pull qwen3.5:9b
ollama list
ollama run qwen3.5:9b "Summarize this public sentence: The warehouse delay was ours."
ollama ps
Here is what that block does. The version command proves the CLI exists, and pull writes the model files to disk. list is your receipt, and run with a public toy sentence is your first chat. Finally ps shows whether the 6.6 GB model is now in memory, and whether the PROCESSOR column says the main chip (CPU, which runs your programs), the graphics chip (GPU, which does the heavy math), or a split between them. Time the reply. If the first sentence takes 20 seconds on the CPU, that is your hardware talking, not a broken install. Stay put, and do not add a second runner to go faster. One more public prompt in the same session is enough, and a confidentiality agreement is not something to paste in. The privacy paste test still applies even when the fan noise is yours.
Save a prompt you will reuse
Suppose you retype “make this a Slack status, five bullets, no hello” every time and still get a 200-word essay back. Save the instruction next to the model instead. Ollama’s way is a Modelfile, a small text file with a FROM line (which model files to use) and a SYSTEM line (how the model should behave). You create a tiny named model from that file, and tomorrow you run the name instead of repeating the speech.
FROM qwen3.5:9b
SYSTEM You turn messy meeting notes into 5 short Slack bullets. No greeting. No closing line. # Save as Modelfile in the folder where you will run the next two commands.
# Tags move; keep FROM in sync with what you pulled.
ollama create notes-status -f Modelfile
ollama run notes-status "Warehouse delay was ours. Carrier missed the 14:00 dock. Two pallets still on the floor."
On a good day that prints five bullets with the dock time and the pallets, and no “Happy to help.” If you get a speech instead, either the SYSTEM line is being ignored or the name after FROM is not the local file you think it is, so run ollama list and check. A text file on your desktop that you paste by hand is also a valid way to save the instruction. Skip Open WebUI and prompt libraries this week, because one SYSTEM line is the whole assignment.
Where the files live
Ollama does not drop a friendly llama-3.1.gguf (a model file format) into your Downloads folder. It stores hashed blobs, which are pieces with scrambled names, plus small files that describe them. If you look for a .gguf, find none, and install LM Studio “to get a real file,” that is how a second folder gets started. Look in the documented directory instead.
According to the current FAQ, macOS uses ~/.ollama/models, Linux with the stock installer uses /usr/share/ollama/.ollama/models, and Windows uses C:\Users\%username%\.ollama\models. You can point Ollama at a different disk with OLLAMA_MODELS and then restart the app. On Linux the ollama user needs write access to that folder, and you should never delete files in Finder while a run is live.
LM Studio keeps its own cache (a short-term memory the program keeps to work faster), and a Docker llama.cpp setup usually shares a ./models folder you chose. Three apps mean three copies. In our story the disk held about 6.6 GB in Ollama, 5.7 GB in LM Studio, and another 5.7 GB in a Docker volume, which adds up to 18 GB of near-duplicate model files. The size and compression guide covers size, and a later post covers heat and battery. For today, just know the path and know that it is not Downloads.
Stop the extra apps
This is the step people skip. Quit LM Studio from its menu, not only the chat tab, because on a Mac the menu-bar icon can keep the server running after the window is gone. For Docker, run docker ps -a, then docker stop the llama.cpp container if it is still listed. Quit Docker Desktop entirely if you only installed it for this.
Then confirm that exactly one listener remains.
# Expect one healthy local server, not a cloud id.
curl -s http://127.0.0.1:11434/api/tags
ollama ps
# Optional, macOS / Linux: who owns 11434, 1234, 8080
lsof -nP -iTCP:11434 -sTCP:LISTEN
lsof -nP -iTCP:1234 -sTCP:LISTEN
lsof -nP -iTCP:8080 -sTCP:LISTEN
What you want to see is tag information from port 11434, one row in ollama ps (or none, if you already stopped the model), and nothing listening on 1234 or 8080. If 8080 still answers, that is the Docker habit. If 1234 answers, LM Studio’s server toggle is still on. In our story, the command itself was perfect. It was just pointed at a program that was no longer running, and memory goes to whichever process loaded the model, not to whichever icon you clicked last.
Worked example: three processes, one dead port
Picture a Tuesday morning when your operations team drops 12 lines in Slack: the carrier missed the dock appointment, two pallets are on the floor, and the customer wants a time. You have a command from a llama.cpp guide, still aimed at 8080, and you hit return. It is refused. You spend 19 minutes restarting Docker Desktop because the guide said Docker, but the container turns out to have Exited (0) 14 hours ago. Ollama had been listening on 11434 the whole time with no model loaded, and LM Studio still had a Qwen model sitting in RAM from last night’s comparison.
| Process | Port | Status that morning | What your command hit |
|---|---|---|---|
| Ollama | 11434 | Listening, no model loaded | You did not send anything here |
| LM Studio | 1234 | App open, model half-warm | 2.4 GB RAM, unused |
| Docker llama.cpp | 8080 | Container exited | Connection refused |
| The 12-line note | (Slack) | Still in the thread | Rewritten by hand |
The fix that would have saved the morning was simple. Quit LM Studio, leave Docker alone, and run ollama run notes-status with the 12 lines. Even a cold 8B model on the CPU would have beaten 19 minutes of container logs. Instead you type the status yourself and tell the stand-up that “local LLMs are flaky” (an LLM is a large language model, the kind of AI behind chatbots). The flaky part was the port in the old guide. Write the working path on a sticky note with the app name, the port, the model name, and the models directory. A note that says only “llama.cpp 8080” is how this happens.
ollama run is not production self-host
- Installing Ollama, LM Studio, and Docker llama.cpp in one weekend, then sending requests to the one that is off.
- Pulling an untagged model that resolves to 70B, filling the disk, and blaming Ollama.
- Treating
ollama listas proof that the prompt is local, when a cloud name can sit next to the 6.6 GB file. - Hunting for a
.ggufin Downloads, then adding a second app to “see the file.” - Leaving LM Studio’s server on 1234, so two look-alike endpoints exist and your extension hits the wrong one.
- Skipping the saved
SYSTEMprompt, then deciding the 8B model “cannot write Slack.”
One model, one prompt, write the id
Block 30 minutes and use one app. If you already like LM Studio from the earlier post, stay there and skip the Ollama commands. If you are starting cold, paste the Ollama block above, download one 7B-class model that fits your RAM, and chat with a public sentence. Then save a SYSTEM prompt (in a Modelfile or a text file), open the models directory, quit the other two apps, and write the port on a sticky note. The next post covers first offline tasks, and the hardware side is in the post on RAM, graphics chips, heat and battery. Ordinary writing still goes through the products chooser, and the full catalog lives on the Learn page.
The Ollama-style day
- Pick one runner, close the other two, and send requests to the port that is up, so you always know which program answered.
- Know the four pieces: the app, the file on disk, the chat window, and the RAM shown by
ollama ps. - Pull one tagged 7B-class model, and re-check its size on ollama.com the week you run it.
- Save a SYSTEM prompt so every chat starts with the same instructions, and open ~/.ollama/models (or the FAQ path for your operating system).
- In our story the three processes were the outage, while the 8B file was fine.
Series notes
This is Part 3 of Run open models from scratch (series code OS10). Previous: friendly desktop runners from zero. Next: first useful offline tasks. Related: hosted vs download and size and quantization.
Sources
- Ollama (download, library, local and cloud modes; confirm which you are in)
- Ollama library (tags and file sizes the week you pull)
- Ollama FAQ (default port 11434, model directories,
ollama ps, cloud disable) - LM Studio (the other desktop runner; pick it or Ollama, not both this week)
- llama.cpp (engine under many apps; Docker server often on 8080)
- Meta Llama downloads (license and acceptable use if your tag is Llama)
- Analytics Made Simple: hosted vs local and desktop runners
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.