If you just want to try an open AI model such as Llama, Qwen, or DeepSeek, use a website that runs it for you instead of installing anything. Sites such as Groq, Together, Fireworks, and HuggingChat let you sign in and chat in minutes. Spend fifteen minutes on one model and one harmless task, then read the site’s page on how long it keeps your messages, because your words still travel to their computers.
Say you want to “try Llama” on your office laptop to polish a thank-you note for the warehouse lead. A tutorial tells you to start by installing graphics-card software, so you do. Seventy minutes later the installer still wants a newer driver, a setup step has failed, and your nine-line thank-you note still sits unfinished. You never even opened a chat box, and the note was due before Thursday.
This post is the version you can actually finish: a browser and a send button, with no compiler. CUDA stands for Compute Unified Device Architecture, and in practice it is NVIDIA’s toolkit for talking to a graphics card, which you do not need on your first night. One spelling trap is worth clearing up now: Groq (spelled with a q) sells fast hosting for open models, and it has nothing to do with Grok from xAI. Programs you install on your own laptop come in a later post, for the day you need the prompt to stay on the machine.
Skip the installer if you only need a chat
You wanted the nine lines to sound less stiff than your first draft in Notes. Someone on the team had said “use Llama, it’s open,” so you searched “run Llama locally CUDA” and landed in a stack that assumes you are building an engine. That stack means an NVIDIA driver, the CUDA toolkit, maybe a helper library called cuDNN, then llama.cpp or a 70B model file in the GGUF format (GGUF is short for GPT-Generated Unified Format). That path is real, but it is also how a quick start turns into an hour and ten minutes with no finished paragraph.
A hosted open-model chat website has already loaded those model files onto someone else’s graphics processor (GPU) hardware. You sign in, pick a named model, and type. You pay with an account, a rate limit (a cap on how many messages you can send in a period), and a prompt that leaves your device, so if that trade is acceptable for the task, do it first. Do not start with llama.cpp, which is the engine underneath a lot of local apps. The upcoming post on desktop runners puts a friendly window on that engine. Tonight you only need a box with a send button.
If the job is a public thank-you, the AI products chooser would probably have pointed you to a closed $20 chat subscription. This series exists for people who ask for open models by name, so that is the path we follow.
Rule of thumb: If you cannot point at a chat box within 15 minutes, you picked the wrong first tool. Installers make sense only after you know you need a machine of your own.
Hosted chat versus a download
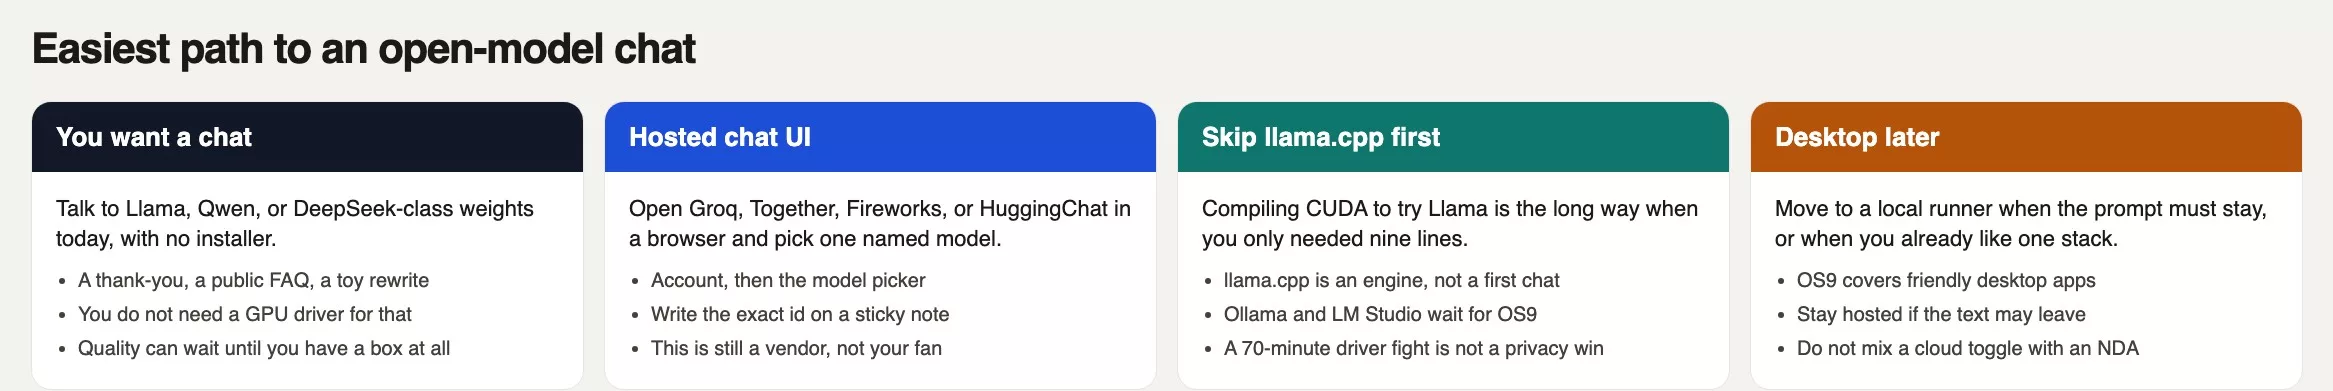
The earlier post on hosted versus downloaded models explained where the model runs. This post picks the hosted option. Hosted chat serves the same model files you could download, but through a browser. A download means Ollama, LM Studio (LM stands for language model), or llama.cpp plus a big file that has to fit in your computer’s working memory (RAM, where running programs keep their data).
| Question | Hosted chat UI | Download to your machine |
|---|---|---|
| What you install | A browser account on Groq, Together, Fireworks, HuggingChat, or a vendor chat that lists open models | Ollama, LM Studio, or llama.cpp, plus a GGUF or similar model file |
| First 15 minutes | Sign in, pick one named model, send one public prompt | Drivers, a multi-GB file, a memory check, then maybe a reply |
| Where the prompt goes | Their servers. Read retention the same day. | Your own memory, if you stay offline and you do not flip a cloud toggle |
| Speed on a big model | Usually fast, because the host bought the hardware | Often slow on a laptop, and you never got that far |
| When it is the right choice | You want Llama, Qwen, or DeepSeek-class chat today, and the text may leave | The text must stay put, or you already committed to one local stack |
One coworker watched a 4.7 gigabyte (GB) download crawl for 41 minutes, then switched to a cloud model id in the same app and got a reply at once. Llama is a family of model files, not a place you can visit. So on your sticky note, write the host first and then the model id.
Who these chat boxes belong to
Four kinds of website cover a first session. Product names change quickly, so the details below come from vendor pages checked in August 2026, and you should re-open the host’s site the week you click.
Groq playground
Groq sells fast hosting on its own chips. The try-it page is the GroqCloud Playground at console.groq.com/playground, where you can sign in with Google, GitHub, or email and then pick a model from the list. Groq’s public console in late August 2026 still showed OpenAI’s open-source gpt-oss models in 20B and 120B sizes, Qwen 3.6 27B, and Llama 3.3 70B on some pages. As of October 2, 2026, Groq’s deprecations page says Qwen 3.6 27B shut down on September 14, 2026, replaced by qwen/qwen3.8-27b. The same page told free and developer users to move off llama-3.1-8b-instant and llama-3.3-70b-versatile after 16 August 2026, so copy the id from the picker on the day you use it. Groq’s legal pages also name GroqChat at chat.groq.com, which is the same company under another label.
Together Chat and playground
Together AI runs a large catalog of open models. For a window shaped like ChatGPT, Together Chat at chat.together.ai is the consumer app. Together’s own posts in 2026 still pointed people there to try new models with no API setup (an API is the way a program asks a model for answers), and Kimi K3 in August was one example. If you want extra settings and a ready-made curl command, use the developer Playground at api.together.xyz/playground. Either one is hosted, which means your prompt travels to Together.
Fireworks playground
Fireworks AI is another big rental service for graphics hardware, and it has a model library you can click through. DeepSeek V4 Pro 0813, GLM 5.2 (GLM is a family of AI models made by the Chinese lab Zhipu AI, now called Z.ai), and Qwen 3.8 27B were on the public library in August 2026. Open a model page and use the playground from there, pick a serverless model, type your prompt, and watch the reply. This post stops at the send button.
HuggingChat and other vendor chats
HuggingChat is Hugging Face’s chat for open models. Its default is called Omni, which routes your prompt to some model in a large pool. For a first session, open the model list and pick one named id so you can write it down.
Some labs wrap their own open models in a branded chat, such as Qwen Chat or DeepSeek’s site. Those count if the picker names an open model. Meta AI at meta.ai is the trap, because in 2026 the flagship assistant there is not Llama running in a browser. Llama models still live on Groq, Together, Fireworks, HuggingChat, and downloads, so if you wanted Llama, the Meta AI tab was the wrong one.
For your fifteen minutes, pick one host so you can name it in a sentence. OpenRouter can wait, since it is a switchboard that routes between many hosts and not a first chat box.
Fifteen minutes, one named model
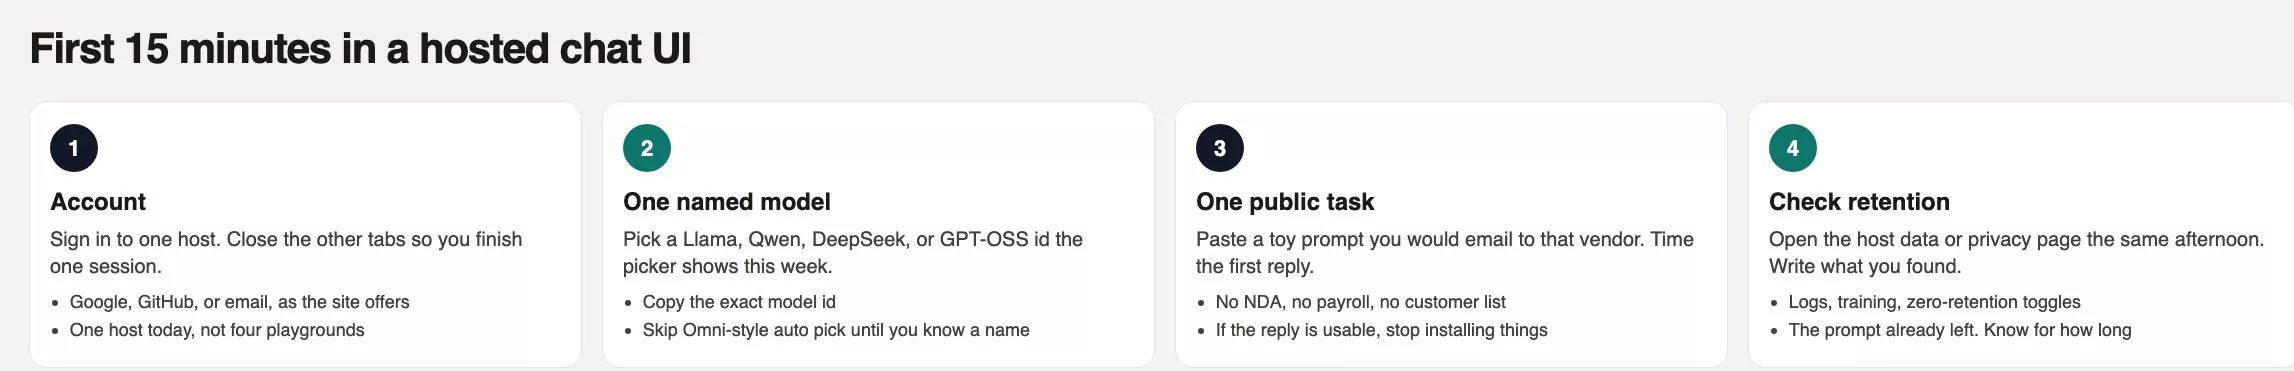
Set a 15-minute timer and commit to one host, one model, and one public task. The steps below go in order, and each one closes off a way the session usually drifts.
- Open one playground (Groq, Together, Fireworks, or HuggingChat) and close the other tabs, so you always know which host received your prompt.
- Create the account, and do not start a second account “to compare,” because comparing is a job for tomorrow.
- Pick one named model and write the exact id on the screen (
qwen/qwen3.8-27bor a Llama or DeepSeek id the picker still shows). If the site offers Omni or Auto, switch it off so you can say the name out loud. - Send one real task that is allowed to leave your device. The aisle 4 thank-you is a good size, because it is public, short, and free of any confidentiality agreement. Time the first reply, and if you like it, you are done installing things today.
- Open the host’s data or privacy page before you close the laptop. Look for retention, training, zero-data-retention switches, and the difference between playground logs and API logs. Then write two sentences about what you found on the sticky note under the model id.
The prompt still leaves your device
A Llama badge on a Groq tab does not make your laptop the computer doing the work. The prompt went to Groq. Together Chat’s “hosted in North America” line is a claim about geography and says nothing about staying local. Fireworks’ playground is Fireworks, and HuggingChat is Hugging Face plus whichever provider Omni picked for that reply. The post on why normal people care about open-model privacy is the longer version of this idea. The privacy paste test asks a simple question: would you email this PDF to that vendor?
Do not copy a blog’s privacy paragraph into a legal memo, and open the page yourself instead. Groq’s public “Your Data” docs, checked in August 2026, say default inference (the model doing its work to produce an answer) is not retained except for reliability and abuse logs kept up to 30 days, with a Zero Data Retention control in the console. Playground and consumer chats can keep more, because the product is a conversation history. Together and Fireworks publish their own notes, and those notes change. Assume logs exist until the page you opened this week says otherwise. If the thank-you includes a name you would not put in Gmail, do not put it in Groq either.
Worked example: 70 minutes for nine lines
Here is the thank-you as it sat in your Notes app, wrapped in an optional API call in case you prefer a script to a send button:
# First hosted session. Public toy only.
# Do this in a playground, or (optional) hit the Groq chat API.
# Never paste a live key into Slack, a ticket, or this file.
# In the shell only:
# export GROQ_API_KEY="paste-your-key-here-in-the-terminal"
curl https://api.groq.com/openai/v1/chat/completions \
  -H "Authorization: Bearer $GROQ_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen/qwen3.8-27b",
    "messages": [
      {"role": "user", "content": "Rewrite this public thank-you in nine short lines. Keep aisle 4 and Thursday. Text: Thanks for the warehouse walkthrough. The slotting map on aisle 4 was the piece we needed. Attached is the one-pager. See you Thursday."}
    ]
  }'
The curl command is there to show you can talk to a named open model without a compiler. The playground does the same job with a send button, so use whichever feels easier. If the model id comes back with a 404 error, the host has moved its list, and Groq did exactly that to older Llama ids in August 2026. Open the picker, paste the new id, and keep the toy prompt. If you do not want an API key (a password that lets a program use the service) yet, skip the script and use the checklist below.
# First 15 minutes, no CUDA
# [ ] One host tab only (Groq / Together / Fireworks / HuggingChat)
# [ ] Account created
# [ ] Exact model id written down
# [ ] Prompt is public (would you email it to that vendor)
# [ ] First reply timed
# [ ] Retention page opened the same afternoon
# [ ] Sticky note: host name, model id, "leaves the building"
# Stop. Do not install llama.cpp today.
The table compares two versions of the same evening. In one you start with the CUDA installer, and in the other you start with a hosted chat.
| Minute | CUDA path on your laptop | Same thank-you in a hosted UI |
|---|---|---|
| 0 | CUDA installer starts | Opens console.groq.com/playground, signs in |
| 6 | Progress bar, driver warning in small type | Picks qwen/qwen3.8-27b (or the Llama id on screen), sends the nine lines |
| 8 | Still installing | Paste, edit two adjectives, send the note |
| 70 | nvcc missing, no chat box, 70 minutes gone | Retention page skimmed, sticky note written |
| Thursday | Warehouse lead still waiting, or you used Gmail after all | Thank-you already sent |
A coworker two desks over took the hosted path in the time you would spend reading the CUDA license screen. He still has to tell legal the host name if his next paste is a confidential document. What he did not have to do was hunt down a graphics driver for a thank-you.
Common mistakes
- Installing CUDA “to try Llama” when a playground would have finished the job.
- Saying Groq when you mean Grok, or opening meta.ai and calling it Llama.
- Calling a Groq or Together tab “local” because the model name is Qwen.
- Letting Omni or Auto pick the model, and then being unable to write the id on the sticky note.
- Pasting a confidentiality-covered document, payroll, or a customer list into the first session “because it is open source.”
- Starting llama.cpp on day one, when that engine belongs later with a desktop runner.
Practice this week
Pick one host and run the 15-minute list on a public paragraph you already wrote. Put the host, the model id, and the words “leaves the building” on one sticky note. If the reply is good enough, stop there. If you need the prompt to stay on your laptop, wait for the post on desktop runners and skip the CUDA detour. If you want the location question again, revisit the hosted versus download comparison. For what “open” actually means, read what open means for AI models, and for more paths see Learn.
Quick recap
- If you want Llama, Qwen, or DeepSeek-class chat with no install, start with a hosted website.
- The plan is one account, one named model, one public task, and one look at the retention page, all in fifteen minutes.
- Groq is not Grok, and a Llama badge on a website does not mean the model is on your disk.
- Do not start with llama.cpp. Desktop runners come in the next post.
Series notes
This is Part 1 of Run open models from scratch (series code OS8). Next: friendly desktop runners from zero. Related: hosted vs download, privacy, and privacy paste test.
Sources
- Groq (inference cloud; not xAI Grok) and GroqCloud Playground
- Groq model list and Groq: Your Data (retention, checked in August 2026)
- Together AI, Together Chat, and Together Playground docs
- Fireworks AI and Fireworks inference intro (model playground)
- HuggingChat
- llama.cpp, Ollama, and LM Studio (later in this series, not today)
- Analytics Made Simple: hosted vs download and Analytics Made Simple: privacy paste test
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.