To run an AI chatbot on your own laptop, install one free app, download one small AI file, and try one harmless question. Then check two things: the setting that quietly sends questions to the internet, and the folder where the big file lives. Apps such as Ollama and LM Studio (LM stands for language model, the kind of AI behind chatbots) download that file and give you a chat box that runs on your own computer. Installing several of them at once is how the same few gigabytes end up on your disk three times.
Say your laptop has 18.4 gigabytes (GB) of free disk space on Monday evening. By late that night the Storage screen shows 3.7 GB, and your Mac refuses to save a PDF. You installed three apps for running AI on your own laptop, Ollama, LM Studio, and one more from a screenshot a friend sent, and each one downloaded the same mid-sized AI model file. That is three copies of the same 4.9 GB file. Each app names its folder differently, so nothing looks duplicated.
This post covers the first night: one official installer, one small model file, and one harmless question. Skip any guide that asks you to build the app yourself from its code, and stick with one app for 30 days.
A runner is a box around weights
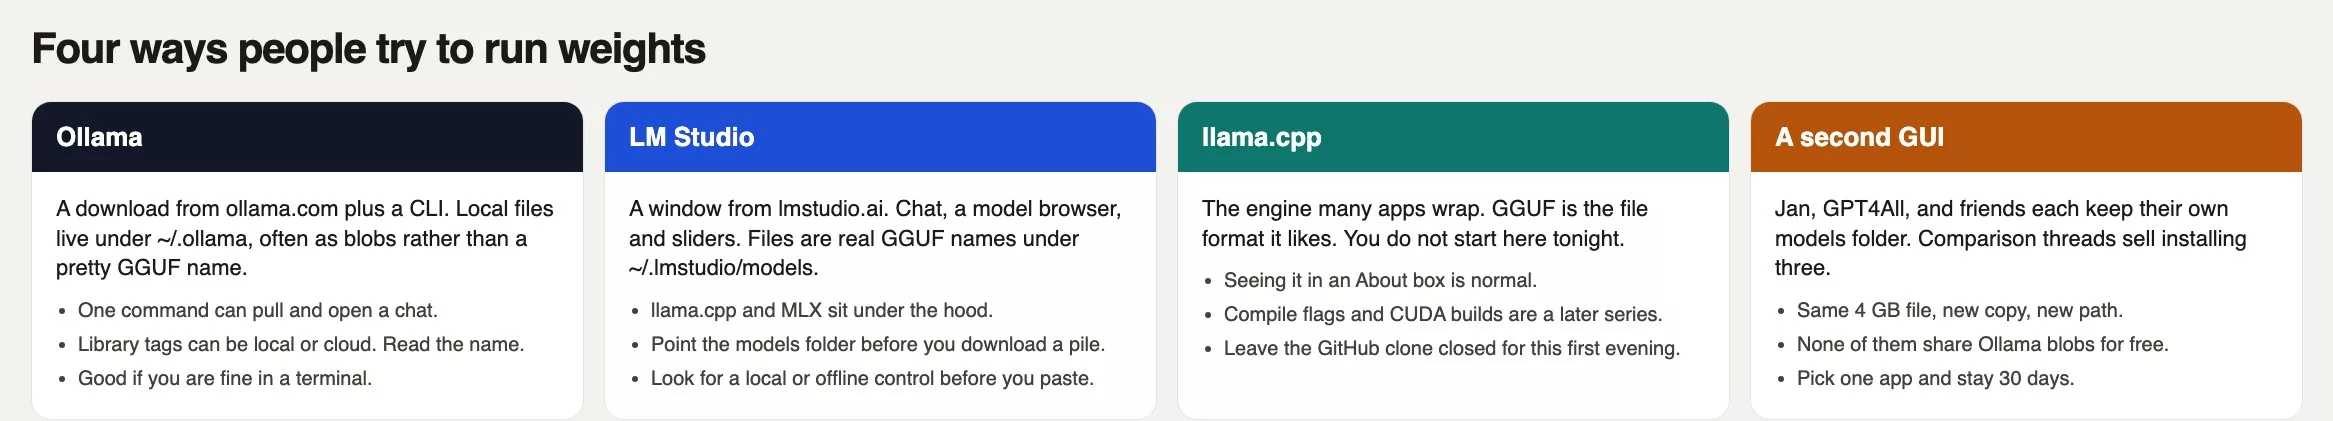
A desktop runner is an app that downloads a model file, loads it into your computer’s working memory (RAM) and its graphics chip (GPU) if you have one, and gives you a chat box. You are not training anything. You are asking a compressed file, often a GGUF (the common single-file format for these models), to finish a prompt on this machine. The guide to size and quantization (squeezing the model into a smaller file) covers how big these files get. Tonight you only need a few gigabytes, small enough that the Storage screen does not complain.
Ollama is the one-command path that many people finish. You install it from ollama.com and then talk to it in a terminal (the text window where you type commands), and it also has a small menu-bar app. LM Studio is a window from lmstudio.ai with a model browser, a chat, and sliders for the graphics chip. Both wrap an engine, and that engine is often llama.cpp (on Apple Silicon, LM Studio also talks to a second engine from Apple (MLX)). Llama.cpp gets its own later series. If an install page tells you to clone it, build it, and pass flags for a graphics toolkit, close the tab.
Other apps exist too, such as Jan, GPT4All, and KoboldCpp. Each keeps its own models folder unless you do extra work. In our story, the chat thread treated “install all three” as research, but it was really three installers filling one drive.
Rule of thumb: One runner for 30 days. A second app is a second copy of the file until you prove otherwise.
Pick one app and stay there
You do not need a bake-off on night one. The quality gaps among 8B-class compressed files are smaller than the gap between “it runs” and “the disk is full.” Tonight you need one official installer, one small local model, and one prompt that you would be comfortable pasting into email. Fan noise, memory, and battery wait for the post on RAM, graphics chips, heat and battery.
| Path | What you install | Where a ~5 GB file lives | Start here if |
|---|---|---|---|
| Ollama | App and CLI from ollama.com | ~/.ollama/models (blobs, not a pretty filename) | You are fine in a terminal and want one command |
| LM Studio | Window from lmstudio.ai | ~/.lmstudio/models/publisher/name/*.gguf | You want a chat window, a download button, and sliders |
| I’ll compile it | llama.cpp from GitHub, a compiler, flags | A folder you pick, a GGUF you named | You already build C++ and you like issue trackers |
If you like a terminal, pick Ollama. If you want a slider that decides how much work goes to the graphics chip, pick LM Studio. The compile path is for people who already have a compiler set up, and in our story the laptop had three About boxes and no compiler.
Ollama does not store a friendly model-q4.gguf that you can drag into LM Studio. It stores content-addressed blobs (pieces named by a fingerprint of their contents) under ~/.ollama/models, while LM Studio stores publisher-and-name GGUF files. Sharing one folder between them is optional homework and not for tonight. If you install both and press Download in each, you pay 4.9 GB twice, which is the whole story of the full disk.
Install from the official site
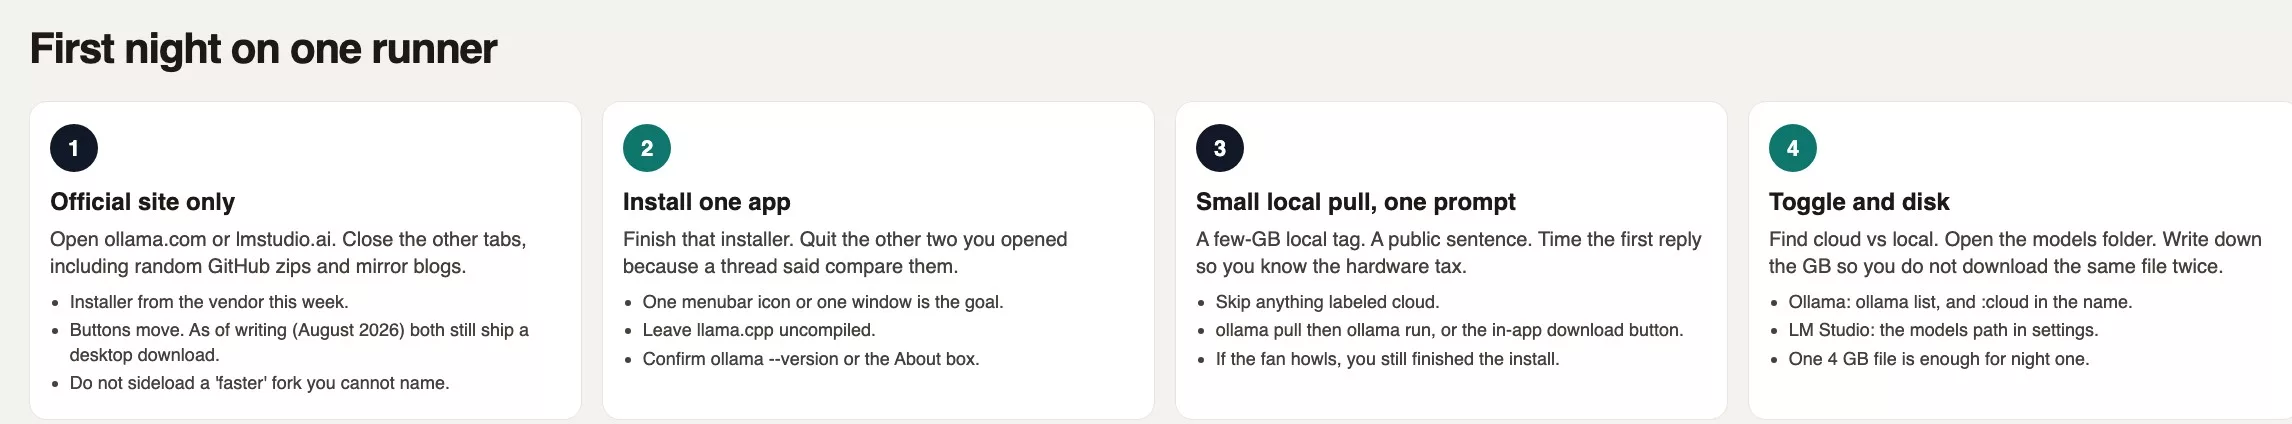
Open one of two addresses and close the rest, so you download the real installer and not a copy from an unofficial site.
- Ollama: ollama.com/download (a Mac installer, a Windows installer, and a Linux install script in the docs)
- LM Studio: lmstudio.ai (the site detects Mac, Windows, or Linux)
In August 2026 Ollama’s homepage sells “on your computer” and “in the cloud” in the same breath. LM Studio still leads with a desktop app, and it also markets local agents and cloud-adjacent services with names that keep changing. Confirm the vendor domain before you download, because a GitHub copy of llama.cpp is not an installer, and neither is an .exe file re-hosted on somebody’s blog.
Mac, Windows, Linux in one pass
On a Mac, drag Ollama into Applications, or open the LM Studio installer file. Allow the permission prompts for the one app you chose. On Windows, run the vendor’s .exe. Ollama installs under your user profile (in August 2026 the program files landed in %LOCALAPPDATA%\Programs\Ollama) and puts ollama on your command path once you open a new terminal. On Linux, Ollama’s docs show curl -fsSL https://ollama.com/install.sh | sh. Read that script on the official page the week you run it, and do not paste a similar line from a chat thread.
- Ollama: open a new terminal and run
ollama --version(orollama -v) before you download 5 GB. You want a version string, not “command not found.” - LM Studio: open the window, open About, and write the version on a sticky note. Look at Settings for a models directory before you download. The default is
~/.lmstudio/models(on Windows,C:\Users\<you>\.lmstudio\models). If your C: drive is tight, change that path first.
Pull one small model, send one prompt
Small means a few gigabytes, so pick a 3B-class or 8B-class compressed file and not a 70B model from a leaderboard. Model names in each app’s catalog change quickly. As of October 2, 2026, Ollama’s quickstart uses gemma4 tags, but you should not tattoo a tag from this page onto a runbook. Open ollama.com/search or LM Studio’s Discover tab the week you install, and pick a line that is a few gigabytes and does not say cloud.
Ollama needs two verbs on night one, and they are in the block below.
# Shape only. Confirm the tag on https://ollama.com/search.
# Pick a small LOCAL model. Skip anything labeled cloud.
ollama --version
# If this tag 404s, take the current small local model from the library.
ollama pull qwen3.5:4b
ollama list
# A NAME ending in :cloud means the prompt leaves your computer.
ollama run qwen3.5:4b
# >>> Summarize this public sentence: The warehouse delay was ours.
# >>> /bye
If the first words take 20 seconds to appear, that is your hardware talking, not a broken install. Do not “fix” it by switching to a cloud name in the same window. Write the number of seconds on the sticky note, and keep the prompt public. A vendor’s confidential PDF still belongs under the paste test.
In LM Studio the same night is all clicking. Open Discover, pick a GGUF that the app marks as fitting your memory, then press Download, Load, and Chat. Type the same public sentence. If the interface offers “cloud,” “host,” or a giant model that would not fit, you have left the local path, so unload it.
Find the cloud or local toggle
A model can be labeled local and still send your text to a company. In an earlier post in this series, someone pasted a confidential agreement after flipping a cloud switch without noticing. In our story nothing leaked over the network, but disk space did leak. You can do both in one evening if you skip this section.
Ollama: the name is the toggle
Ollama’s documentation describes cloud models as tags that hand the work to their servers while you keep using the same command-line tool. The quickstart used a :cloud suffix, and gemma4:cloud was the shape. You sign in with ollama signin. A cloud pull does not put a 70B model on your drive, because it only puts a small stub, and the prompt still leaves your machine.
Run ollama list and read every name in the list. If one says cloud, do not paste anything you would not email to that company. Their FAQ says local runs stay on your machine, while cloud-hosted models process your prompts to provide the service. To force local-only, set disable_ollama_cloud in ~/.ollama/server.json, or set OLLAMA_NO_CLOUD=1, and restart. The list is the map, and the progress bar is not.
LM Studio: settings before the first paste
LM Studio’s pitch is local chat, but its marketing also mentions cloud services and a local agent (an AI that takes actions on its own) with its own name. Open Settings, find the models directory, and look for anything that says cloud, host, or account. If a file must not leave your machine, stay on a loaded local GGUF and keep the computer offline after the download. A window on your desktop does not prove where the work happens, and the earlier post on hosted versus downloaded models covered that.
Where the 4.9 GB files live
Ollama’s FAQ lists these default folders.
- macOS:
~/.ollama/models - Linux (default install):
/usr/share/ollama/.ollama/models - Windows:
C:\Users\%username%\.ollama\models
You can change the directory with OLLAMA_MODELS and then restart the app. On a Mac that often means launchctl setenv plus a restart, because the menu-bar app does not read your shell settings file. On Windows you set a user environment variable (a named setting the app reads when it starts), quit the tray app, and start it again. If you skip the restart, the next 4.9 GB still lands on your C: drive.
LM Studio expects a tree shaped like ~/.lmstudio/models/publisher/model/file.gguf. If search cannot see a GGUF you dropped in by hand, the folders are the wrong shape. Their command-line tool can import a file with lms import path/to/model.gguf, which the current docs call experimental. Change the models directory in the interface while it is still empty and then download, so you do not have to babysit a 15 GB move later.
Hidden folders explain the late-night surprise. Both .ollama and .lmstudio start with a dot, so they do not sit on your Desktop, and you have to open the path yourself. Sort by size. If you see 4.9 GB three times, you are looking at three runners and not three different models.
Worked example: three copies of 4.9 GB
Say you wanted “Llama on the laptop” and a chat screenshot listed three apps with a rocket emoji. All three advertised the same 8B compressed file, and none of them reused a file. Here is what you would find afterward.
| App | Folder you find later | What Storage added | Same weights? |
|---|---|---|---|
| Ollama | ~/.ollama/models (blobs + manifests) | +4.9 GB | Yes, hashed pieces, no .gguf name |
| LM Studio | ~/.lmstudio/models/publisher/name/*.gguf | +4.9 GB | Yes, a real GGUF filename |
| Third app | Its own models directory under the user profile | +4.9 GB | Yes, a third copy |
Start with 18.4 GB free and subtract 14.7 GB of copies. You are at 3.7 GB before the apps themselves take their share, and that is how you get a Finder error on a PDF. The fix is boring, since you quit two apps, uninstall two, keep one, and delete the extra model folders after the keeper still chats. Do not keep LM Studio “for the interface” and Ollama “for typing commands” on night one. The one local stack post is the stack you stick with.
The useful leftover from that night is a sticky note with the app name, its version, the model name, 4.9 GB, “local (no cloud in the list),” and the time to the first word. That note is the start of the next post in the series. Three About boxes is not a stack.
The store tile is not a model card
- Installing three runners because a comparison post had a table.
- Starting from llama.cpp because an online thread called the friendly apps toys.
- Pulling a
:cloudtag, then telling a teammate it is local because the tool is named Ollama. - Leaving the models directory on a 256 GB system drive, then downloading a second 8B file “to compare quants.”
- Pasting a confidential agreement into the first prompt “to see if it works,” when a public sentence would do.
- Grabbing an installer from a random GitHub zip or a mirror blog.
Install one runner, load one small file
- Pick Ollama or LM Studio, and close the other tab, because two runners compete for the same memory and make your first test confusing.
- Download from the official site, and confirm the domain in the address bar.
- Run
ollama --versionor write down the LM Studio version from About, because the version tells you which instructions and fixes apply to you. - Pull one small local model, send one public prompt, and write down the seconds until the first reply.
- Run
ollama list(or open the in-app model list), confirm nothing says cloud, and take a screenshot. - Open the models folder and write down the path and the size in GB. If you already have two copies, delete one app tonight.
The next post is one local stack, which assumes you kept one runner. A thank-you paragraph still belongs in the chooser, not in a 14.7 GB science fair.
Desktop runner, then a tiny model
- Use one official app, either Ollama or LM Studio, and not both or llama.cpp tonight, because two programs fighting over the same memory make your first test fail for the wrong reason.
- Load one small local model, send one public prompt, and read the list for cloud tags.
- Find the folder, because a 4.9 GB GGUF copied three times means three runners and not research.
Series notes
This is Part 2 of Run open models from scratch (series code OS9). Previous: easiest path: hosted open model chat. Next: one local stack end to end. Related: hosted vs download and Open-source AI explained.
Sources
- Ollama and the download page (desktop app and command-line tool; local and cloud on the same site)
- Ollama quickstart (run a model, including a cloud-shaped tag) and Ollama Cloud
- Ollama FAQ (model paths,
OLLAMA_MODELS, how to disable cloud features) - LM Studio (desktop app) and import / models directory
- llama.cpp (engine many GUIs wrap; not the night-one installer)
- Hugging Face: GGUF (the file format behind those 5 GB downloads)
- Groq (hosted inference; not xAI Grok) and hosted open model chat
- Analytics Made Simple: hosted vs local and Learn
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.