If your household shares a laptop that runs a local AI model, give each person their own computer login and start a new chat before you hand it over. A kitchen laptop that runs a local AI model is a shared brain. Anyone who signs in under the same computer login can read old chats, open attached files, and reuse whatever model is already loaded. Local means your prompt may stay off a vendor’s servers, but it does not mean the chats are private from the people who share your house.
Picture a laptop with a crooked lemon sticker on the lid, sitting in the kitchen with the chat app still open from your child’s homework. Your child has asked for a science-fair paragraph on fermentation, and you sit down to help. The sidebar lists 11 threads, and the third from the top is titled “week 6 notes.” You click it because it looks like a grocery list. It is not one. The first reply is a six-line summary of your partner’s therapy journal, a 2,800-word paste that your partner dropped in over lunch. Nobody went hunting for it, since your child was using the same computer login that you never signed out of.
This post is about chat history, saved files, and who can reach the app over the network. The menu names below come from vendor docs checked in August 2026.
A family Mac is not a team server
One kitchen laptop is a shared brain that holds chats, dropped files, and a small program listening for requests on a local network port (a numbered entry point into the computer). Sharing one login, sharing the machine with separate logins, and running a real team host are three different setups. Write down which one you have before you invite a partner, a child, or a coworker. Later you will see what 127.0.0.1 versus 0.0.0.0 means on public Wi-Fi, how to print a household rules card, and how to run a two-command check for who can reach the port.
One laptop, one memory
A local model keeps your prompt on your own computer, away from any AI company’s machines, as long as you stay in local mode. The earlier post on hosted versus downloaded models covered the cloud toggle that still exists in some apps. Even in local mode, the prompt lives in memory, on disk wherever the app stores it, and on the screen. Anyone under that computer login can scroll the sidebar, reopen “week 6 notes,” and read the six lines, and they can drag the next PDF from the Desktop into a new chat. Local answers the question “did this leave the house?” It does not answer “who else in the house is this?”
Three things live in that one window. The first is your chat history, which includes titles, full conversations, and attached files. The second is the model files, which are large downloaded files in a format called GGUF (a common file format for local models), stored under ~/.ollama/models on macOS or in the path the Ollama docs list under your user folder on Windows. The third is the network listener. Ollama’s docs in August 2026 said it listens on 127.0.0.1 port 11434 unless you change the OLLAMA_HOST setting. LM Studio’s developer server (LM stands for language model) is similar, often on port 1234, with a “Serve on Local Network” switch that opens it beyond this one computer. The llama.cpp server can do the same. None of these local web APIs (connections that let other programs send the model questions) ask for a household password, and Ollama’s authentication docs say no login is required on http://localhost:11434. That is convenient for you, and it becomes a hole whenever the listener is open wider than this one machine.
Your child used the open login because it was already there and the homework was due. Your partner used the only chat on the only account, named the thread like a journal heading, and went back to cooking. Nobody in this story is a villain. The shared brain was enough.
Rule of thumb: If two people can sit in the same computer login, they share the sidebar. Name the login the way you would label a filing cabinet.
Share a login, share a machine, or run a real host
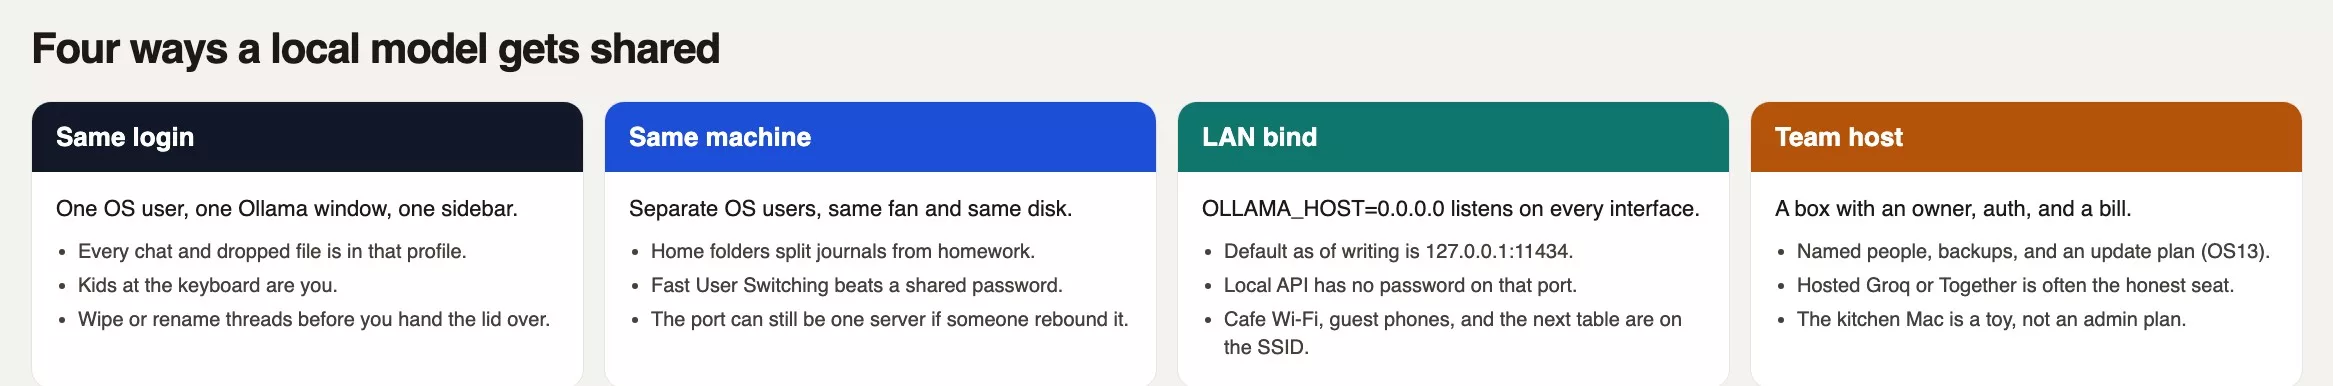
People say “we share Ollama” and mean three different setups. Write down which one you actually have before you invite a partner, a child, or a coworker.
| Mode | What you share | Who sees the chats | Who can hit the API |
|---|---|---|---|
| Share the login | One OS user, one runner app, one ~/.ollama | Anyone at that keyboard, including a child on homework | This machine only, until someone changes the bind |
| Share the machine | Separate OS users, same laptop, same fan | Each user’s own chats if they signed out | Still localhost per session, unless a service was rebound for everyone |
| Real team host | A box with an owner, backups, and a written update plan | What that product logs, on purpose | Named people on a private network, with auth in front of the port |
Sharing the login is what you had in the story. It is fine for a solo laptop and wrong the moment a second person types. The cheap fix is social: start a New Chat, delete the private thread, and title the rest with a name. The better fix is one computer account per adult. It takes two minutes. Fast User Switching on macOS is slower than saying “here, use mine,” but it keeps your partner’s journal in your partner’s home folder and your child’s homework in your child’s.
Sharing the machine still shares heat, memory, and disk space. The earlier hardware post explained that a laptop with 16 gigabytes (GB) of memory gets unhappy running an 8B-class model (one with about 8 billion adjustable settings) while Chrome is also open. If your child loads a model before dinner, your evening work waits for it. Agree on who may run a model the same way you agree on who may render video.
A real team host is a different kind of thing. Someone owns the updates, as the earlier post on updating models described, and someone owns the backups of the model folder. Someone can also say who may call the API. A kitchen Mac with OLLAMA_HOST=0.0.0.0, set so that three laptops can send requests to it, is a toy server. Toys are fine on a Saturday. Monday is different. A toy is not an admin plan when an intern pastes in a customer spreadsheet.
Who can reach this port
The address 127.0.0.1 means this computer talking to itself. Apps on the same Mac can reach Ollama there, and a phone on the Wi-Fi cannot. The address 0.0.0.0 means listen on every network connection the machine has. The home network is one connection, and a cafe network is another. Ollama’s FAQ documents how to set OLLAMA_HOST to 0.0.0.0:11434 when you want other devices on a network to connect. Treat that page as a warning label that happens to include an on-switch.
In August 2026, that local API still did not ask the caller to log in. A second device that can open http://192.168.x.x:11434/api/tags can list your models, and the generate and chat endpoints use the same kind of web request. LM Studio’s network-serve page says plainly that any address other than 127.0.0.1 exposes the server beyond your own computer, and it recommends turning authentication on. If you need a phone in the house to talk to the Mac, make that a deliberate decision with a firewall rule. Do not leave it on when you close the lid and walk to a coffee shop.
Cafe Wi-Fi is the sharp case. You sit down, the laptop joins the network called Airport_Free, and a leftover launchctl setenv OLLAMA_HOST 0.0.0.0:11434 from last weekend’s demo is still in the environment. The runner comes up when you open the lid, and anyone else on that network who scans common ports can find 11434. They do not get your Apple password. They get an open web address for the model that will run whatever prompt they send against the weights (the model files) you loaded, using your memory and your battery. Home is calmer. It is not empty either, since guest phones, a friend’s laptop, or a neighbor on an open guest network can all reach it. You need to know whether the listener is limited to this computer or open to the network. Two short commands answer that, along with a look at who is on the network.
A household rules card
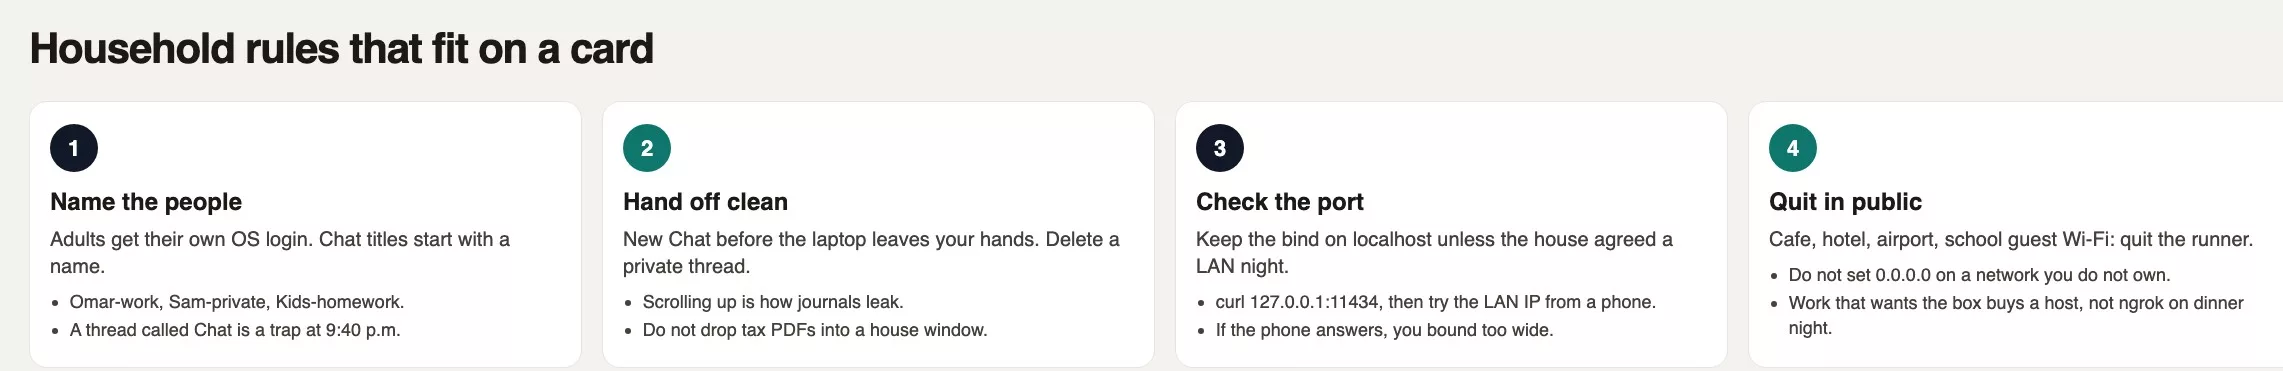
Print this card and tape it under the trackpad or on the inside of the lid. Change the names, and keep the line about where the listener is bound. The comments are part of the card so the next adult can read why each rule exists.
# KITCHEN OLLAMA CARD  (print, tape under the trackpad)
# House: Parent / Partner / Kid. Stack: Ollama. Checked August 2026.
# 1. Adults have separate macOS users. The kid uses "Kids", not a parent login.
# 2. Chat titles start with a name: Parent-work, Partner-private, Kids-homework.
# 3. Before you hand the laptop, New Chat. Delete a private thread.
# 4. Journals, tax PDFs, and work decks stay out of a house window.
# 5. Bind stays 127.0.0.1:11434. Nobody sets OLLAMA_HOST=0.0.0.0
#    without a Saturday talk the rest of the house hears.
# 6. Cafe, hotel, airport, school guest Wi-Fi: Quit Ollama in the menu bar.
# 7. If work wants "our home box," the answer is no. They buy a host.
# 8. Models live in ~/.ollama/models. Do not "free space" there on a school night.
# Who can hit this port? Run on the Mac that hosts the runner.
curl -sS -o /dev/null -w "localhost:%{http_code}\n" --max-time 2 http://127.0.0.1:11434/api/tags
# 200 means the app is up on loopback. Now try this laptop's LAN IP
# from a phone on the same SSID (Wi-Fi details in System Settings):
# curl -sS -o /dev/null -w "lan:%{http_code}\n" --max-time 2 http://192.168.1.47:11434/api/tags
# If the phone gets 200, you bound too wide. Clear OLLAMA_HOST, restart.
# macOS leftover from a demo (only if you set this on purpose):
# launchctl getenv OLLAMA_HOST
# If that prints 0.0.0.0:11434 and you did not mean LAN night, unset it and reopen Ollama.
The card is meant for a 30-second read at the table. Line 2 is how you would have seen “Partner-private” instead of “week 6 notes.” Line 3 is the handoff step, and line 5 with the two commands is the only technical part. Flags and menu labels change over time. If the command fails, the app may use another port, so check the runner’s status screen that week.
A small team is not the kitchen box
Three people in a shop will try this. They set up one quiet desktop with a 12 GB model that “almost feels like ChatGPT,” set OLLAMA_HOST=0.0.0.0, and post the machine’s address in chat. It works until someone needs an audit trail, or until two prompts queue up and the fan becomes the office soundtrack. It also breaks when an intern opens the port to the internet with ngrok “for a client demo,” or when an update lands a new default model and Tuesday’s summaries suddenly sound different. Ollama’s FAQ even shows ngrok and Cloudflare Tunnel examples. Those tools put your local port on the public internet, which is a product decision that needs a login and encryption, not a dinner-table experiment.
If the work is real, pick a host you can name. A hosted open-model API from Groq (a company that runs models for you, which people call inference, spelled with a q and not xAI’s Grok), Together, or Fireworks gives you a key, a bill, and a data-retention page you can actually read. A small rented server with a reverse proxy (a front-door program that checks a password) is the do-it-yourself version of the same thing. The kitchen Mac can still be the place where you try prompts that must not leave the house. It should not be where accounting, support, and a contractor all point their laptops. Before you share a port at work, write four lines on a sticky note: who owns the box, who may download models, where the disk lives, and what happens when the person who set it up is on vacation. If you cannot fill those lines in, you do not have a team host. You have one person’s laptop with extra visitors. That is a fine thing to have, as long as you call it what it is.
A worked example: 11 threads on a shared laptop
Here is the evening from the opening story as a table you can reuse, with the numbers from the lemon-sticker laptop.
| When | What happened | What was shared | Fix that would have held |
|---|---|---|---|
| At lunch | Your partner pasted 2,800 words, titled the thread “week 6 notes” | The full journal, in the only OS user | Partner-private on your partner’s login, then sign out |
| Before dinner | Your child opened Ollama, still running under your login | 11 titles in the sidebar, including week 6 | Kids login, or you quit the app after lunch |
| After dinner | Your child asked for a fermentation paragraph; model used the loaded 8B | Fan, RAM, and the same window your partner used | Fine, if the sidebar had no private titles |
| Late evening | You clicked week 6, read a six-line summary | Therapy content, now in your head too | Delete thread after use; name chats; separate users |
The 10-minute fix that night went like this. Your partner created a separate macOS account. You deleted “week 6 notes” from your sidebar, and the paste was already safe in your partner’s original file. Your child got the Kids login and a chat titled Kids-homework. You ran the localhost command, which answered with 200, and then the address-based command from your phone, which said the connection was refused. Nobody set 0.0.0.0, and the card went under the trackpad. If a child is in the mix, read the guide to kids and shared devices for closed-chat age gates, Family Link, and Screen Time. That post covers ChatGPT on an iPad, while this one covers Ollama on a laptop. The shared-brain problem has the same shape in both. The control here is the computer account plus the port, because your runner may not ship a family plan.
Sharing a folder is not a policy
- Leaving one computer login open “because it is the house computer,” then being surprised that the sidebar behaves like a group chat.
- Titling private threads like grocery lists (
week 6 notes,stuff,Chat). - Setting
OLLAMA_HOST=0.0.0.0:11434for a living-room demo and never unsetting it. - Opening the port wide on cafe, hotel, airport, or school guest Wi-Fi, or leaving the runner up in a bag on those networks.
- Calling a network address in a chat message “the team server” with no login, no owner, and no backup of
~/.ollama/models. - Opening port 11434 to the internet with ngrok or Cloudflare because a FAQ snippet showed the command.
- Letting kids use a work login, or letting work use the kitchen box. The guide on kids and shared devices and the privacy paste test still apply, because local does not cancel them.
- Deleting the models folder to “clean the disk” the night before a science fair. The earlier post on updating models explains where those files live and why they matter.
One rule card on the machine
Sit at the actual table and open the runner. Count the threads, and rename any that a child or a partner should not open. Delete the one you would not read aloud. If two adults use the machine, make the second computer account now. Then run the two commands, and if a phone can reach port 11434, set the listener back to localhost and restart. Quit the app once on a network you do not own, so the habit exists before you need it. Write the four team lines only if someone at work asked.
This series stops here on purpose. Earlier posts covered hosted chat, desktop runners, choosing one stack, offline jobs, hardware limits, and updates, and this one covered sharing the box. For model cards, licenses, and when a $20 closed chat is easier, switch to Open-source AI explained. For kids and closed products, read the guide to kids and shared devices. You will find more paths on Learn and in the AI products chooser.
Who can run it, and what they should not paste
- One computer login is one filing cabinet. Split logins or wipe threads before the laptop changes hands.
- Keep Ollama (and similar apps) on
127.0.0.1. Treat0.0.0.0as a switch for one planned evening at home, never a cafe default. - Confirm with two commands: localhost should answer, and a phone on the same Wi-Fi should not.
- A kitchen Mac with an open port is a toy. Work that needs sharing should buy a host with a name and a bill.
- Tape the rules card to the lid, and title chats with people, not moods.
Series notes
This is the last part of Run open models from scratch (series code OS14). Previous: updating models without breaking your setup. Related: Open-source AI explained, privacy paste test, kids on shared devices, and Learn.
Sources
Product pages and docs used for bind defaults, auth, and network serving. Re-check the week you change a setting.
- Ollama FAQ (default bind
127.0.0.1:11434,OLLAMA_HOST, exposing on a network, ngrok and Cloudflare examples, model storage paths) - Ollama: Authentication (no auth required on local
localhost:11434) - Ollama (the app the household in this story ran)
- LM Studio and LM Studio local server (developer server and the “Serve on Local Network” bind; they recommend auth off localhost)
- llama.cpp (engine under many desktop runners; its server can bind wide too)
- Groq (hosted inference for a real team seat; not xAI Grok)
- Together AI and Fireworks AI (hosted open-model APIs when the kitchen box is the wrong shape)
- Kids, family, and shared devices (closed-chat household layer)
- Privacy when you run AI yourself and Hosted versus download (location vs open weights)
- Learn (Analytics Made Simple)
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.