
Data quality only helps other people if they can see it. A short one-page scorecard next to each important table tells everyone who owns it, how healthy it is, and what to watch out for.
Say you have already profiled your data, removed duplicates, mapped categories, labeled time zones, and automated your checks. Then a new analyst joins, rebuilds a metric from the wrong table, and the executive channel learns about “your” number the hard way. The work was solid, but nobody outside your head could see the proof. Quality that only lives in your head does not survive your vacation.
This post closes the series Data quality for people who ship numbers. The earlier posts made quality something you do every week, and now you write it down just enough that others can rely on your datasets. You do not need a committee, a 40-page standard, or a tool nobody opens. Think of it as a light scorecard that lists the dataset, its owner, its quality measures, its known issues, and the next check. Company-wide governance, meaning the formal rules for who owns and approves data, still matters. We already cover that in Data Governance 101 and Master Data Management. This post is the analyst-sized version that you can ship this month. Skills from the SQL series, Python for analytics, From spreadsheets to real data, and Analytics foundations all feed the same habit, which is making the promise about your data readable.
Trust is a product feature, not a personality trait
Example.
The light scorecard (copy this)
Example.
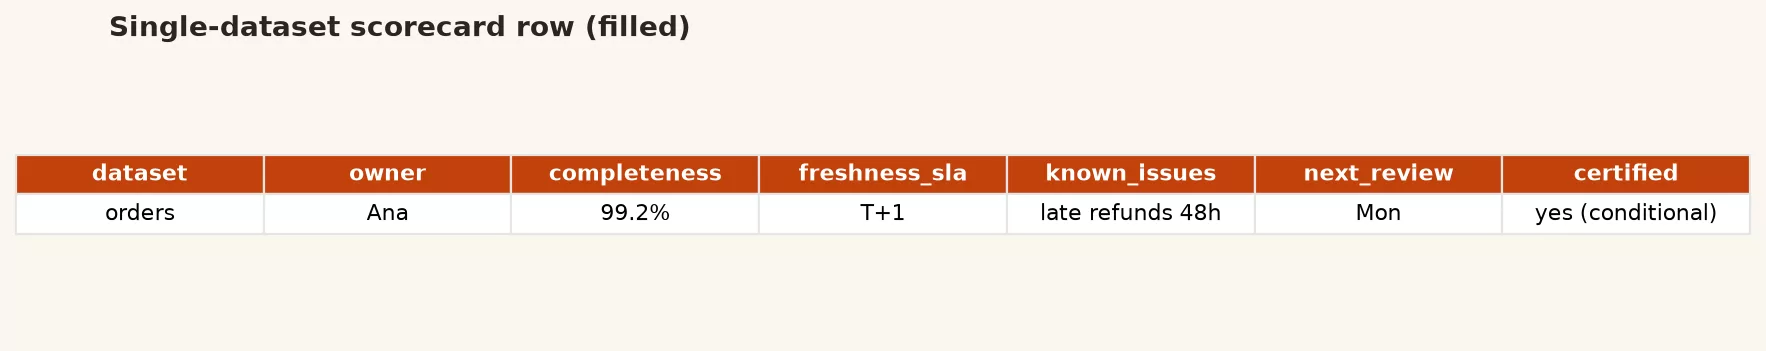
Keep one scorecard per dataset that people actually use, or per certified mart (a cleaned table that has been approved for reporting), and not per raw landing table unless raw is what people query. Pick the table people argue about in meetings. The grain field on the card means what one row of the table stands for, such as one row per order.
| Field | What to write | Example |
|---|---|---|
| Dataset name | A stable plain-English name plus the technical name | Orders daily fact (analytics.orders_fact) |
| Purpose | Decision or report it serves | Daily revenue and order counts for Sales Ops |
| Owner | Named human or rotation, plus backup | The analytics lead, with a backup analyst |
| Grain | One sentence saying what a single row stands for | One row per order |
| Primary key | Business key used in checks | order_id |
| Time contract | The time rules from the earlier post on dates and time zones | Event time UTC; local day by store zone; fiscal via date dim |
| Consumers | Dashboards, exports, models | Sales daily board; finance weekly pack extract |
| Quality metrics | 3 to 7 measures with thresholds | See metrics table below |
| Last green run | When checks last passed | 2024-06-12 06:12 UTC |
| Known issues | Honest limits and workarounds | Refunds lag up to 48h; do not use for same-day net revenue |
| Next check | When quality will be reviewed again | Daily automated suite; human review each Monday |
| Links | Pipeline, dashboard, runbook | Code folder, dashboard address, incident channel |
That is enough for most workplace trust problems. Resist the urge to invent twenty optional fields before the first five are filled in for your top tables.
Quality metrics block (the heart of the card)
Pull these measures from the automated checks described in the earlier post on validation. Show the current value, the threshold, and the status. Update them automatically if you can. If you must update by hand, do it on a schedule, because a stale green light is worse than an honest “unknown.”
| Metric | Threshold | Current | Status |
|---|---|---|---|
| Row count (yesterday) | > 0 and within 60% to 140% of 4-week same-weekday median | 12,480 | PASS |
Duplicate order_id | 0 extra rows | 0 | PASS |
Null amount rate | ≤ 0.1% | 0.02% | PASS |
Orphan customer_id | 0 | 3 | FAIL |
| Load freshness | max loaded_at_utc lag ≤ 6 hours on weekdays | 2.1 hours | PASS |
| Invalid order dates | 0 rows outside 2000 to 2100 after cast | 0 | PASS |
When a measure fails, the scorecard should not hide it. Put the failure at the top for the day and link the check log. Then state the impact on users in one sentence: “Do not use customer segment joins until orphans are cleared.”
Where to publish so people actually see it
Documentation dies in forgotten wikis. Place the scorecard where people already look when they use the data:
- Business intelligence (BI) tool description, or certified badge text, on the main dashboard.
- Warehouse table comment, or a companion view named
…_dqthat returns the latest status row. - readme file in the code folder that builds the mart, with the card written out.
- Channel topic or pinned post for the team that gets alerted on a failure.
- A small companion file that travels with CSV and spreadsheet handoffs (the metadata habit from the Python series).
Pick two places, not seven, because consistency beats coverage. If your company later adopts a data catalog, these scorecards become its starting content instead of empty templates.
Known issues: the most underrated trust builder
Hidden caveats destroy credibility, while written caveats build it. A known issue should include:
- What is wrong or limited.
- Who is affected.
- Since when.
- Workaround.
- Expected fix or “accepted risk” owner.
These examples read as mature, not weak:
- “Same-day net revenue is incomplete because refunds post up to 48 hours later. Use T+2 for finance-facing nets.”.
- “Store 118 moved to a new point-of-sale (POS) system on 2024-05-01. Pre-migration order IDs can collide with the legacy system, so filter on
source_system.”. - “Category ‘Other’ is still 7% after the category mapping work. Do not use for assortment strategy until it is under 3%.”.
This is the same honesty as the good-enough data idea in the foundations series, where confidence language beats fake certainty.
Worked example: Orders daily fact scorecard
Here is a filled card you can adapt. It assumes you already have the time rules and automated checks from the earlier posts in this series.
# Data quality scorecard (light)
# Dataset: Orders daily fact
# Technical: analytics.orders_fact
# Version: 2024-06-12

purpose: >
  Certified order-level fact for Sales Ops daily board and the finance
  weekly extract. Not for real-time inventory.

owner:
  primary: analytics lead
  backup: backup analyst
  channel: #data-sales-ops

grain: one row per order
primary_key: order_id

time_contract:
  event_timestamp: ordered_at_utc (UTC instant)
  business_day: local_business_date (store IANA zone)
  fiscal: join analytics.date_dim on local_business_date
  partial_day_policy: mark current local day as in_progress

consumers:
  - Sales daily dashboard (certified)
  - finance_weekly_orders.csv export job
  - churn features notebook (read-only, secondary)

quality_metrics:
  - name: rows_yesterday
    threshold: ">0 and within 60%-140% of 4-week same-weekday median"
  - name: unique_order_id
    threshold: "0 duplicate keys"
  - name: null_amount_rate
    threshold: "<= 0.1%"
  - name: orphan_customer_id
    threshold: "0"
  - name: load_lag_hours
    threshold: "<= 6 on weekdays, <= 12 weekends"
  - name: invalid_dates
    threshold: "0 after cast; year in 2000-2100"

known_issues:
  - id: KI-17
    summary: Refunds lag up to 48h
    impact: Same-day net revenue understates true net
    workaround: Use T+2 net for finance; gross OK same-day
    status: accepted_risk
    review_by: 2024-07-01
  - id: KI-21
    summary: 3 orphan customer_ids since 2024-06-11
    impact: Segment joins drop those orders
    workaround: Exclude or map to 'Unknown customer' bucket
    status: open
    owner: analytics lead

next_check:
  automated: every day 06:00 UTC (Part 6 suite)
  human_review: each Monday 10:00 local, 15 minutes
  escalate_if: any FAIL open more than 1 business day

links:
  checks_repo: analytics-dq/orders_fact_checks.py
  bi: https://bi.example.com/dashboards/sales-daily
  runbook: docs/runbooks/orders_fact.md
  last_green: 2024-06-12T06:12:00Z
Example output:
You can store the same content as Markdown, a config file, a warehouse table, or a wiki page. The format matters less than the fields and the honesty.
Optional: a one-query status face for SQL users
-- Latest scorecard face for BI description or a status tile
SELECT
  dataset_name,
  owner_primary,
  grain,
  overall_status,
  failing_checks,
  known_issues_open,
  last_green_at_utc,
  next_human_review_at
FROM analytics.dq_scorecard_current
WHERE dataset_name = 'orders_fact';

-- overall_status example logic (materialize in your job)
-- FAIL if any gate check failed in the last run
-- WARN if only soft-band checks failed
-- PASS otherwise
Pair this with a tiny Python script that updates dq_scorecard_current after your automated checks run. The scorecard then stays alive instead of turning into a slide that goes stale after the offsite.
from datetime import datetime, timezone

def summarize_suite(results):
    """results: list of objects with .name, .ok, .detail from Part 6."""
    failed = [r for r in results if not r.ok]
    if not failed:
        status = "PASS"
    elif any(r.name.startswith("row_count") or "unique" in r.name for r in failed):
        status = "FAIL"
    else:
        status = "WARN"
    return {
        "dataset_name": "orders_fact",
        "overall_status": status,
        "failing_checks": ", ".join(r.name for r in failed) or None,
        "checked_at_utc": datetime.now(timezone.utc).isoformat(),
        "owner_primary": "analytics lead",
    }

# pseudo: write_to_warehouse("analytics.dq_scorecard_current", summarize_suite(results))
Writing for three audiences at once
A scorecard fails if only engineers can read it, so aim for three readers:
- The rushed stakeholder: purpose, status, known issues, and a line saying what it is safe to use for and what it is not.
- The analyst on call: grain, keys, check names, runbook links, owner.
- Future you: why thresholds exist, when exceptions were accepted, what changed last quarter.
Lead with plain English and keep technical names in parentheses. Avoid unexplained acronyms, and if you must say service level agreement (SLA), define it once as the promised freshness or quality bar. If you find yourself building a responsibility chart (RACI, short for responsible, accountable, consulted, and informed), you may already be climbing into program governance. That is fine, but do not force that vocabulary onto a single card.
Certification without theater
Some teams stamp dashboards “certified.” The stamp only helps when it means a published scorecard plus passing checks. An empty certification is worse than no badge, because it teaches leaders to stop asking questions.
A minimal certification contract:
- Named owner and backup.
- Grain and primary key written.
- Automated suite scheduled with logged results.
- Known issues section reviewed in the last 30 days.
- A list of users, so you know who to notify when a check fails.
If any bullet is missing, call the asset “in progress” or “team use,” not certified. Honesty scales to a bigger team, and show-and-tell does not.
How much process is enough?
Use a simple ladder of four stages, and climb only when the pain demands it.
| Stage | What you have | When to stay here | When to level up |
|---|---|---|---|
| Personal notes | README + three checks | One consumer, one owner | Someone else ships from your table |
| Light scorecard | This post’s template + log | Team of analysts, a few certified dashboards | Multiple domains, auditors, or frequent handoffs |
| Shared catalog entries | Scorecards imported to a catalog | Company-wide discovery pain | Regulated data, formal stewardship roles |
| Governance program | Policies, councils, MDM, RACI | Enterprise risk and cross-domain conflict | You need operating model change, not more wiki pages |
Most readers of this series should live happily at the light scorecard stage for a long time. That is not a lesser path, because it is how quality shows up in the work week. When leadership asks for “governance,” you can point to scorecards and check logs as evidence that you already practice stewardship. From there you can grow into program design with the governance articles instead of starting from slogans.
Common mistakes
| Mistake | What happens | Better move |
|---|---|---|
| Documenting only columns, never grain | People still double count | Lead with one-row meaning |
| Owner is “the data team” | Nobody acts on FAIL | A named person plus a backup |
| No known issues section | Users rediscover limits in meetings | Write the awkward truths |
| Scorecard updated yearly | False trust | Tie updates to check runs |
| Green badge without thresholds | Theater | Show metric, threshold, value |
| Catalog everything first | Burnout, empty fields | Top five datasets only |
| Hiding failures to protect image | Bigger damage later | Fail public, fix fast, note impact |
Rule of thumb: If a competent stranger cannot decide whether to use your table for a board slide after two minutes on the scorecard, the card is not done.
How to practice this week (and close the series)
- List the five datasets that cause the most arguments in your team chat, and rank them by how much damage a wrong number would do, not by how elegant they are.
- Fill one light scorecard completely, including at least one known issue. If you have zero issues, you are probably not looking.
- Connect the card to your automated checks by pasting in the last run statuses and timestamps.
- Publish the card in two places, such as the dashboard description and the readme file.
- Walk one stakeholder through the card in ten minutes, ask what was still ambiguous, and fix those lines.
- Schedule the Monday human review for 15 minutes, and put it on a calendar like a real meeting.
When those habits stick, you have finished the hands-on quality path: define bad data, profile, dedupe, standardize, fix time, validate, and document trust. For deeper program design, policies, and cross-domain ownership, continue with Data Governance 101 and Master Data Management. For more skill tracks, use the Learn hub.
Series recap: Data quality for people who ship numbers
| Part | Focus | You can now… |
|---|---|---|
| 1 | What “bad data” means | Name dimensions with workplace examples |
| 2 | Profile before you polish | Measure nulls, ranges, and weird categories first |
| 3 | Deduping without destroying history | Respect keys and soft deletes |
| 4 | Standardizing categories and names | Use mapping tables; avoid “Other” hell |
| 5 | Dates, time zones, fiscal calendars | Store UTC, display local, separate fiscal clocks |
| 6 | Validation you can automate | Gate loads with counts, keys, freshness, sanity |
| 7 | Documenting quality | Publish a light scorecard others trust |
None of this requires waiting for a perfect platform. It requires repeating small, grown-up habits until the room stops treating data quality as a surprise.
A 30-day rollout plan (one team)
If you want a concrete path from “we should document more” to “we trust our top tables,” try this month-long shape:
- Week 1: Pick five datasets and write only the grain, owner, and purpose for each. Share them in the team channel for corrections.
- Week 2: Attach automated checks to the top two datasets and create the check log table. Then make a check fail once on purpose in a test copy.
- Week 3: Fill in the measures and known issues, and publish the scorecards in dashboard descriptions and readme files. Walk one stakeholder through each card.
- Week 4: Add the Monday human review and retire one noisy check. Promote one more dataset from notes to a full card, and stop there unless pain demands more.
That plan is deliberately small, because quality programs die when month one tries to boil the ocean. Analysts win when month one makes two dashboards safer and one on-call shift less scary.
Quick recap
- Trust needs a readable contract: purpose, owner, grain, metrics, issues, next check.
- Publish scorecards on the path of use, not only in a distant wiki.
- Known issues that are written down increase confidence, while hidden limits destroy it.
- Automate the status from your checks, so that green means something measurable.
- Stay light until pain demands catalogs and formal governance programs.
You made it through the series, so ship one scorecard this week. After that, go back to the numbers with fewer late-afternoon mysteries.
Sources
Research and further reading used for this article:
- Wang, R. Y., and Strong, D. M. (1996), Beyond Accuracy: What Data Quality Means to Data Consumers: http://mitiq.mit.edu/Documents/Publications/TDQMpub/14_Beyond_Accuracy.pdf
- DAMA International: https://www.dama.org/
- DAMA NL, Dimensions of Data Quality: https://dama-nl.org/dimensions-of-data-quality-en/
- DATAVERSITY, Data quality dimensions: https://www.dataversity.net/articles/data-quality-dimensions/
- Collibra, The 6 data quality dimensions: https://www.collibra.com/blog/the-6-dimensions-of-data-quality
- IBM, Data quality dimensions: https://www.ibm.com/docs/en/ws-and-kc?topic=quality-data-dimensions
- Analytics Made Simple, Data Governance 101: https://analyticsmadesimple.com/key-terms/data-governance/
- Analytics Made Simple, Master Data Management: https://analyticsmadesimple.com/key-terms/master-data-management/
- Analytics Made Simple, Learn hub: https://analyticsmadesimple.com/learn/
- Analytics Made Simple, Analytics foundations: https://analyticsmadesimple.com/series/analytics-foundations/
- Analytics Made Simple, From spreadsheets to real data: https://analyticsmadesimple.com/series/spreadsheets-to-data/
- Analytics Made Simple, SQL series: https://analyticsmadesimple.com/series/sql/
- Analytics Made Simple, Python for analytics: https://analyticsmadesimple.com/series/python/
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.



