A model card is the product label for an AI model file. Read it like a spec sheet before you download anything. Check who published it, what the license allows, whether it is a chat model or a base model, and whether the file size fits your computer’s memory. Skip the giant scoreboard on the first pass.
Pavel’s laptop had 16 GB of RAM and 48 GB free when he opened a 70B model card on Hugging Face. The first badge was a bright Text Generation pill beside an official-looking org name. He treated that as a go. The Files tab listed a GGUF labeled Q4_K_M at 42.5 GB. He clicked it. Cafe Wi-Fi needed 53 minutes. macOS then warned that 2.1 GB remained. LM Studio refused to load the weights. The 70B file sat on disk, and 16 GB of memory was never going to hold it.
This page teaches a 90-second scan you can run on any live Llama or Qwen card. Names on the Hub move. The scan does not.
Five fields, then stop
Treat the Hugging Face model card as a shopping sheet. On the first pass, check only the publisher, the license chip, chat versus base in the name, the file size against your RAM, and one sentence of intended use or limits. Popularity counts and the big evaluation table can wait until those five answers exist.
The card is a spec sheet
On the Hub, the model card is the repo’s README.md. Hugging Face’s docs split it in two. A YAML metadata block at the top feeds the pills in the header: license, tags, pipeline_tag, datasets, base_model, library. Markdown under that is the human text: what it is, who built it, how to use it, what it gets wrong. Both layers overlap. You can read the pills in 20 seconds and still miss the file that wrecks a 16 GB machine.
The Hub template still tracks the 2018 model-card paper (Mitchell and coauthors): Model Details, Uses, Bias / Risks / Limitations, Training, Evaluation, Technical Specs. You are not writing that paper. You are shopping. Who made it, what job it was built for, what it will not do, and whether it physically fits. Popularity counts and a wall of benchmark rows can wait until those four answers exist.
Pavel never got to intended use. He never opened Limitations. He saw a pretty first badge and a 70B in the title. That is how a spec sheet turns into a 42.5 GB souvenir.
Read the header, ignore the sparkle
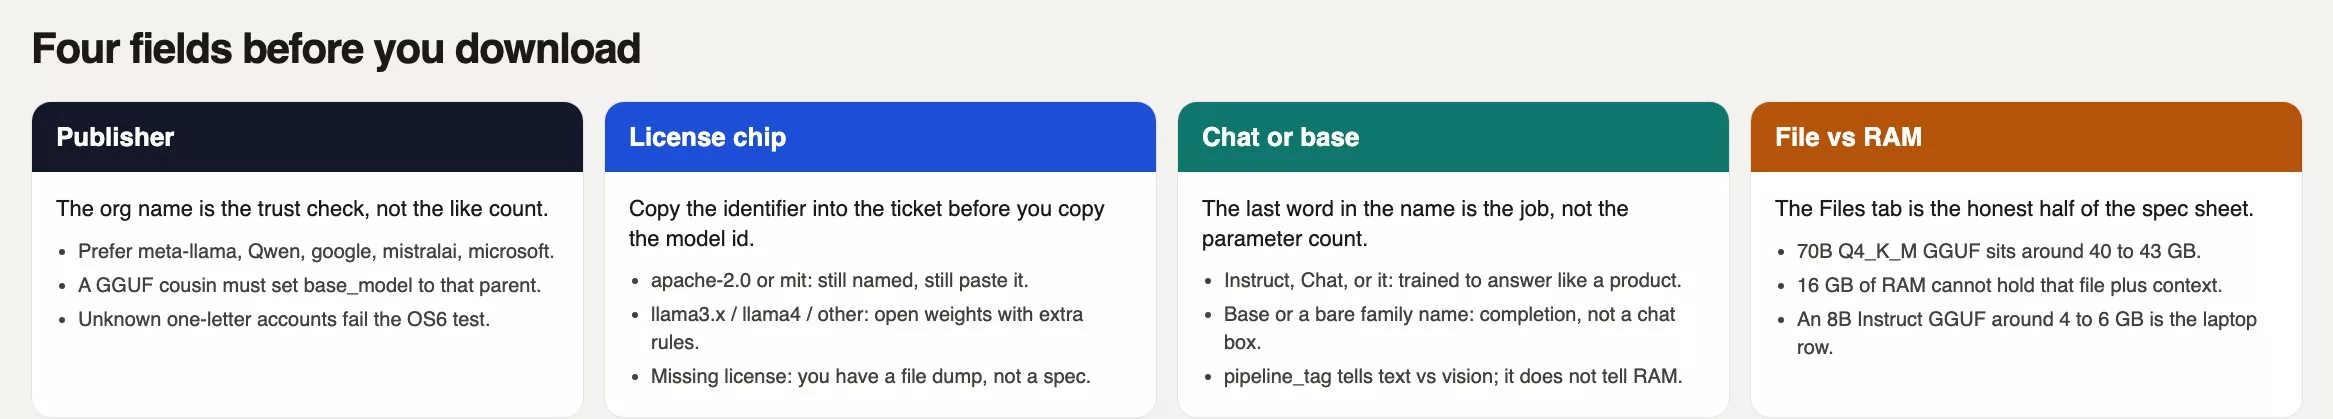
Who published it
The org name is the first trust check. meta-llama, Qwen, google, mistralai, microsoft: those are the families the rest of the Hub clones. A stranger account can still ship a useful GGUF when base_model points at one of those parents. the random-download safety guide already said do not download random weights. One-letter account, brand-new org, no license, no parent: close the tab.
Official Llama repos are often gated. You click Agree, terms appear, Files unlock. Easy to sleepwalk through. Read the org, then read what you agreed to. Follower counts are popularity. They are not RAM.
The license chip
The license identifier is the chip in the header. As of writing (August 2026) many Qwen-class cards still show apache-2.0 or mit. Meta’s 70B-class Instruct repos show a Llama Community identifier such as llama3.3 (or a later llama4-style chip if that line is the flagship this week). Apache-style terms are ordinary software use. Llama’s community licenses add acceptable use, attribution, and a monthly active user threshold that can force a separate grant. the open-weight vs open-source guide is the law class. This page is the chip. If the chip is missing, you have a file dump.
Rule of thumb: The first badge is chrome. The org name and the license chip are the spec. If those two disagree with the story in your head, believe the chip.
Chat, base, and the cousin repo
Look at the last word in the model name before you look at the parameter count. Instruct, Chat, or it usually means the weights were trained to answer like a product: system prompt, user, assistant. A Base (sometimes a plain family name with no suffix) is a completion model. It continues text. It will not reliably take “summarize this PDF” the way ChatGPT does. Desktop apps can wrap a base model in a chat template and hide that. You still paid for the wrong animal.
pipeline_tag is the Hub’s task label, usually text-generation for chat weights. It picks the widget. It does not tell you the file will fit. If you wanted a text summarizer and the tag is a vision stack, you opened the wrong repo.
Then there is the cousin. Official repos ship safetensors shards for Python. The GGUF you drop into LM Studio or llama.cpp often lives in another repo whose card sets base_model to the official id and base_model_relation: quantized. That parent link is the spec. A GGUF with no parent and a flashy 70B in the title is an the random-download safety guide incident. If the card has new_version, read that repo instead.
Context length and the Files tab
Context length is how much text the model can keep in one go, measured in tokens (a chunk of a word, not a page). Llama 3.3 70B Instruct’s public card, as of writing, talks about a 128,000 token window. Some Qwen 72B-class cards advertise the same order of magnitude, with a note that default config.json can be shorter. Re-read the card the week you pick. A 128k window is a lot of pages and a RAM multiplier on a 70B file.
The Files tab is the honest half of the spec. Official 70B-class Instruct repos list multi-gigabyte safetensors shards. Add them up before you assume “one file.” GGUF repos list named quants. You need the byte size next to the name, not the GGUF viewer, on pass one.
Ballpark, as of recent public GGUF cards for Llama 3.1 / 3.3 70B Instruct (confirm the row you click): Q4_K_M around 42.5 GB, Q4_K_S around 40 GB, Q5_K_M around 50 GB, Q8_0 around 75 GB. A Q2 can dip near 26 GB with ugly quality loss. the size-and-RAM guide is the RAM class: loaded weights want memory near the file size, plus context overhead. A 42.5 GB Q4 on 16 GB of RAM is a no. An 8B Instruct GGUF around 4 to 6 GB is the laptop animal Pavel had. Need 70B-class quality on 16 GB? Use a host (the hosted-API guide) or pick a smaller Instruct file. Disk is not RAM.
Intended use, limitations, skip the eval widget
Scroll past the hero badges to Uses. Hugging Face’s annotated template splits Direct Use, Downstream Use, and Out-of-Scope Use. Direct Use is what this does without you retraining it. Out-of-Scope is the do-not list: medical advice, law, scraping private data, that family of harm. Bias, Risks, and Limitations is the other required stop. Labs are uneven here. Some write a real paragraph. Some paste a disclaimer. Read whatever exists. If the card says research only, or “not evaluated for X,” that is the spec talking. Your Slack thread does not override it.
Then you will hit Evaluation. The Hub can render model-index (or newer eval-results metadata) as a widget of ARC, MMLU, HumanEval, whatever the author wired in. On first read, skip it. the quality-without-benchmarks guide already covered why a leaderboard row is a poor shopping list. Use it later, when two 8B Instruct files both fit. Training Details, CO2, BibTeX, and Glossary can wait. If you stay in LM Studio or Ollama, the GGUF cousin’s quant table is the start guide that matches the file you will click.
Worked example: a 70B Instruct card
Walk this as of writing (August 2026). Open the official meta-llama/Llama-3.3-70B-Instruct card, or the current Meta 70B-class Instruct repo if the Hub now leads with a Llama 4 line. Run the same walk on a Qwen 72B-class Instruct card. Names move. Fields do not.
Header: publisher meta-llama. License chip is a Llama Community identifier, not Apache 2.0. Task pill is Text Generation. The name ends in Instruct, so this is the chat sibling, not the base. Gated: you accept Meta’s terms before Files. Context copy is a 128k-class window; confirm on the page you opened. None of that tells you the file fits 16 GB of RAM.
Files: official shards are the Python path. For a desktop runner, open a GGUF repo that lists this id as base_model. Find Q4_K_M. On recent public tables that row is about 42.5 GB. Pavel’s 16 GB RAM fails here. Stop. Want this class of model anyway? the hosted-API guide and a host. Want local? An 8B Instruct GGUF, then skim Uses and Limitations. Skip the eval widget until a file that fits is on the table.
| Field | Why you care | Skip for now |
|---|---|---|
| Publisher org | Who you trust; whether the random-download safety guide lets you download | Follower count, weekly downloads, likes |
| License chip | Apache-style vs Llama community vs missing | The full PDF after you have the identifier |
| Name suffix (Instruct vs Base) | Chat product vs autocomplete | Architecture diagrams and paper abstracts |
pipeline_tag | Text chat vs vision vs something else | Hobby tags that only help search |
| Files / GGUF GB | Whether 16 GB of RAM can hold it | Every exotic quant in the list |
| Context length | Will a long PDF even fit the window | YaRN recipes and rope flags |
| Intended use + limitations | What the authors say you should not do | The eval widget, CO2, BibTeX |
base_model | Is this GGUF a child of the official repo | Merge family trees |
Use this as a 90-second scan while the page is open. Time it. If you are still reading MMLU rows, you left the spec sheet and entered theater.
# 90-second model card scan. Do this before any download.
# Target: finish before the cafe Wi-Fi password screen times out.
# 1. Publisher (15s)
#    org in {meta-llama, Qwen, google, mistralai, microsoft, ...}
#    else: require base_model -> one of those, or stop (the random-download safety guide).
# 2. License chip (15s)
#    apache-2.0 / mit : still paste the id into the ticket.
#    llama3.x / llama4 / other : open weights, extra rules, read later.
#    missing : close the tab.
# 3. Name + pipeline_tag (15s)
#    Instruct / Chat / it : chat-shaped.
#    Base / no suffix : completion model, not your ChatGPT stand-in.
#    pipeline_tag text-generation (or the vision tag if you wanted vision).
# 4. Files tab (30s)
#    GGUF Q4_K_M (or the app’s default) : read the GB.
#    70B Q4 is ~40 to 43 GB. 16 GB RAM cannot load it.
#    8B Q4 is ~4 to 6 GB. That is the laptop row.
#    No parent base_model on a GGUF? stop.
# 5. Uses + Limitations (15s)
#    One pass. If it says research-only or not-for-X, believe it.
#    Skip the eval widget. Skip CO2. Skip BibTeX.
#    If new_version points elsewhere, scan that card instead.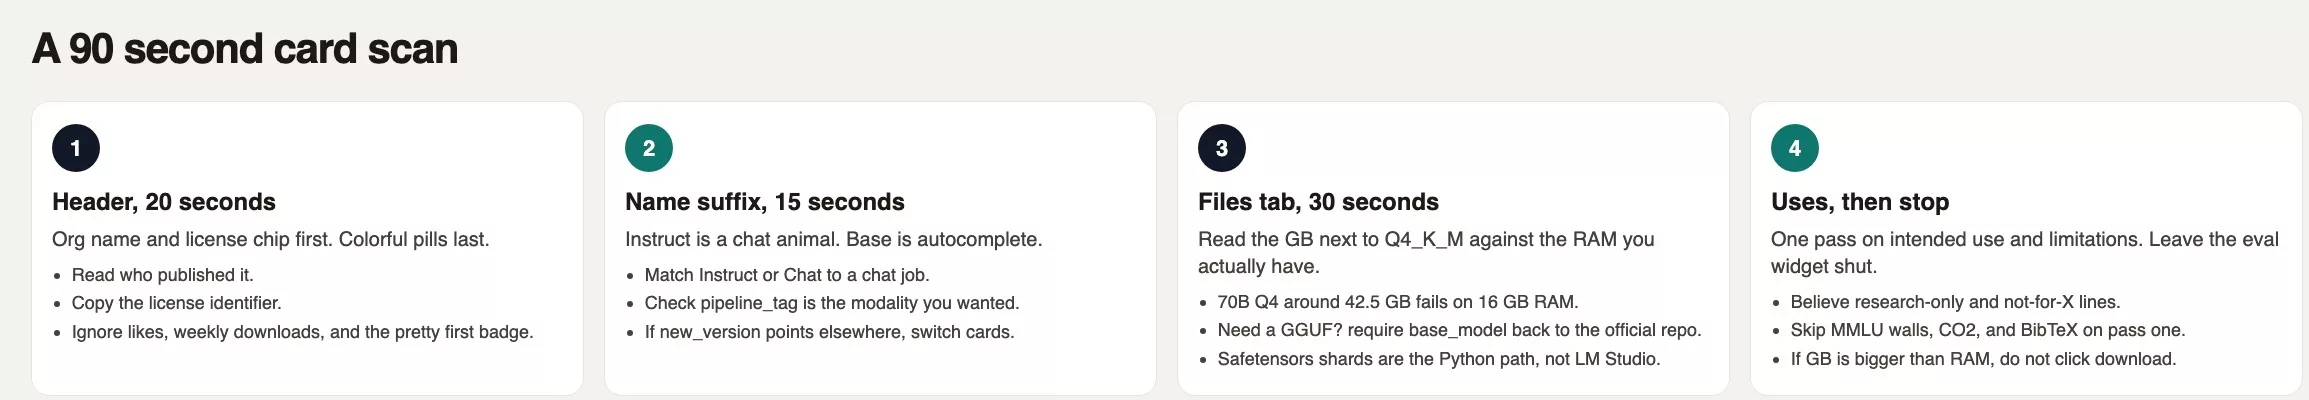
What that checklist is for: Pavel had the pretty badge at second 3 and the download at second 10. The scan puts 75 seconds of boring fields in front of the click. The 42.5 GB row is the one that would have saved the disk.
The card is not the README vibe
- Trusting the first colorful pill (Text Generation, a llama mark, a download count) instead of org + license + GB.
- Downloading the official
safetensorsshards when the app you use wants a GGUF, or the reverse. - Grabbing a Base model because the parameter count matched a blog, then wondering why chat feels broken.
- Accepting a gated Llama license with the same reflex as a cookie banner, then telling legal “it’s open.”
- Reading the eval widget first, picking the highest MMLU, and finding out the file is 42.5 GB after the progress bar starts.
- Ignoring
new_versionandbase_model, so you pull an old quant of a repo the author already replaced.
Scan one card for license, size, publisher
Open two live cards this week. One official Instruct repo (Llama 70B-class or Qwen 72B-class, whichever the Hub is pushing as of writing). One GGUF cousin that sets base_model to that id. Run the 90-second scan on both. Write five lines on a sticky: org, license id, Instruct or Base, the Q4 GB, one sentence from Limitations. Then write your RAM in the corner. If the GB is larger than the RAM, you do not click. That is the drill.
If you need 70B-class quality, do not collect the file as a trophy. the hosted-API guide is the hosted door: Groq, Together, and Fireworks. If a closed $20 chat is enough, the closed-chat guide already said so. Local practice continues in Run open models from scratch with an 8B that fits.
A model card you can actually use
- Treat the Hugging Face card as a spec sheet: YAML pills plus the README text.
- Read org, license chip, Instruct vs Base, and
pipeline_tagbefore any Files click. - On Files, read the GGUF GB against your RAM. A 70B Q4 around 40 to 43 GB does not load in 16 GB.
- Skim Uses and Limitations. Skip the eval widget on pass one.
- If the file cannot fit, pick a smaller Instruct GGUF or wait for the hosted APIs in the hosted-API guide. Do not fill the disk for a badge.
Series notes
This is Part 9 of Open-source AI explained (series code OS7c). Related: open-weight vs open-source vs free, hosted chat APIs, Run open models from scratch, privacy paste test, and Learn.
Sources
Docs and cards checked for this article. Labels move; re-open the week you download.
- Hugging Face: Model cards (metadata vs text, license,
base_model,pipeline_tag, eval widgets) - Hugging Face: Annotated model card template (Uses, limitations, evaluation sections)
- Hugging Face: Model card guidebook
- Hugging Face: GGUF on the Hub (quant names, viewer, llama.cpp / LM Studio / Ollama)
- meta-llama/Llama-3.3-70B-Instruct (worked official card as of writing; confirm the current flagship)
- Meta: Llama downloads and license (community license / acceptable use, not Apache)
- Mitchell et al., 2018: Model Cards for Model Reporting (the paper the Hub template still cites)
- llama.cpp, LM Studio, and Ollama (the runners that load a GGUF)
- OS3: Model size, quantization, and will my laptop run it? and OS6: Safety and random downloads
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.