Marcus opened the QBR folder at 11:22 on Tuesday. The intern, Jordan, had dropped a six-page KPI dictionary into Drive, filename qbr_kpi_defs_CHAT. Page 1 was a pretty table: Net Retention 118%, Active Accounts 4,260, Time to First Value 2.1 days. Finance’s Slack from 4:17 the day before used 97%, 2,941, and 11 days. The QBR was Thursday. Two days. Eleven slides in the deck already quoted 118%. Jordan had asked ChatGPT at 9:04am to “write the KPI definitions” and pasted the reply. The model never saw Finance’s closed-book memo.
This is Part 30 of Phase P, and Part 5 of AI safety for everyday life. It is the last part of this series, and the last of Phase P. Kids, family, and shared devices was the household layer. This part is the work layer: what still belongs to you when a model can draft the memo. The earlier series on Prompting for everyone and AI agents for everyone taught the typing and the watch-approve-walk-away ladder. This one is the job underneath those tools. The map for what to study next sits on Learn.
What you’ll learn
- Treat AI as a task shifter in this lane, not as a clean “jobs taken” headline you can plan Monday from
- Name five skills that still belong to you: the question, the number check, the conversation, taste, and the stop
- Read a three-column table of what ChatGPT, Claude, Gemini, or Grok can draft versus what you still own
- Replay Marcus’s three KPI mismatches (118% vs 97%, 4,260 vs 2,941, 2.1 days vs 11) before they reach a QBR
- Run a 45-minute weekly practice on one live artifact, then write stop, edit, or ship
Tasks move first, titles lag
Jordan still has the intern title. The task that used to take a week of interviews (write down what “active” means) took 11 minutes in a chat. That is the change in this article’s lane. The org chart did not vanish on Tuesday. The definition work moved into a paste, and nobody owned the paste.
The International Labour Organization has been boring on this in a useful way. In 2023 they scored tasks inside occupations, then they refined that index in 2025. Few jobs are a pile of tasks you can fully hand to current generative AI. Nearly every occupation still has work that needs a person. Transformation of jobs is the likely path. Those scores are potential exposure if the tools were fully adopted, not a census of roles already gone. Cost, skills, and messy operations sit in between the score and the headcount.
The OECD’s 2023 Employment Outlook put the same caution in a chapter title: no signs of slowing labour demand yet. Their read of the evidence at the time was little sign of large negative employment effects from AI. Workplace case studies in manufacturing and finance made the same cut: reorganisation of tasks showed up more often than people being walked out. Your role can still change. Do not write your week from a displacement percentage you saw on a thumbnail. You cannot take that thumbnail to Gita in FP&A. You can take a definition, a source, and a conversation.
Rule of thumb: If Finance did not sign the definition, the model’s definition is a draft. It does not go in the deck.
Five skills that still matter
The NIST AI Risk Management Framework (voluntary, 2023, with a generative-AI profile in 2024) spends a lot of ink on human oversight: who is responsible when a person and a model share a workflow. OpenAI’s own API safety note says the same thing in one line you can tape above a monitor. Wherever possible, have a person review outputs before they are used in practice. Give that person the original notes, the source table, the memo. A chat window does not count as that review.
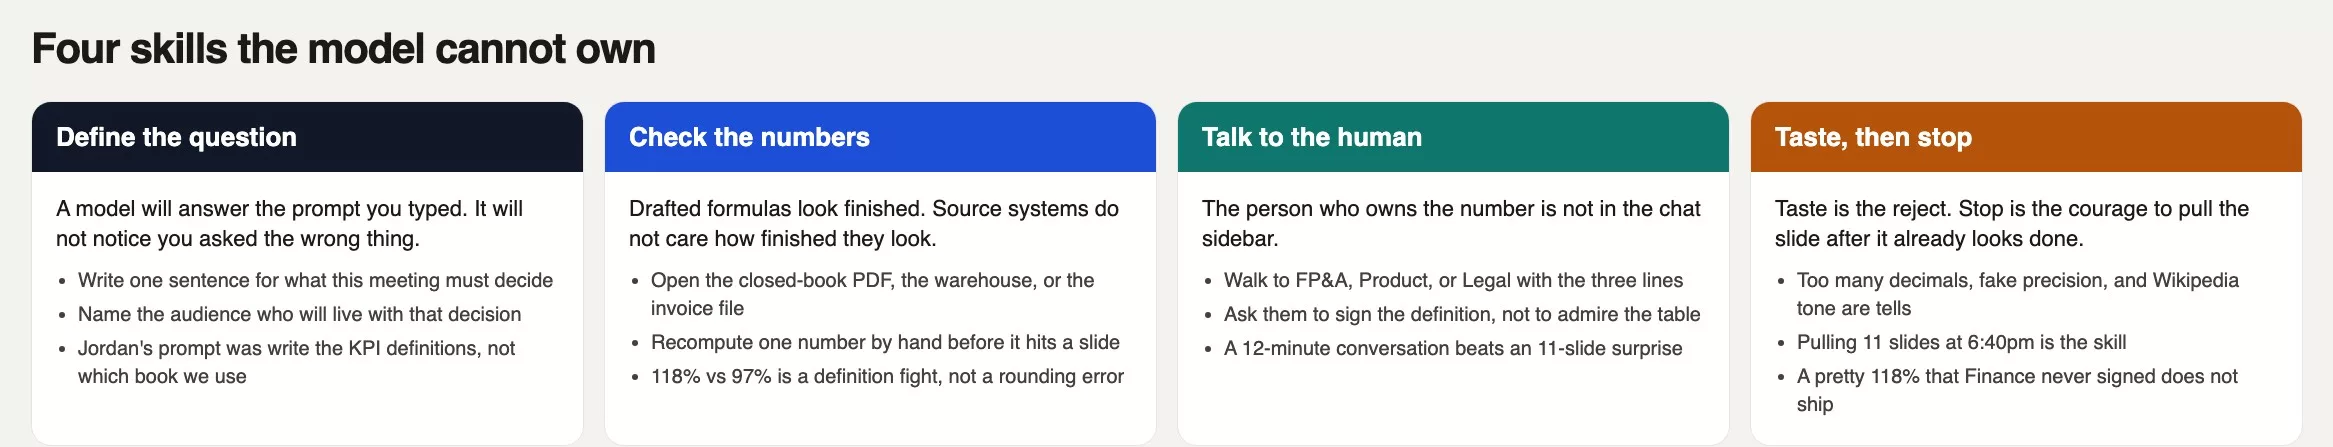
On an analytics team that oversight is five habits you can name in a standup.
Define the question
Jordan asked ChatGPT to write the KPI definitions. That is a production request with no question inside it. The QBR had a real one: which closed book this company is using this quarter for Net Retention, Active Accounts, and Time to First Value, and who already signed it. A model will answer the prompt. It will not walk down the hall and notice you asked the wrong thing.
Write the question in one sentence before you open the chat. “Which Net Retention does Gita want on slide 4, logo or ARR, services in or out.” If you cannot finish that sentence, you are not ready to prompt. The prompting series is the drill for turning a sticky note into a work request. This skill is the step before that drill: pick the decision the meeting is actually making.
Check the numbers
The intern’s table looked arithmetically tidy. Three metrics, two decimal places, a footnote that said “trailing twelve months.” None of that is a check. A check is opening finance_metric_pack_q2.pdf, the three-page closed book Gita sent last quarter, and recomputing one number against the warehouse. 118% and 97% are a definition fight. One includes professional services and uses ARR. One is logo count and strips one-time services. The model cannot see that fight unless you put both memos in the prompt on purpose, and even then it will happily average them.
Pick one number. Find the source. Do the arithmetic once with a pencil or a SQL window. Do not ask the same model “does 118 look right.” That question is how 118 survives until Thursday.
Talk to the human who has to live with it
Gita has to sit in the QBR and defend Net Retention if a board member pokes it. Product has to defend Time to First Value if a customer success lead says onboarding is “two days now.” Those people are not in the ChatGPT sidebar. Twelve minutes at Gita’s desk, or a six-line Slack that asks her to sign three definitions, beats an 11-slide surprise.
This is also where agents fool people. A coding agent or a work-mode agent can file a pull request, fill a sheet, or draft 11 slides while you get coffee. The watch, approve, walk away ladder still ends on a person. If nobody talks to the owner of the number, you delegated the embarrassment.
Taste, and the courage to stop
Taste here means spotting that Time to First Value came back as 2.100 days, that the prose sounds like a glossary page, and that “active” was defined three different ways in one table. Fake precision is a tell. Wikipedia tone is a tell. A metric that nobody in the building has ever said out loud is a tell.
Stop is the ugly twin. The deck already had 11 slides using 118%. Pulling them at 6:40pm on Tuesday feels late. Shipping them on Thursday is later. The prompting series closer is about closing the chat and doing the task yourself. Same muscle, different artifact: close the folder. Do not paste.
What the model can draft vs what you still own
Use this as a wall chart. The left column is the skill. The middle is fair work for ChatGPT, Claude, Gemini, or Grok. The right column stays yours even if the draft looks done.
| Skill | What the model can draft | What you still own |
|---|---|---|
| Define the question | A rewrite of your prompt, a list of possible questions, three ways to frame the QBR | Which question this meeting is answering, and who the answer is for |
| Check the numbers | A formula, a sample table, a “spot the inconsistency” pass on text you pasted | The source system, the closed-book definition, the arithmetic you would defend |
| Talk to the human | A six-line Slack, a meeting agenda, a summary of last quarter’s thread | The actual conversation with Gita, Product, Legal, or the intern |
| Taste | Three shorter versions, a less glossary-like tone, a cut of the extra decimals | Whether this artifact should exist, for this audience, in this week |
| Stop | A list of risks if you ask it to list risks | The decision to pull the 11 slides, or to leave the chat unpasted |
Drafting is cheap. Ownership is a person with a calendar and a name. If your weekly AI habit is only the middle column, you will get faster at producing files like qbr_kpi_defs_CHAT.
Worked example: three KPIs, two days out
Here is the mismatch as a closed case, labeled as this team’s toy numbers, not as industry research.
| Metric | ChatGPT paste (Jordan) | Closed book (Gita / Product) |
|---|---|---|
| Net Retention | 118%, ARR, services included, trailing twelve months | 97%, logo count, one-time services stripped |
| Active Accounts | 4,260, any login in 90 days | 2,941, paid seat with a billable event in the last 30 days |
| Time to First Value | 2.1 days, first login after invite | 11 days, first successful export |
Jordan’s chat title was still in the sidebar: “kpi defs please be thorough.” Thorough is how you get six pages. The model put the product name in three sentences, invented a “North Star” paragraph, and formatted a table that would have looked fine in a vendor blog. It did not open the warehouse. It did not read finance_metric_pack_q2.pdf. It did not know Product counts first value as an export, because nobody types that unless they already know it.
Marcus caught it because he opened Finance’s Slack before he opened the intern’s file. The 4:17 message was 14 lines. Ugly. Correct. He walked to Gita at 11:40. Eighteen minutes. They pulled the 11 slides at 6:40pm. Thursday still happened. The deck used 97%, 2,941, and 11 days. Jordan’s chat is still sitting in history. That chat is now the practice artifact, not a career prophecy.
If you are the intern: send the draft to the owner as a draft. Do not drop it in the QBR folder with a filename that pretends it is the book. If you are Marcus: the 11:22 open is late. Put the closed-book PDF in the QBR folder on Friday, with the three definitions at the top, before anyone prompts.
A 45-minute weekly practice
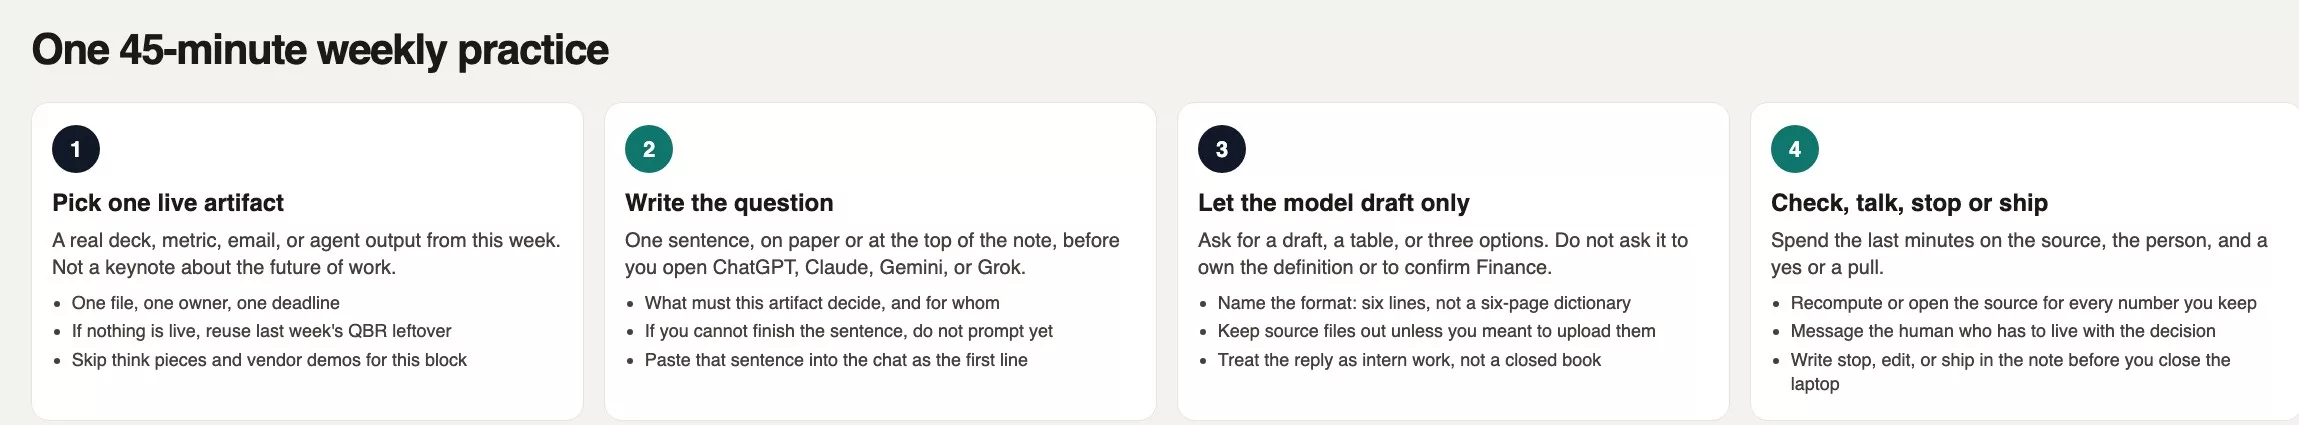
Do not spend the 45 minutes on a talk about skills of the future. Pick one live file: a deck, a metric, an email, or an agent output. If your week is quiet, reuse last week’s leftover, the way Marcus reused Jordan’s chat on the following Monday.
First five minutes: write the question in one sentence, and name who has to live with the answer. If the sentence will not finish, go find the person and come back. Next fifteen: open one model you already use (ChatGPT, Claude, Gemini, or Grok), paste the question first, and ask for a tight draft (six lines, a three-row table, three options). Do not ask it to confirm Finance. Do not ask it to “be thorough” unless you want six pages. Next fifteen: open the source, recompute one number or check one claim against a file a human already signed, then Slack or walk to the owner. Last ten: write stop, edit, or ship. Ship means you would put your name on it in the QBR. Checking agent work is the same last block when the artifact came from a loop instead of a single chat.
Paste this into the note and fill it every week. Same 45 minutes. Different file.
Weekly 45-min AI practice (one artifact)
Date:
Artifact (deck / metric / email / agent output):
Owner who has to live with this:
Question in one sentence:
Model used (ChatGPT / Claude / Gemini / Grok):
What the model drafted (six lines max in this box):
Source I opened (file, query, or memo):
Number or claim I recomputed:
Person I talked to, and their yes/no:
Stop / edit / ship:
What I will not let the model own next time:
Chat title to keep (or to ignore):
What that checklist does: it forces the right column of the table before you close the laptop. A filled row from Marcus’s Tuesday would read: artifact = QBR deck, owner = Gita, question = which Net Retention is the closed book, model = ChatGPT, source = finance_metric_pack_q2.pdf, number = 97% not 118%, person = Gita yes, decision = stop (pull 11 slides). The last line, “what I will not let the model own,” would be “the definition.”
Common mistakes
- Asking a model to write the definitions before anyone wrote the question.
- Pasting the reply into the QBR folder with a filename that looks official.
- Checking 118% by asking the same chat “does this look right.”
- Skipping Gita because the table was pretty and the intern was thorough.
- Spending the week on future-of-work threads instead of one live artifact.
- Letting an agent fill 11 slides on watch mode, then calling that an approval.
- Keeping 2.100 days because extra decimals felt precise.
How to practice this week
Run the 45-minute plan once on a file that already exists. Fill every line of the checklist, including stop / edit / ship. If you manage an intern, put the closed-book PDF in the shared folder on Friday and require a named owner on any metric that will be spoken in a meeting. Next reading if the prompt is the weak step: Prompting for everyone. If the weak step is an agent you walked away from too early: AI agents for everyone. This series ends here. The rest of the catalog is on Learn.
Quick recap
- Plan the week around tasks and definitions, not around a viral jobs-gone percentage.
- Keep five skills: question, number check, conversation, taste, stop.
- Models draft. You own the closed book and the pull.
- 118% vs 97% two days before a QBR is the failure mode. Pull the slides.
- One 45-minute practice, one artifact, stop / edit / ship written down.
Sources
- ILO: How might generative AI impact different occupations? (task scores inside jobs; transformation more likely than a clean wipe; exposure is not actual impact)
- OECD Employment Outlook 2023: Artificial intelligence and jobs (little evidence, at the time of that edition, of large negative employment effects; task reorganisation showed up first)
- NIST: AI Risk Management Framework (voluntary; human oversight and roles when people and models share a workflow)
- OpenAI: Safety best practices, Human in the loop (review outputs before they are used in practice; give the reviewer the original notes)
- Analytics Made Simple: Learn (paths after Phase P)
- AMS: Prompting for everyone and AMS: AI agents for everyone (the typing and the watch-approve ladder this part sits on)
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.
Merch on Etsy
Open store → Boxplot Mouse Pad, Data Science Mouse Pad, Analytics Mouse Pad, Box Plot, Whisker Plot
View on Etsy →
 Naive Bayes Mouse Pad, Data Science Mouse Pad, Analytics Mouse Pad, Bayesian Mouse Pad
View on Etsy →
 Dashboard to Excel Ceramic Coffee Mug
View on Etsy →
 You're On Mute White Ceramic Coffee Mug, Data Science Mug, Data Mug, Analytics Mug, Statistics Mug, Programming Mug, Gift Mug, Coffee Mug
View on Etsy →