
Leadership rarely wants every order line item on a slide. They want totals, averages, counts, and “by region” breakdowns. That shift from many rows to a few summary rows is aggregation. If SELECT queries are how you read, aggregate functions are how you brief.
This tutorial covers aggregate functions and grouping logic for our SQL series on Analytics Made Simple. We cover COUNT, SUM, AVG, MIN, and MAX, then GROUP BY, and the important distinction between WHERE and HAVING. Our practice datasets remain customers and orders. Hub: SQL series.
What you will learn
- What aggregate functions do to a set of rows.
- How
COUNT,SUM,AVG,MIN, andMAXanswer different metric questions. - How
GROUP BYsplits rows into buckets before aggregating. - How row-level
WHEREconditions filter rows before grouping. - How post-aggregation
HAVINGconditions filter groups after aggregation. - Common grain mistakes that inflate or deflate totals.
From rows to metrics
An aggregate function takes many values and returns one. Without a GROUP BY clause, it collapses the whole filtered table into a single summary row. With a GROUP BY clause, it returns one summary row per group.

| Function | Plain English | Typical use |
|---|---|---|
COUNT(*) | How many rows | Order volume, event counts |
COUNT(col) | How many non-null values in col | Filled emails, complete fields |
SUM(col) | Add numbers | Revenue, quantity |
AVG(col) | Average of non-null numbers | Average order value |
MIN(col) / MAX(col) | Smallest / largest | First date, biggest order |
Whole-table aggregates
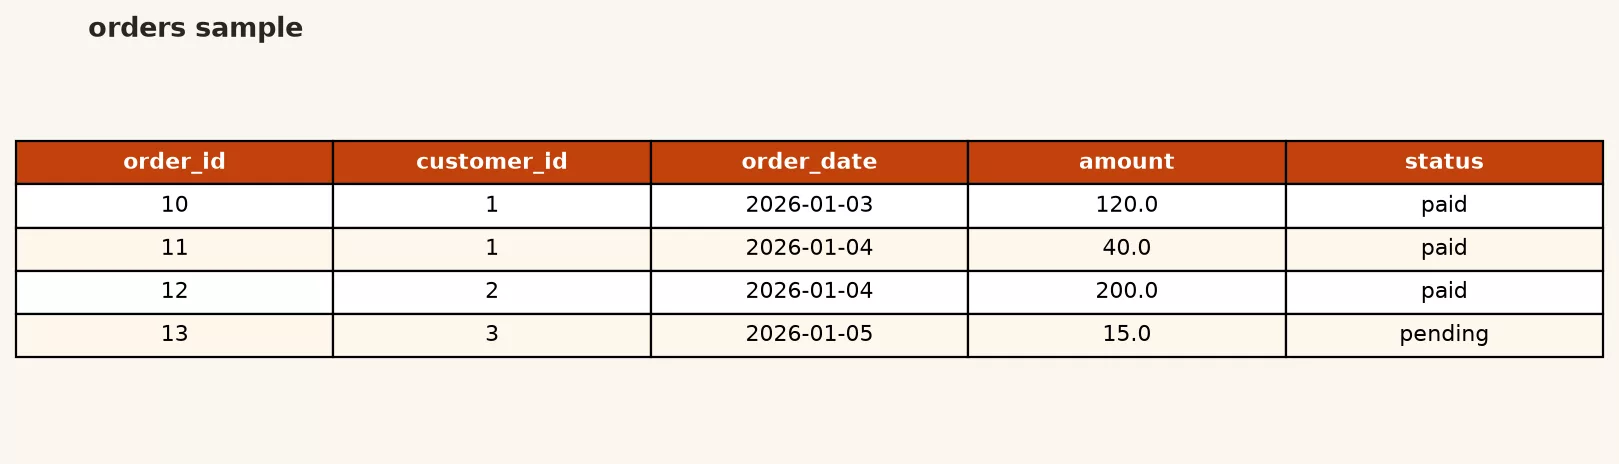
How many orders?
SELECT
  COUNT(*) AS order_count
FROM orders;
Total amount across all orders (including pending and cancelled, so be careful in real life):
SELECT
  SUM(amount) AS total_amount
FROM orders;
A more realistic business question filters for paid orders only.
SELECT
  COUNT(*) AS paid_orders,
  SUM(amount) AS paid_revenue,
  AVG(amount) AS avg_paid_order,
  MIN(amount) AS min_paid_order,
  MAX(amount) AS max_paid_order
FROM orders
WHERE status = 'paid';
Notice that the row filter still executes first before grouping occurs. You are not averaging cancelled noise unless you choose to.
COUNT(*) vs COUNT(column)
The COUNT(*) function counts total rows, whereas COUNT(email) counts only rows with non-null values. On customers:
SELECT
  COUNT(*) AS customers,
  COUNT(email) AS customers_with_email
FROM customers;
If those numbers differ, you just measured incompleteness. That is a quality signal as much as a SQL trick. Pair with data quality when the gap matters operationally.
COUNT(DISTINCT ...)
Unique customers who placed a paid order:
SELECT
  COUNT(DISTINCT customer_id) AS paid_customers
FROM orders
WHERE status = 'paid';
Different from counting paid order rows. One customer can place many orders. Always match the function to the grain the stakeholder meant.
GROUP BY: one summary per bucket
GROUP BY splits rows into groups that share the same values in the grouping columns, then aggregates each group.
SELECT
  status,
  COUNT(*) AS order_count,
  SUM(amount) AS total_amount
FROM orders
GROUP BY status
ORDER BY status;
Example output:

Rules of thumb:
- Every non-aggregated column in the
SELECTlist should appear inGROUP BY(strict engines enforce this). - Alias the aggregates so results are readable.
- Apply an
ORDER BYclause after you know the group grain.
Revenue by customer (paid only):
SELECT
  customer_id,
  COUNT(*) AS paid_orders,
  SUM(amount) AS paid_revenue
FROM orders
WHERE status = 'paid'
GROUP BY customer_id
ORDER BY paid_revenue DESC;
The WHERE clause removes non-paid rows before grouping. Each remaining row belongs to a customer bucket. The sum function then calculates the cumulative order amounts inside each bucket.
HAVING vs WHERE
This is the concept people mix up for months. Memorize the timing:
- The
WHEREclause filters rows before groups form. - The
HAVINGclause filters groups after aggregates compute.
Example: paid orders only, then keep customers whose paid revenue is at least 100.
SELECT
  customer_id,
  SUM(amount) AS paid_revenue
FROM orders
WHERE status = 'paid'
GROUP BY customer_id
HAVING SUM(amount) >= 100
ORDER BY paid_revenue DESC;
You cannot put SUM(amount) >= 100 in WHERE in standard SQL, because the sum does not exist yet at row-filter time. You cannot put status = 'paid' only in HAVING if you meant to exclude rows before summing, unless you like writing awkward conditional aggregates. Keep row predicates in WHERE and group predicates in HAVING.
Another HAVING example: statuses with at least two orders.
SELECT
  status,
  COUNT(*) AS order_count
FROM orders
GROUP BY status
HAVING COUNT(*) >= 2
ORDER BY order_count DESC;
Worked example: weekly-style summary
Ask: “For paid orders, show order count, revenue, and average order value overall, then break down by status across all orders for ops.”
Overall paid snapshot:
SELECT
  COUNT(*) AS paid_orders,
  SUM(amount) AS paid_revenue,
  AVG(amount) AS avg_order_value
FROM orders
WHERE status = 'paid';
Ops breakdown by status (all statuses):
SELECT
  status,
  COUNT(*) AS orders,
  SUM(amount) AS amount_sum,
  AVG(amount) AS amount_avg
FROM orders
GROUP BY status
ORDER BY amount_sum DESC;
Example output:
If someone asks for “customers with more than one paid order,” combine COUNT and HAVING:
SELECT
  customer_id,
  COUNT(*) AS paid_orders
FROM orders
WHERE status = 'paid'
GROUP BY customer_id
HAVING COUNT(*) > 1
ORDER BY paid_orders DESC, customer_id;
That is a retention-flavored list from a tiny schema. In production you would add date windows and definitions. The SQL shape stays the same.
Grain warnings (read these twice)
- Summing after a bad join doubles revenue. Our upcoming joins guide will show row fanout explosions. If a total looks “too healthy,” check join fanout before you celebrate.
- Averaging averages across groups is not the same as a weighted overall average. Prefer explicit sum divided by count at the right grain when precision matters.
- Null values in
AVG()calculations are automatically skipped. If missing amounts should count as zero, you must decide that explicitly with coalescing patterns later. - Mixing metrics of different grains on one slide without labels confuses everyone. “Orders” and “customers” are not interchangeable nouns.
Light bridge to later parts
GROUP BY on one table is step one. Real regional revenue needs a join to customer region in our joins tutorial. Complex multi-step summaries get clearer with common table expressions in our advanced techniques guide. Until then, keep queries short and names honest.
When you pull aggregates into notebooks for charts, the Python series helps. When spreadsheet pivots are still enough, that is fine; see spreadsheets to data. Site map: Learn.
Reading a metric definition before you code
Most aggregation bugs are definition bugs. Before you open the editor, write one sentence with four parts:
- Who or what is the unit? Orders, customers, sessions, invoices.
- What is included? Paid only, shipped only, excluding internal test accounts.
- What is the time window? Calendar month, rolling 28 days, fiscal period.
- What number do we show? Count, distinct count, sum, average, min, max.
Example: “Count distinct customers with at least one paid order in January 2026.” That forces COUNT(DISTINCT customer_id), a paid filter, and a date filter. It is not COUNT(*) on orders, and it is not “customers who exist in the customers table.” Stakeholders often say “active customers” and mean three different things by lunch. Your job is to pin the sentence, then map it to SQL.
When the sentence needs a dimension like region, you either join tables in our joins tutorial or you use a denormalized column if your warehouse already provides it. Do not invent region on the orders table in your head if it is not there.
A second worked path: funnel-ish counts
Ops asks for a simple status funnel on the toy orders: how many pending, paid, and cancelled, plus paid revenue. You can answer with one GROUP BY clause, then optionally a paid-only summary for money.
SELECT
  status,
  COUNT(*) AS orders,
  SUM(amount) AS amount_sum
FROM orders
GROUP BY status
ORDER BY
  CASE status
    WHEN 'pending' THEN 1
    WHEN 'paid' THEN 2
    WHEN 'cancelled' THEN 3
    ELSE 4
  END;
The CASE expression in the ORDER BY clause is optional polish so the funnel reads in a business order instead of alphabetical. Not every engine needs it; readability is the point. Then a paid money line:
SELECT
  SUM(amount) AS paid_revenue
FROM orders
WHERE status = 'paid';
If paid revenue from the second query does not match the paid row’s amount_sum from the first, you made a typo. Reconcile before you paste into a deck. That habit scales to warehouse work where dashboards disagree by millions.
Common mistakes
- Selecting a non-grouped column without aggregating it. Database engines will either throw a syntax error or select an arbitrary row value, which produces unreliable reporting.
- Placing aggregate conditions in the
WHEREclause instead ofHAVING. You cannot filter grouped totals inside a pre-aggregationWHEREclause; use an explicitHAVINGclause instead. - Placing row-level conditions exclusively in the
HAVINGclause. Always useWHEREfor filtering individual rows before grouping, which is both clearer to read and significantly faster. - Counting the wrong thing.
COUNT(*)vsCOUNT(DISTINCT customer_id)changes the story. - Forgetting to filter status before summing “revenue.”.
- Ordering by a column not in the result in engines that disallow it. Order by aliases or group keys you selected.
Practice
- Compute paid revenue, paid order count, and average paid amount.
- Group by status using
COUNTandSUMto review categories. GROUP BY customer_idfor paid orders;HAVINGfor customers over a revenue threshold you choose.- Compare
COUNT(*)andCOUNT(email)on customers. - Write one wrong query on purpose (aggregate in
WHERE) and read the error. These early syntax errors are valuable learning opportunities. - Translate two real workplace metrics into: grain, filter, group key, aggregate function.
Quick recap
- Aggregates collapse many values into metrics:
COUNT,SUM,AVG,MIN, andMAX. GROUP BYcomputes those metrics per bucket.WHEREfilters rows before grouping;HAVINGfilters groups after.COUNT(*),COUNT(col), andCOUNT(DISTINCT col)answer different questions.- Match metric grain to business language before you format the slide.
- Watch joins later; fanout breaks sums even when syntax is perfect.
Next: join tables so region and revenue can live in one result without copy-paste. We explore inner and left joins, keys, and row-count explosions in our upcoming joins guide.
FAQ: aggregates under pressure
Why does my average not match the spreadsheet?
Common causes: different filters, null values skipped by AVG() while the sheet treated blanks as zero, or the sheet averaged daily averages instead of a weighted overall average. Rebuild both sides from the same filtered row set. Prefer SUM(amount) * 1.0 / COUNT(*) when you need to control the denominator explicitly (and still be careful with null amounts).
Can I group by a column alias?
Different database engines handle missing values slightly differently. Some allow grouping by column aliases or select-list position; others require repeating the expression or source column. Portable habit: group by the underlying columns or expressions, and alias only for the output label. When in doubt, repeat the expression. Clarity beats cleverness in shared queries.
When do I use HAVING instead of filtering in an outer query?
The HAVING clause is the direct tool when the condition is about the aggregate of a group inside the same SELECT statement. An outer query around a grouped subquery can do the same job and is sometimes easier to read for multi-step logic. Our subqueries guide covers nested logic more fully. In this tutorial, master HAVING for thresholds like “revenue at least 100” or “more than one order.”
Is COUNT(*) slow?
On huge tables, exact counts can be expensive, and approximate counts may exist in warehouse products. For learning and for most departmental tables, COUNT(*) is fine. Optimize later with indexes, better filters, and query optimization best practices. Do not avoid the metric you need because of premature fear; measure first on your real engine.
Sources
Aggregate and grouping references:
- SQLite: aggregate functions
- SQLite: Grouping reference (grouping and having)
- PostgreSQL tutorial: aggregate functions
- PostgreSQL: Grouping and having documentation
- Analytics Made Simple: SQL series
- Analytics Made Simple: Learn
- Analytics Made Simple: Data quality series
- Analytics Made Simple: Python series
- Analytics Made Simple: Spreadsheets to data
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.



