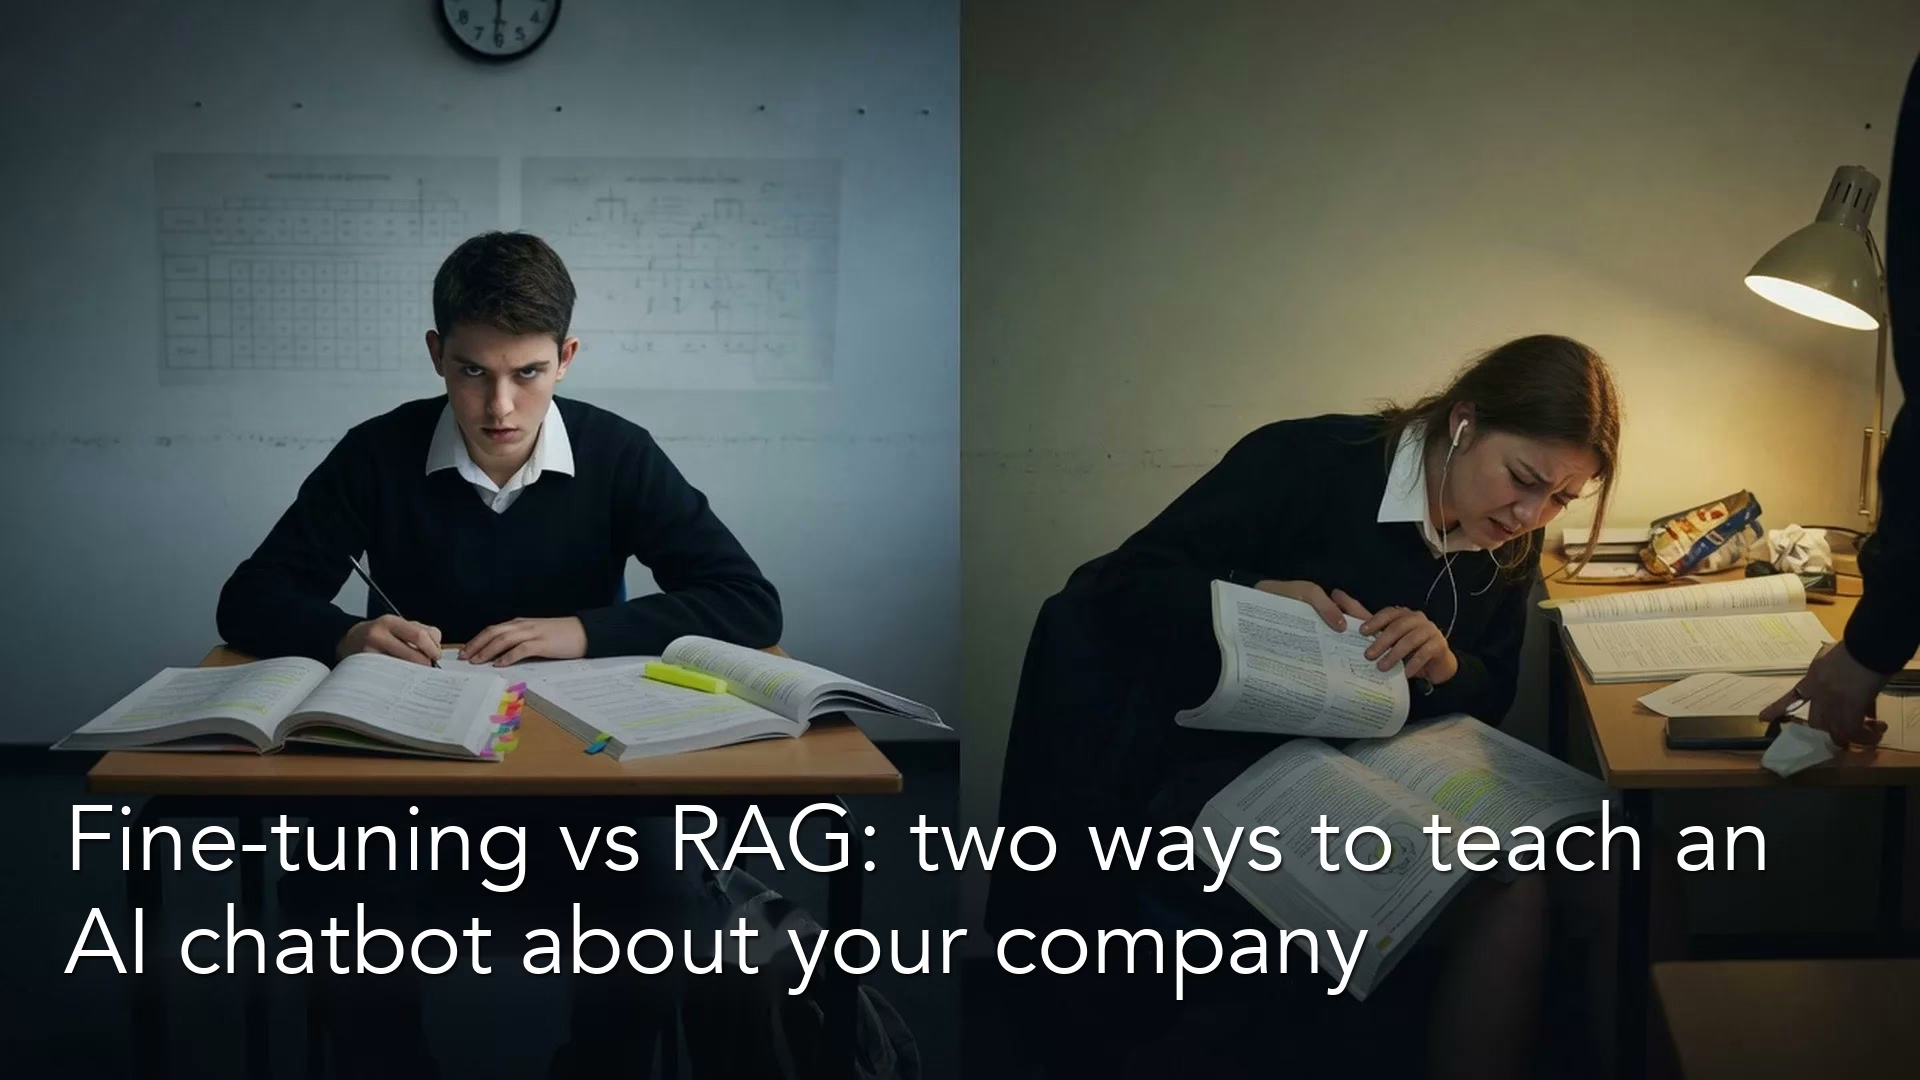
Fine-tuning and retrieval-augmented generation (RAG) are two different ways to make an AI chatbot useful for your company. Fine-tuning teaches the model new habits by training it on examples. RAG looks up your documents at the moment someone asks a question and hands them to the model. For most “know our business” chatbots, curated retrieval is a better first move than a fine-tune, mostly because your documents change and a trained model does not.
Say your manager asks you for a chatbot that answers questions about your company’s policies, and the policies change every quarter. Picture two students facing an exam. Fine-tuning is the student who studied for weeks and now answers from memory, which is fast but frozen at the last day of studying. RAG is the student who is allowed to open the binder for each question, so the answer is only as good as the binder and the student’s skill at finding the right page.
Leadership wants the chatbot to “know our business.” One team wants to fine-tune on last year’s support tickets, and another wants to index the wiki so the bot can search it. Both ideas can help, but they solve different jobs, and the budget meeting goes better when everyone can say which job is which.
Two different jobs
Fine-tuning
Fine-tuning means you keep training an existing model on examples you provide, so its behavior shifts. Some methods retrain the whole model, and cheaper ones train a small add-on layer called an adapter. A typical lesson is “given this ticket, produce this exact structured output” or “rewrite this in our support voice.” The new behavior is then built into the model files you deploy. Because of that, updating a fact means preparing new training data and running another training job, so a fine-tuned model works nothing like a live wiki.
RAG
RAG retrieves the passages that match a question from your own collection of documents, then asks the model to answer using those passages plus the question. If someone edits a Confluence page and you refresh the search index, the next answer can use the change without any retraining. The failures move to the lookup step. The system may fetch the wrong chunk of text, work from a stale index, skip a document the user is not allowed to see, or blend two sources that disagree.
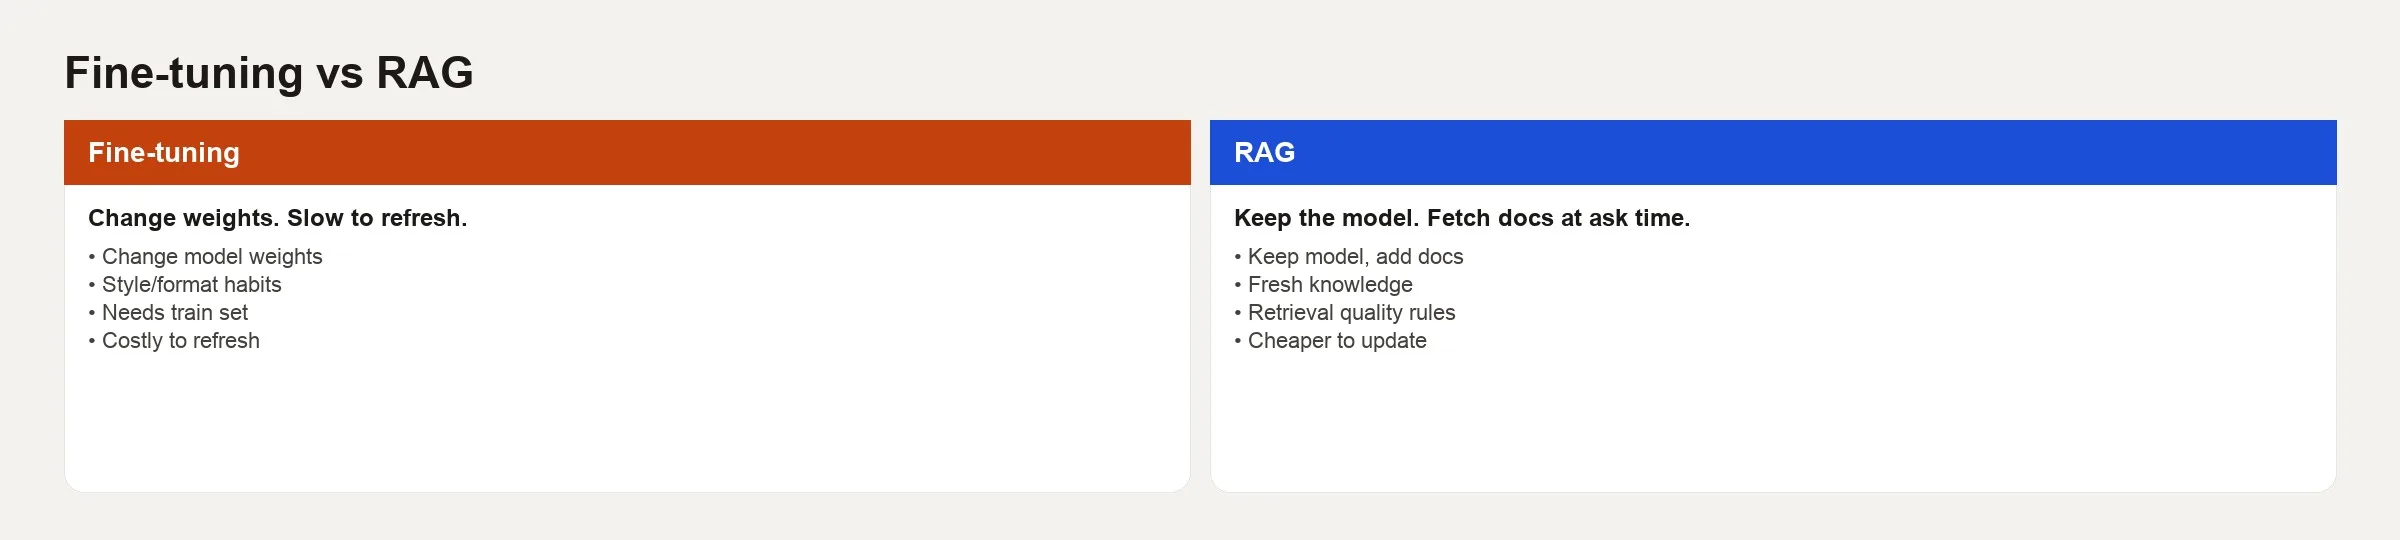
Rule of thumb: If you need the model to speak or format differently, consider fine-tuning, though a stronger prompt is worth trying first. If you need it to use today’s internal facts and show where they came from, start with RAG.
Comparison that survives a budget meeting
| Dimension | Fine-tuning | RAG |
|---|---|---|
| Primary win | Behavior, style, task skill, reliable output format | Answers grounded in outside or current documents |
| Fact freshness | As fresh as the last training set | As fresh as the search index and its sources |
| Upfront cost | Labeling examples, training compute, a test harness | Loading documents, splitting them into chunks, building the index, testing retrieval |
| Runtime cost | Often shorter prompts, and the model may be specialized | A lookup step plus longer prompts that carry the retrieved text |
| Citations | Weak unless you still retrieve or hardcode them | A natural fit, because you can show the retrieved sources |
| Best early bet for internal Q&A | Usually not | Usually yes (Amazon Web Services and others recommend starting with RAG for questions about your own documents) |
| Failure mode | Confident, outdated knowledge, or overfitting to noisy labels | Wrong neighbors, prompts stuffed with too much text, or fluent answers built on bad chunks |
Google Cloud’s guidance on using your data with large language models frames it the same way. RAG grounds answers in your data at the moment of the question, and supervised fine-tuning teaches a well-defined task. They are different dials with different upkeep schedules.
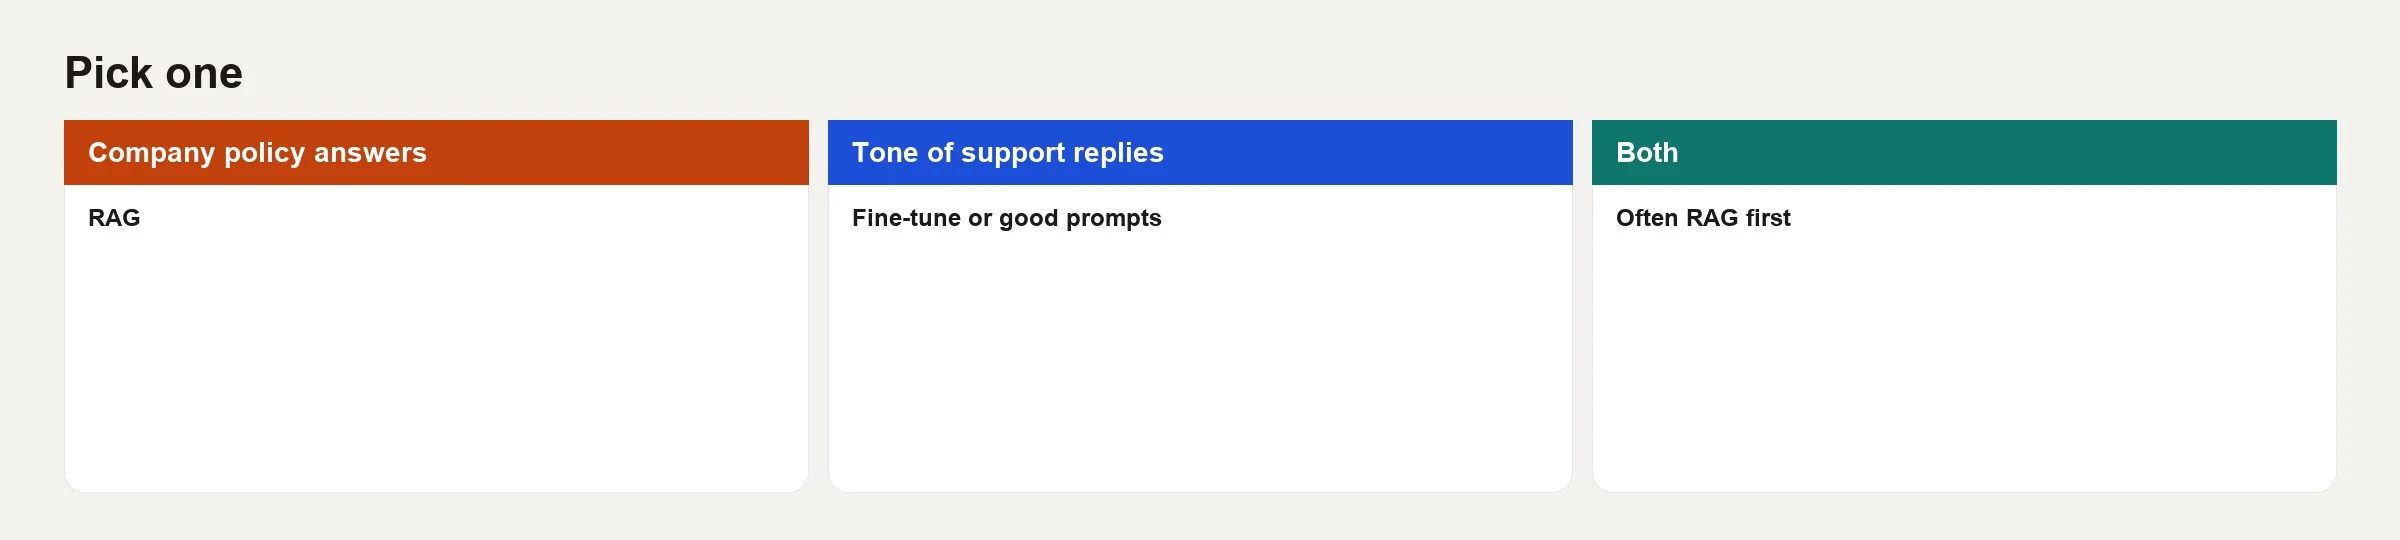
When RAG is the better first move
RAG tends to win in these situations, and most business chatbots fall into at least two of them:
- You are answering questions about policies, runbooks, and metric definitions.
- Your documents change weekly, and leadership expects the bot to notice.
- You need an audit trail that shows which paragraph the model was given.
- You have a wiki but no clean, large set of labeled examples to train on.
- You have several source systems, and permissions must decide what each user can retrieve.
RAG still fails when the wiki is a mess. Retrieval cannot invent one approved definition of “active customer” out of three pages that disagree. Fix the documents and decide who owns them first, then retrieve from them.
When fine-tuning earns its keep
Fine-tuning pays off when the problem is how the model behaves and not what it knows:
- Your app must parse a strict output format such as JSON (a plain-text format programs use to pass structured data), and prompting has stopped improving results.
- A house writing style has to hold across thousands of generated answers.
- Domain jargon and task patterns keep getting mangled by the base model.
- Offline tests show that classification or extraction quality needs the model’s weights (the learned numbers inside the model) to change.
- Cost or delay rules out stuffing a huge block of retrieved text into every call.
Fine-tuning is a poor way to make a model memorize the March refund policy, because policies belong in retrieval or in a lookup tool. It is also a poor way to teach private facts that you would not be willing to put into training data under a clear approval process.
Combining them without turning it into a science fair
A common pattern is to fine-tune, or lean heavily on prompt writing, for format and tone, and use RAG for facts. Some teams try retrieval-augmented fine-tuning variants, but you do not need that name to use the idea. Keep the system diagram boring, with four steps:
- Retrieve the top matching chunks, applying filters for who may see what.
- Build a prompt that keeps three things separate: your instructions, the retrieved evidence, and the user’s question.
- Generate the answer with a model that is either a base model with good instructions or one fine-tuned for your format and voice.
- Test it against a golden set, meaning a fixed list of questions with known good answers. Check that answers stay faithful to the sources, that the bot declines when nothing relevant is found, and that the output format is valid.
Tool calling sits next to both approaches. That means letting the model run a warehouse query (a written request for data from a database) or call a metrics service instead of guessing. For analytics numbers, prefer tools over free-text memory, whether the model was tuned or is retrieving.
Worked scenarios
Scenario 1: an internal policy assistant
Suppose you need to answer “How do refunds work for EU annual plans?” with links to the current policy. The better first approach is RAG over the approved policy pages, with access filters and citations. You would fine-tune later only if a workflow (the series of steps you follow) engine needs a fixed answer format and prompting fails to deliver it. What you should not do is fine-tune on a ZIP (a compressed bundle of files) of PDFs and skip retrieval, because then you will wonder why June’s policy never shows up.
Scenario 2: drafting ticket replies
Here you need replies in a calm company voice, with a greeting, steps, and a closing. Start with strong system prompts and a few example replies, and consider a fine-tune only if the volume and your tests justify it. RAG still has a role, which is pulling the right troubleshooting snippet for the product area so the steps stay accurate. The voice comes from the tune or the prompt, and the facts come from retrieval.
Scenario 3: an analytics SQL helper
Say you want to help analysts write SQL (the query language for databases) against your warehouse. Fine-tuning on pairs of questions and queries can help with your dialect and style, and RAG over table documentation and metric cards can help the model name the right columns. Neither replaces a dry run of the query, a check that each row means what you think it means, or a human review. Publish a checklist instead of promising an “AI database administrator” that works on vibes. For the checking habits, see how to check AI-written SQL and the SQL series.
-- Decision pseudocode for a new "know our business" request
if need_current_internal_facts or citations:
    build_rag(sources=approved_corpus, filters=acl, evals=faithfulness)
if need_strict_format or stable_voice and prompting_plateaued:
    consider_fine_tune(task_examples, evals=schema_and_quality)
if need_exact_numbers_from_warehouse:
    prefer_tools(sql_or_metric_api)  # not free-text memory
always:
    human_review_for_high_stakes
    monitor_and_golden_set()
Data and governance differences
Fine-tuning data is training data, so it raises questions about labels, licenses, scrubbing personal information, how long you keep it, and whether it may ever leave your private network. RAG data is a working collection of documents, so the questions are about access control at lookup time, redaction, and keeping the index clean. Both need owners. A fine-tune freezes a snapshot of behavior, while RAG freezes whatever you forgot to delete from the index. The incidents look different, but both call for the same stewardship habits you would use for any data quality work.
Security deserves a note here. Prompt injection means hiding instructions inside text that the model will read, and it is a bigger worry for RAG and for agents that use tools, because retrieved text is untrusted. Fine-tuned models can still be steered by a malicious user prompt as well. Neither approach is safe by design, so add filters and a human escalation step for any high-impact action.
Common mistakes
- Fine-tuning to avoid building search over messy documents. You will end up retraining forever.
- Running RAG without tests and celebrating on demo day, right up until the first confident wrong policy answer.
- Retrieving prose about metrics instead of querying the warehouse for numbers that must match what Finance reports.
- Skipping a prompt baseline before fine-tuning. Many tuning requests disappear after a better system prompt (the hidden standing instructions a chatbot gets before your question).
- Mixing unvetted sources in one index, such as HR drafts next to customer help pages, without filters.
- Having no rollback plan for a bad fine-tune or for a poisoned document that ranked first all week.
- Declaring victory on fluency instead of on how often the task actually succeeds.
How to practice
- Write one paragraph for your vice president that explains fine-tuning versus RAG with the student and open-book comparison. No product names are needed.
- Inventory one AI pilot. Label each requirement as behavior, fact freshness, citation, or exact number from a tool. Then map each one to a prompt, RAG, a fine-tune, or a direct API (the way one program asks another for data) call.
- Build a 20-question golden set for any internal Q&A bot. Score retrieval hit rate and answer faithfulness separately, so you know which step is failing.
- Try to solve a format problem with prompts and examples first. Only then sketch what the fine-tuning data would look like.
- Read one vendor comparison, such as the Amazon Web Services page on RAG versus fine-tuning or Google’s tuning guide, and note where your use case sits. Link it in your design doc.
Quick recap
- Fine-tuning changes how the model behaves, while RAG supplies outside text at the moment of the question.
- Internal fact Q&A usually starts with RAG, and style or hard task formats may justify fine-tuning once prompts stop improving.
- Freshness, citations, and upkeep schedules differ, so budget for the one you choose.
- Combine them carefully: retrieve facts, tune or prompt for form, and use tools for exact numbers.
- Tests, permissions, and clear ownership of sources matter more than architectural fashion.
When someone says “we should fine-tune so it knows our data,” translate it into a question: should we change the model’s weights, retrieve documents, call tools, or clean up the wiki? That translation is the whole job of this Key Term.
Your next step
Pick one assistant your team wants and answer two questions from this post: do the facts change often, and is the problem facts or format? If facts change, start with RAG. If the problem is format or style after good prompts, consider fine-tuning. Writing the answer down keeps the project from drifting.
Series notes
This pairs with RAG explained in plain English in the Practical AI series. Use both as decision aids, not as science-fair trophies.
Sources
Further reading and references used for this article:
- Amazon Web Services Prescriptive Guidance, comparing RAG and fine-tuning: https://docs.aws.amazon.com/prescriptive-guidance/latest/retrieval-augmented-generation-options/rag-vs-fine-tuning.html
- Google Cloud, “To tune or not to tune?” (RAG vs supervised fine-tuning): https://cloud.google.com/blog/products/ai-machine-learning/to-tune-or-not-to-tune-a-guide-to-using-your-data-with-llms
- Oracle overview of RAG vs fine-tuning: https://www.oracle.com/artificial-intelligence/generative-ai/retrieval-augmented-generation-rag/rag-fine-tuning/
- Analytics Made Simple: Practical AI series, What are LLMs?, Vector databases, How to check AI-written SQL, Learn
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.