
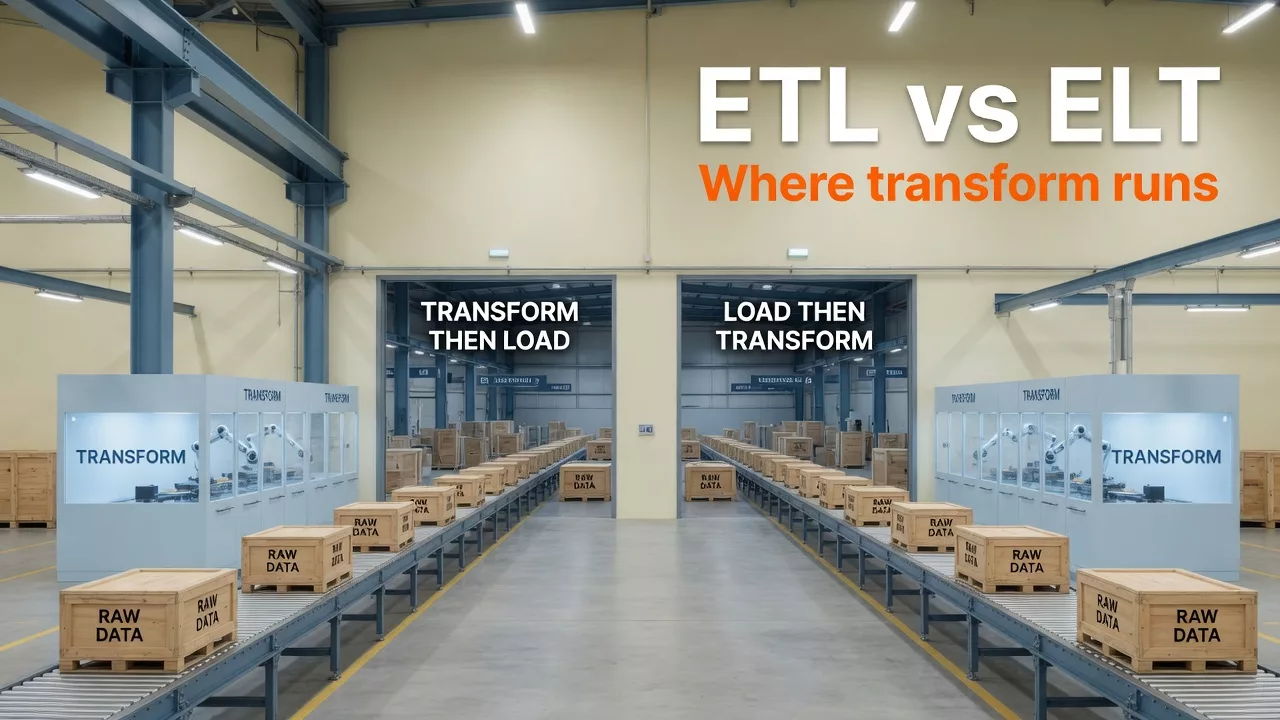
ETL and ELT are two orders for the same three steps of moving data: extract it from a source, transform (clean and reshape) it, and load it into your warehouse, the central database your company reports from. ETL cleans the data before loading it; ELT loads raw data first and cleans it inside the warehouse. What matters is where the cleanup runs, which copy you trust, and how you recover when a source sends bad data.
Imagine you open a report one morning and yesterday’s orders are missing. Someone asks whether the job is ETL or ELT, as if the name would fix it. The useful questions are where the cleanup step failed and whether the raw data was kept so you can run it again.
This guide compares the two in plain language, covers related patterns such as copying only changed records, and ends with a checklist for choosing. Related: storage options and governance.
What you’ll learn
- ETL vs ELT with a simple diagram.
- When each architectural pattern still wins in production.
- How change data capture (CDC) and other integration patterns fit.
- Pragmatic best practices that survive daily production demands.
- A checklist for choosing an approach.

ETL: extract, transform, load
Classic ETL extracts from sources, transforms in a dedicated engine or middle tier, then loads curated results into a target. Common when targets were expensive on-prem warehouses and you wanted to load only clean, slim tables.
Strengths: heavy cleansing before landing; strict control of what enters a sensitive target; mature enterprise tooling in regulated environments. Costs: middle-tier complexity; slower iteration if every change needs a specialist tool; raw history may not be retained.
ELT: extract, load, transform
ELT loads raw or lightly staged data into a powerful warehouse first, then transforms with SQL (often dbt) inside that platform. Cloud warehouses made this popular because storage is cheap and SQL engines scale.
Strengths: faster iteration for analytics engineers; raw data available for reprocessing; transforms versioned as code. Costs: need good warehouse governance and cost control; easy to create junk schemas if ownership is weak; some PII (personal information that can identify someone, like a name or email) may land before masking unless you plan carefully.
Side-by-side
| Topic | ETL | ELT |
|---|---|---|
| Transform location | Before / outside warehouse | Inside warehouse |
| Raw retention | Often limited | Usually kept in stages |
| Iteration speed | Can be slower | Often faster for SQL teams |
| Best classic fit | Strict curated loads | Cloud analytics stacks |
| Main risk | Opaque middle tier | Messy ungoverned raw zones |
When to prefer which
- Prefer ELT for cloud analytics with strong SQL skills and dbt-like workflows.
- Prefer ETL-like shaping when you must minimize raw PII landing or feed constrained legacy targets.
- Hybrid is normal: light redact on the way in, heavy modeling after load.
Related patterns
CDC (change data capture)
Streams inserts/updates/deletes from source logs so you do not re-extract full tables every time. Great for fresher data and lower source load. Requires careful handling of schema (the layout of the data: which tables and columns exist) changes and deletes.
Replication
Keeps copies in sync for availability or analytics offloading. Not the same as transforming into a dimensional model. A replica of production is still production-shaped.
Virtualization / federation
Run a query, a question written for a database, across several systems without moving the data first. Useful for exploration and some operational patterns. Can hide performance and ownership problems if treated as a free lunch.
Best practices
- Name grains and owners for curated tables, so people know what one row means and whom to ask.
- Keep transforms in version control with tests, so every change can be reviewed and undone.
- Separate raw, staged, and mart layers.
- Monitor freshness, volume, and hard fails.
- Document recovery: replay from raw, not from screenshots.
- Control costs with partitioning, clustering, and query discipline.
Worked story
A team loads Stripe and app database extracts into a warehouse every hour (ELT). dbt models build fct_orders and dim_customer. A test fails when order totals go negative. They fix the model and rebuild without re-pulling every source. That loop is why ELT feels good when raw stages exist.
Another team must feed a legacy finance system that only accepts a fixed file layout with masked fields. They shape the file in a controlled transform step before load (ETL-style). Different constraint, different pattern.
Tooling notes (not ads)
You will see Informatica, Talend, Fivetran-style extractors, Airbyte, cloud glue services, Airflow/Dagster orchestration (the tool that schedules jobs and runs them in the right order), and dbt-style transformers. Buy for the bottleneck you have: extraction reliability, orchestration, or modeling discipline. Tools do not replace ownership.
Decision checklist
- Where must PII be masked?
- How fresh does the data need to be?
- Who will write and test transforms?
- Do we need raw replay?
- What does failure look like and who is paged?
- What is the cost model of our warehouse?
Quick recap
- ETL transforms before load; ELT transforms after load.
- Cloud analytics often lean ELT; constraints can require ETL-style shaping.
- CDC, replication, and federation are cousins, not synonyms.
- Version and test transforms; monitor freshness.
- Choose by constraints and skills, not acronym fashion.
A good first step this week: pick one data feed your team relies on and write down where its cleanup happens, before loading or inside the warehouse. If nobody can say, that is the gap to fix first.
Sources
- https://www.sas.com/en_us/insights/data-management/what-is-etl.html
- https://docs.aws.amazon.com/prescriptive-guidance/latest/serverless-etl-aws-glue/aws-glue-etl.html
- https://azure.microsoft.com/en-us/products/data-factory
- https://cloud.google.com/data-fusion
- https://www.talend.com/
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.



