
Fake data is often the right choice for demos, training, and vendor sandboxes. Use it when a real copy of your data would put customers on a slide they never agreed to be on.
Say a vendor wants a “realistic” demo setup by Friday. Someone on your team proposes restoring last month’s production backup into a shared sandbox and scrubbing a few columns. That plan does not scrub anything. It copies real people into a room with weaker locks, so more people can see them and fewer rules protect them.
Words that get blurred
People use “synthetic,” “masked,” “anonymized,” and “sample” as if they meant the same thing. They do not, and the table pulls them apart with a warning for each.
| Term | Plain meaning | Watch out |
|---|---|---|
| Sample / subset | Real rows, fewer of them | Still real people and secrets |
| Masked / redacted | Real rows with fields hidden or replaced | Join keys and rare values can re-identify |
| Anonymized | Legal/technical claim that individuals are not identifiable | Hard to achieve; often over-claimed |
| Synthetic | Rows generated by rules or models, not copied from a person | Can still leak patterns or be too fake to test bugs |
| Mock / fixture | Hand-built tiny data for tests | May miss edge cases |
Ethics starts with being honest about which kind you are using. If you call a masked copy of production “synthetic,” you have a paperwork problem today. Later it becomes a compliance problem, because auditors treat the two very differently.
When synthetic or mock data is the ethical choice
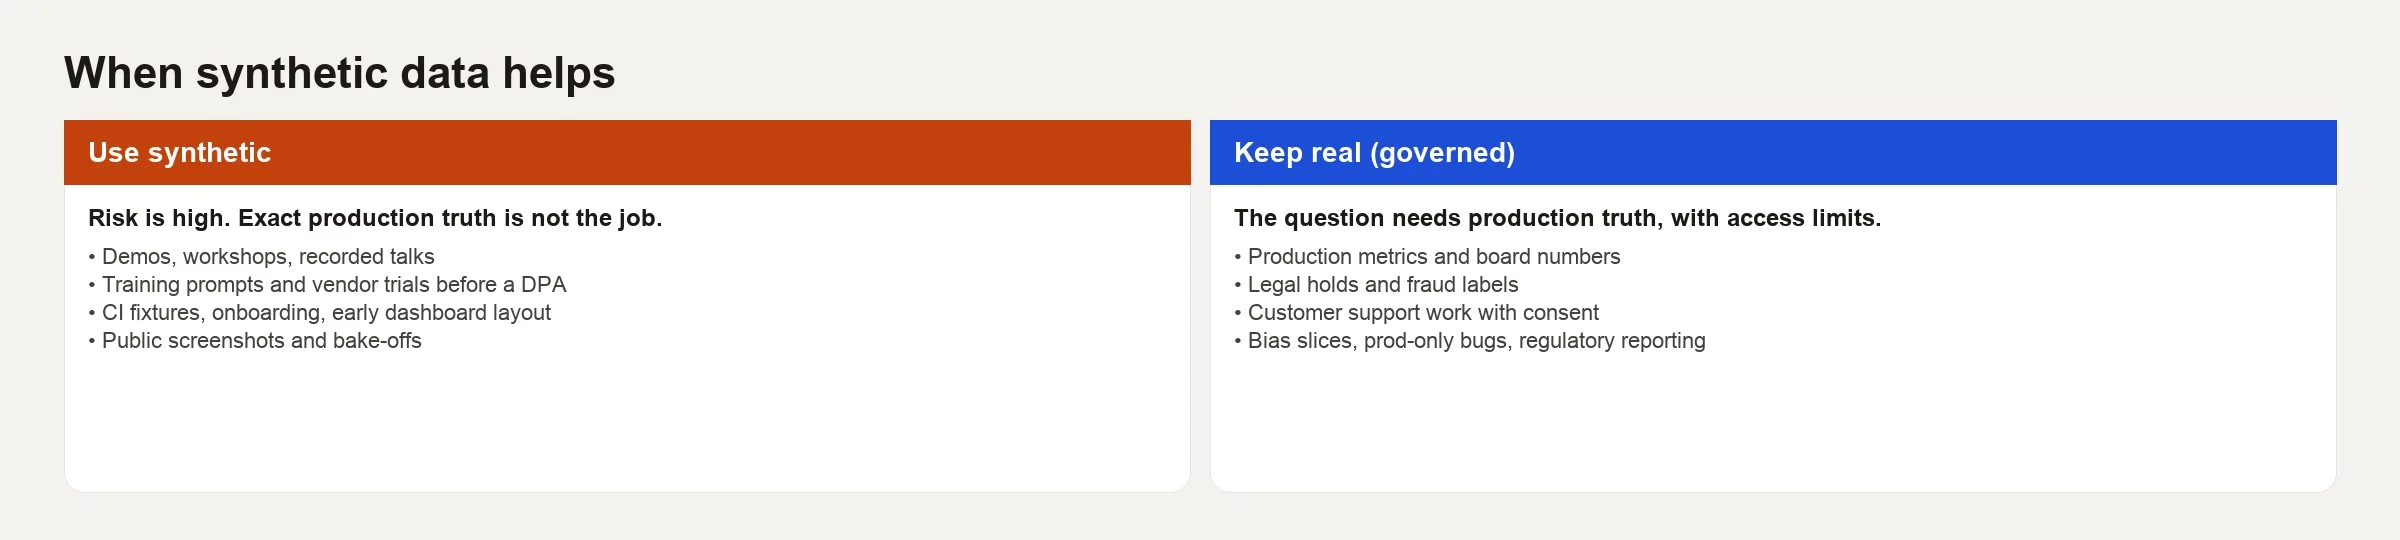
Prefer generated or hand-built data when real rows would travel farther than the people in them expected. Seven situations come up often.
- Teaching and workshops, where screenshots and laptops leave the room.
- Public talks, blog posts, and vendor demos that will be recorded or shared.
- Automated tests, often called continuous integration (CI), that run on shared machines you do not control.
- Early dashboard layout work, where the volume and shape of the data matter more than how columns relate.
- Vendor bake-offs run before a data processing agreement is signed. That agreement is the contract that limits what a vendor may do with your data.
- Prompt and AI agent experiments that might send table samples to an outside model service.
- Onboarding for a new hire who has not yet finished access training.
In these cases, using real people as props has a high moral cost. Using fake data often costs little, as long as you design the fakeness on purpose.
When you still need real data, under governance
Fake data is a poor substitute when the answer depends on real rare events or on the real mess of production. Five situations fit that description.
- Validating a fraud model against real attack patterns.
- Debugging a data quality failure that only happens in production.
- Measuring bias across real groups of people, which needs legal and ethical review.
- Final acceptance testing for a system migration, when only production-sized quirks matter.
- Regulatory reporting that has to reflect actual activity.
In these cases the ethical path is more than “use whatever is convenient.” Take the least access you need and use the data only for the stated purpose. You also keep audit logs, set a limit on how long you keep it, and sometimes get a formal review. Fake data can still help, because you can build and test your setup on fake rows before you touch the real extract.
Ethics is purpose, proportion, and honesty
Three questions clear up more arguments than a slogan does.
- Purpose: what decision or deliverable needs data at all?
- Proportion: what is the least risky data that still serves that purpose?
- Honesty: could anyone mistake this dataset for production truth?
If the purpose is to keep a dashboard from looking empty on stage, fake data is a fair answer. If the purpose is to estimate how much churn will drop for a board number, fake data cannot replace measuring the real thing. Label every output so nobody pastes fake numbers into a real forecast.
How to make synthetic data useful
Start from what one row means, and from the rules
First write down what one row represents. It might be one customer per day, one order line, or one ticket. Then list the hard rules. Each ID must be unique and amounts cannot be negative. Statuses come from a fixed list, and dates must run in order, so a ship date never lands before the order date. Generators that ignore those rules make test data that never fails the way production does, or fails in impossible ways that waste your time.
Match the shape loosely, not perfectly
For demos you want a believable shape. That means a few big customers, many small ones, some seasonal wiggle, and a handful of blank values. You do not need a perfect clone of production. A perfect clone can point back to real people and gives you false confidence, so write down what you chose not to copy.
Include edge cases on purpose
Add empty text next to true blanks, names with accented characters, refunds, same-day cancellations, and leap days if they matter. Add duplicate IDs if production has them, and events that arrive late. Test data that only covers the happy path teaches you to build pipelines that break the first time something odd arrives.
Keep generators in version control
A saved script with a fixed random seed beats a mystery file on someone’s laptop. The seed makes every run produce the same rows, so tests are repeatable. Review the generator like any other code, because it defines what “normal” looks like for everyone who uses it.
Here is a tiny sketch, for illustration only.
import random
from datetime import date, timedelta

random.seed(42)
statuses = ["paid", "paid", "paid", "refunded", "pending"]

def fake_orders(n=1000, start=date(2025, 1, 1)):
    rows = []
    for i in range(1, n + 1):
        order_day = start + timedelta(days=random.randint(0, 180))
        amount = round(max(1.0, random.gauss(48.0, 20.0)), 2)
        rows.append({
            "order_id": i,
            "customer_id": random.randint(1, 200),
            "order_date": order_day.isoformat(),
            "amount_usd": amount,
            "status": random.choice(statuses),
        })
    return rows
That is enough for a workshop on grouping and refund filters. It is not enough to claim “this matches our market,” so put that sentence in a short readme file next to the script.
Worked example: a demo environment for a metrics class
Suppose you want to teach weekly revenue, refund rate, and a cohort chart with no real customers exposed. Your audience is internal analysts plus a few vendor observers, and screenshots may leave the company. So you make four decisions.
- Use fully synthetic customers and orders with a fixed seed.
- Give the environment a made-up brand, a “Northwind-like” demo tenant carrying this site’s name, instead of a real region name.
- Include intentional quality bugs, such as 2% blank
customer_idvalues on a staging-only table, so learners can practice checks. - Ban connecting workshop laptops to production “just for the live demo.”
Next, write a card that records the details. These are the fields worth writing down.
| Field | Example entry |
|---|---|
| Purpose | Workshop screenshots and SQL practice |
| Data class | Synthetic only; no prod subset |
| Generator | repo path + seed 42 |
| Refresh | Rebuild nightly from script |
| Allowed tools | Classroom warehouse schema demo_* |
| Forbidden | Joining demo to real customer dims |
| Labeling | Watermark “SYNTHETIC” on dashboards |
| Owner | Analytics enablement |
| Review | Each quarter or before external demos |
A second, smaller table covers the rules for the fake values themselves.
| Field | Synthetic rule |
|---|---|
| IDs | Fake sequential or hashed, never copied from prod |
| Emails | example.com only |
| Amounts | Plausible ranges, not cloned totals |
| Label in prompt | Say synthetic explicitly so nobody pastes it as truth |
The finished card is what you show security when they ask what is in that demo environment. A paper trail settles the question faster than reassurance does.
Risks of synthetic data
Fake data has some risks of its own, and it helps to know them before you rely on it.
- False confidence: models and dashboards look healthy on toy patterns.
- Leakage through training: a generative model trained on sensitive data can memorize it, so its “synthetic” output may not be safe without care.
- Re-identification through realism: if you inject too many real rare combinations, you have rebuilt the hazard you meant to avoid.
- Policy theater: calling a masked production copy “synthetic” to skip a review.
- Broken links between tables: fake data that cannot join properly is useless for testing the joins that matter.
Standards bodies and privacy researchers agree that anonymizing and faking data both leave some risk behind. Neither gives you a free pass, so write down your assumptions. For high-stakes data such as health, finance, children, or precise location, ask a privacy lawyer first.
Common mistakes
- Restoring production backups into shared sandboxes “temporarily.”
- Masking emails with a pattern but leaving names, phone numbers, and free text intact.
- Using synthetic numbers in real decision meetings without labels.
- Building generators with no seed, no owner, and no documentation.
- Keeping only happy-path test data, which hides blank-value and late-event bugs.
- Joining synthetic facts to real customer tables “for convenience.”
- Assuming a vendor’s “synthetic” export was never trained on your data.
- Skipping the purpose test and generating data when no data was needed.
Practice
Pick one recurring use of production-like data that is not a final business decision. Onboarding, dashboard themes, outside demos, and automated tests all qualify. Write a one-page card that covers the purpose, what one row means, the generator plan, the edge cases, the watermark, and the owner. Build a small generator or a hand-made set and swap it in for the risky path. Then tell the team where the seed lives.
For a second drill, look at one extract that someone called “anonymized.” List every field that could point back to a person. A join with a public dataset is enough to do it. Then decide whether to truly fake it, cut it down further, or keep it under stricter access. Honesty is the skill you are practicing.
Hand-off language that prevents confusion
When you hand a fake dataset to another team, say three things out loud. Say what purpose it serves, what it deliberately does not copy from production, and who to ask before using it for a decision. A one-paragraph readme beats word of mouth. For example: “This tenant is seed 42 synthetic orders for SQL workshops. Distributions are plausible, not calibrated to 2025 revenue. Do not use for board metrics or model validation.” A sentence like that stops more bad slides than a long policy page nobody opens.
If legal or security asks for a data map, list your fake-data environments as full entries with owners and refresh jobs. Hidden demo databases are how “we only use fake data” turns into “wait, who restored that backup?” Keep the same inventory for demo warehouses that you keep for production. The rows may be imaginary, but the risk is not.
Quick recap
- Synthetic, masked, sampled, and anonymized are four different claims.
- Fake data is often the ethical default for teaching, automated tests, demos, and early AI experiments.
- Real data still belongs in governed analysis where truth and rarity matter.
- Purpose, proportion, and honesty beat slogans.
- Useful fake data respects row meaning, rules, edge cases, and versioned generators.
- Label your outputs, own the card, and never join demo facts to real people “just this once.”
Series notes
Related reading on data stewardship and privacy when pasting into chat tools. This post stands alone on fake data ethics.
Sources
- National Institute of Standards and Technology (NIST), Privacy Framework resources: https://www.nist.gov/privacy-framework.
- National Institute of Standards and Technology, AI Risk Management Framework (data and privacy risk context for AI systems): https://www.nist.gov/itl/ai-risk-management-framework.
- UK Information Commissioner’s Office (ICO), anonymisation and synthetic data guidance hub: https://ico.org.uk/for-organisations/uk-gdpr-guidance-and-resources/data-sharing/anonymisation/.
- European Data Protection Supervisor, public materials on anonymisation concepts (see current resources): https://www.edps.europa.eu/data-protection/data-protection/reference-library/anonymisation-pseudonymisation_en.
- Synthetic Data Vault (open-source ecosystem docs for generators; engineering reference, not a legal shield): https://docs.sdv.dev/sdv.
- Analytics Made Simple, Data quality series: https://analyticsmadesimple.com/series/data-quality/.
- Analytics Made Simple, Data stewardship series: https://analyticsmadesimple.com/series/data-stewardship/.
Keep going
Same lessons in your feed
Short diagrams, hooks, and weekly tutorials on Substack, Instagram, X, and Facebook.



